Continuously Updated
Short answer: among models that answer at least 45% of questions correctly, Gemini 4 Carbon (medium) hallucinates least, at 4.2% (not yet publicly available). The best public model is Gemini 4 Argon at 4.3%. No model is hallucination-free.
Last updated November 7, 2026 · 7 benchmarks · 124 models on the AA-Omniscience v1.1 board · 100+ sources · What changed
Lowest hallucination rate, models answering 45%+ correctly
4.2%
Gemini 4 Carbon (medium) Not yet publicly available
Best public model: Gemini 4 Argon, 4.3% [2]
Hallucination rate of the most accurate model
70%
Claude Fable 5.1
68.4% accuracy, the highest in our table [2]
Hallucination rate of OpenAI's top model
49.8%
GPT-6 Astra
61.6% accuracy, AA-Omniscience Index 42.4 [2]
Models that give more wrong answers than right ones
52 of 124
Negative AA-Omniscience Index
AA-Omniscience v1.1 board, November 7, 2026 [2]
Every major AI model hallucinates. Generative AI, by the design of it, cannot be hallucination-free - but the risk can be mitigated before it reaches your decision and costs you money. Suprmind Data Lab publishes the Multi-Model AI Divergence Index, which measures what happens when several AI models answer the same question: how often they contradict and correct each other, and on which questions. See how multi-model verification works as a mitigation strategy.
This page tracks hallucination rates across seven benchmarks, covers every frontier model from Gemini 4 Carbon and Gemini 4 Argon to Claude Opus 5.5 and Fable 5.1 to GPT-6 Astra and GPT-6.1 Sol to Grok 4.7, and presents the data without spin. The numbers don't agree with each other, and we explain why that matters more than any single leaderboard ranking.
Every number below comes from a different benchmark measuring a different aspect of hallucination. Low Vectara + high AA-Omniscience hallucination means the model is good at summarization but bad at admitting ignorance. High FACTS + low AA-Omniscience accuracy means the model is accurate with tools but attempts too many questions. No single column tells the full story. Cross-reference at least two.
Column guide:
Click any column header to sort. The table opens on the 20 models with the highest AA-Omniscience v1.1 Index. Models without a v1.1 record follow, with their final v1 record in grey and marked v1. Use "Show all" for every model.
| Model | Lab | AA accuracy | AA hallucination | AA Index | Vectara (new) | Vectara (orig.) | FACTS | SimpleQA Verified | HalluHard |
|---|---|---|---|---|---|---|---|---|---|
| Gemini 4 Carbon highNot yet publicly available: Google is giving access to a subset of cyber defenders first, then to more trusted partners. High effort, Artificial Analysis's default configuration. At low effort: 49.2% accuracy, 19.8% hallucination, Index 39.2. Not yet publicly available | Google DeepMind | 58.3% | 11.4% | 53.5 | - | - | - | - | - |
| Claude Opus 5.5 maxAA max run with the default fallback model. | Anthropic | 65.5% | 50.3% | 48.1 | 9.9% | - | 66.5 | - | - |
| Gemini 4 Carbon mediumNot yet publicly available. Medium effort: the lowest AA-Omniscience v1.1 hallucination rate of any model in this table that answers at least 45% of questions correctly. Not yet publicly available | Google DeepMind | 48.9% | 4.2% | 46.8 | - | - | - | - | - |
| Claude Fable 5.1 maxAA max run with the default fallback model. | Anthropic | 68.4% | 70.0% | 46.3 | - | - | - | - | - |
| Gemini 4 Argon highAnnounced September 30, 2026 for an initial group of cyber defenders. Public since October 13, 2026 in the paid tier of the Gemini API and in the Gemini app for Google AI Pro and Ultra subscribers. | Google DeepMind | 48.3% | 4.3% | 46.1 | 12.1% | - | 72.4 | 75.6% | - |
| GPT-6 Astra maxAA max run. On AA-Omniscience v1.1 the high setting reads 61.1% accuracy, 42.5% hallucination, Index 44.6. HalluHard on its updated question set, run at medium thinking. | OpenAI | 61.6% | 49.8% | 42.4 | 8.7% | - | 78.1 | 75.8% | 27.2%‡ |
| GPT-6.1 Sol max | OpenAI | 61.8% | 51.9% | 42.0 | - | - | 76.8 | 73.8% | - |
| Claude Opus 5 max | Anthropic | 60.9% | 59.4% | 37.6 | - | - | - | 63.3% | - |
| Grok 4.7 xhigh | xAI | 42.7% | 20.0% | 31.2 | - | - | - | 59.4% | - |
| Muse Wonder Full max | Meta | 41.0% | 17.6% | 30.6 | - | - | - | - | - |
| Claude Sonnet 5.5 maxAA max run with the default fallback model. | Anthropic | 51.5% | 43.3% | 30.5 | - | - | - | 44.7% | - |
| Kimi K3.1 ProOpen weights since November 2, 2026. | Moonshot AI | 48.9% | 37.3% | 29.9 | - | - | - | - | - |
| GPT-6.1 Terra maxMax effort, as Artificial Analysis lists it. Its high setting reads 47.3% accuracy, 37.0% hallucination, Index 27.8. | OpenAI | 47.6% | 34.5% | 29.6 | - | - | - | - | - |
| Muse Spark Open xhigh | Meta | 42.0% | 28.0% | 25.8 | - | - | - | - | - |
| Muse Wonder maxIts high setting reads 38.2% accuracy, 22.2% hallucination, Index 24.5. | Meta | 38.0% | 20.9% | 25.1 | - | - | - | - | - |
| Gemini 3.8 Flash high | Google DeepMind | 50.5% | 55.1% | 23.3 | - | - | 71.2 | 74.6% | - |
| Muse Spark 1.3 max | Meta | 38.0% | 25.2% | 22.4 | - | - | - | - | - |
| GPT-6 Sol maxFACTS: the November 5, 2026 board scores GPT-6 Sol on the Parametric slice only (76.1), so the cell is blank. Its September 28 average was 72.5. | OpenAI | 51.1% | 60.8% | 21.4 | 6.5% | - | - | 64.4% | - |
| Inkling 2 SmallWeights not yet released. Thinking Machines plans to publish them under Apache 2.0. | Thinking Machines Lab | 33.8% | 26.7% | 16.1 | - | - | - | - | - |
| Claude Haiku 5.5 maxMax effort, as Artificial Analysis lists it. Lower effort settings answer fewer questions correctly and guess slightly more often. | Anthropic | 34.7% | 34.2% | 12.3 | - | - | 47.3 | 23.9% | - |
| Qwen3.8 Max (0902) | Alibaba (Qwen) | 29.5% | 27.1% | 10.5 | - | - | - | - | - |
| Gemini 3.5 Flash-LiteFACTS: the November 5, 2026 board has no Grounding score for it, and averages its other three slices to 49.4, so the cell is blank. Its September 28 average was 53.5. | Google DeepMind | 26.5% | 26.7% | 6.9 | - | - | - | 33.1% | - |
| GLM-5.3 max | Zhipu AI (Z.ai) | 32.3% | 38.9% | 6.0 | - | - | - | - | - |
| Tencent Hy4Tencent's own figures conflict: its research blog gives a 5.45% hallucination rate, its press release 7.2%, both on Tencent's internal tests. | Tencent | 50.0% | 89.1% | 5.4 | - | - | - | - | - |
| Mistral Large 4 highThe October 6 preview build read 23.9% accuracy, 41.3% hallucination, Index -7.5. | Mistral AI | 26.0% | 28.2% | 5.1 | - | - | - | - | - |
| DeepSeek V4.1 Flash 1017 maxThe October 17 build. The earlier DeepSeek V4.1 Flash row holds the previous build's v1 record. | DeepSeek | 39.6% | 64.1% | 0.9 | - | - | - | - | - |
| Command A+ | Cohere | 9.8% | 13.9% | -2.7 | - | - | - | - | - |
| DeepSeek V4 Pro 0813 (GA)August 13 GA build at max effort, scored separately from the April preview because the checkpoints differ. | DeepSeek | 45.2% | 94.1% | -6.4 | - | - | - | - | - |
| MiniMax-M3.1-Flash | MiniMax | 45.1% | 93.7% | -6.4 | - | - | - | - | - |
| GPT-6 Luna max | OpenAI | 39.6% | 79.3% | -8.3 | - | - | 64.8 | - | - |
| GPT-5.6 Terra maxFACTS: the November 5, 2026 board scores GPT-5.6 Terra on Grounding and Parametric only (average 59.1), so the cell is blank. | OpenAI | 42.3% | 89.4% | -9.3 | - | - | - | 41.5% | - |
| GPT-5.6 Luna maxFACTS: the November 5, 2026 board scores GPT-5.6 Luna on the Parametric slice only (50.6), so the cell is blank. | OpenAI | 39.1% | 92.3% | -17.1 | - | - | - | 39.1% | - |
| Claude Fable 5 maxAA max run with Opus 4.8 fallback. HalluHard on its updated question set, with adaptive thinking. | Anthropic | 65.0%v1 | 63.6%v1 | 43.0v1 | - | - | - | - | 38.9%‡ |
| Gemini 3.1 ProVectara, FACTS 2026 and SimpleQA Verified figures are listed as Gemini 3.1 Pro Preview. On the FACTS board its Parametric score, 79.4, does not appear on the Parametric sub-board itself. | Google DeepMind | 54.9%v1 | 50.9%v1 | 31.9v1 | 10.4% | - | 69.1 | 77.5% | - |
| Grok 4.6 highAA configuration: high, with no v1.1 record. On AA-Omniscience v1.1 the xhigh setting reads 46.2% accuracy, 39.7% hallucination, Index 24.9. | xAI | 48.2%v1 | 34.3%v1 | 30.5v1 | - | - | - | 52.9% | - |
| Claude Opus 4.8FACTS: 53.5 on the 2026 Kaggle board of September 28, 2026. The model is no longer on the board. | Anthropic | 48.8%v1 | 39.3%v1 | 28.8v1 | - | - | - | 44.5% | - |
| Muse Spark 1.1 xhigh | Meta | 52.1%v1 | 50.0%v1 | 28.1v1 | - | - | - | - | - |
| Claude Opus 4.7AA configuration: max. FACTS: 45.5 on the 2026 Kaggle board of September 28, 2026. The model is no longer on the board. | Anthropic | 48.9%v1 | 42.3%v1 | 27.3v1 | 12.0% | - | - | - | - |
| Muse Spark 1.2 xhigh | Meta | 45.4%v1 | 33.3%v1 | 27.2v1 | - | - | - | - | - |
| Gemini 3.7 Flash highFACTS: 71.2 on the 2026 Kaggle board of September 28, 2026. The model is no longer on the board. SimpleQA Verified now marks the model deprecated: still listed, but unranked and hidden from the board's default view. | Google DeepMind | 55.3%v1 | 64.5%v1 | 26.5v1 | - | - | - | 73.2% | - |
| Grok 4.5 highFACTS: the November 5, 2026 board scores Grok 4.5 on the Parametric slice only (42.5), so the cell is blank. Its September 28 average was 50.2. | xAI | 51.6%v1 | 54.1%v1 | 25.3v1 | - | - | - | 53.8% | - |
| GPT-5.6 Sol maxFACTS: the November 5, 2026 board scores GPT-5.6 Sol on the Parametric slice only (81.1, the top of the board's average column), so the cell is blank. | OpenAI | 59.4%v1 | 92.2%v1 | 22.0v1 | 12.4% | - | - | 69.2% | - |
| Gemini 3.5 Flash highFACTS: 63.1 on the 2026 Kaggle board of September 28, 2026. The model is no longer on the board. SimpleQA Verified now marks the model deprecated: still listed, but unranked and hidden from the board's default view. | Google DeepMind | 51.4%v1 | 62.2%v1 | 21.2v1 | - | - | - | 70.4% | - |
| GPT-5.5 xhighFACTS: 66.7 on the 2026 Kaggle board of September 28, 2026. The model is no longer on the board. | OpenAI | 58.0%v1 | 89.0%v1 | 20.5v1 | 9.3% | - | - | - | - |
| Kimi K3 max | Moonshot AI | 47.6%v1 | 53.2%v1 | 19.7v1 | - | - | - | - | - |
| Grok 4.3 highShown in two configurations. Medium attempts fewer questions, which lowers both accuracy and hallucination. | xAI | 34.8%v1 | 25.8%v1 | 18.0v1 | - | - | - | - | - |
| Grok 4.3 mediumShown in two configurations. Medium attempts fewer questions, which lowers both accuracy and hallucination. | xAI | 28.8%v1 | 16.9%v1 | 16.7v1 | - | - | - | - | - |
| Claude Sonnet 5 max | Anthropic | 40.1%v1 | 39.4%v1 | 16.5v1 | - | - | - | 32.1% | - |
| Gemini 3 ProVectara (new) and SimpleQA Verified figures are for the preview. | Google DeepMind | 55.8%v1 | 91.5%v1 | 15.3v1 | 13.6% | - | 68.8† | 72.1% | - |
| Grok 4.20 (Reasoning)AA build: Grok 4.20 0309 v2, reasoning. | xAI | 27.5%v1 | 17.4%v1 | 14.8v1 | - | - | - | - | - |
| Claude Opus 4.5AA configuration: reasoning. FACTS 2026 Kaggle board of September 28, 2026: 43.9. Claude Opus 4.5 is no longer on that board. | Anthropic | 46.6%v1 | 61.0%v1 | 14.0v1 | 10.9% | - | 51.3† | 39.0% | 30.2% |
| Claude Opus 4.6AA configuration: max. FACTS: 41.5 on the 2026 Kaggle board of September 28, 2026. The model is no longer on the board. | Anthropic | 47.0%v1 | 62.8%v1 | 13.7v1 | 12.2% | - | - | 45.2% | - |
| Qwen3.7 Max | Alibaba (Qwen) | 31.1%v1 | 25.6%v1 | 13.5v1 | - | - | - | - | - |
| Claude Sonnet 4.6AA configuration: max. FACTS: 37.0 on the 2026 Kaggle board of September 28, 2026. The model is no longer on the board. | Anthropic | 40.9%v1 | 48.4%v1 | 12.2v1 | 10.6% | - | - | 30.9% | - |
| GPT-5.3 Codex xhigh | OpenAI | 52.9%v1 | 89.2%v1 | 10.9v1 | - | - | - | - | - |
| Gemini 3 FlashAA configuration: reasoning. Vectara (new) figure is listed as Gemini 3 Flash Preview. FACTS: the November 5, 2026 board scores Gemini 3 Flash Preview on the Parametric slice only (72.4), so the cell is blank. Its September 28 average was 63.4. | Google DeepMind | 53.4%v1 | 93.0%v1 | 10.1v1 | 13.5% | - | - | - | - |
| GPT-5.1AA configuration: high. Vectara (new) figure is the high setting. | OpenAI | 37.7%v1 | 51.9%v1 | 5.4v1 | 12.1% | - | 49.4† | 34.9% | - |
| Qwen3.8 Max Preview | Alibaba (Qwen) | 31.9%v1 | 41.7%v1 | 3.4v1 | - | - | - | - | - |
| Grok 4Not on Vectara's new-dataset board, so that cell is blank. Vectara's November 2025 launch post put it above 10%. | xAI | 40.5%v1 | 64.5%v1 | 2.1v1 | - | 4.8% | 53.6† | - | - |
| Claude Sonnet 4.5AA configuration: reasoning. | Anthropic | 32.9%v1 | 49.1%v1 | -0.1v1 | 12.0% | 5.5% | 49.1† | - | - |
| GPT-5.2 xhighVectara (new) figure is the high setting. FACTS: 48.5 on the 2026 Kaggle board of September 28, 2026. The model is no longer on the board. | OpenAI | 44.3%v1 | 81.2%v1 | -0.9v1 | 10.8% | - | - | - | 38.2% |
| DeepSeek V4.1 Flash maxVectara (new) and SimpleQA Verified figures are listed as DeepSeek V4.1 Flash, with no build date, so they may come from either build. | DeepSeek | 46.4%v1 | 96.5%v1 | -5.3v1 | 4.2% | - | - | 42.3% | - |
| Claude 4.5 HaikuAA configuration: non-reasoning. | Anthropic | 14.4%v1 | 25.7%v1 | -7.6v1 | 9.8% | 4.5% | - | - | - |
| GPT-5AA configuration: high. Vectara figures are the high setting. FACTS 2026 Kaggle board of September 28, 2026: 56.5. GPT-5 is no longer on that board. | OpenAI | 40.3%v1 | 82.2%v1 | -8.7v1 | 15.1% | 1.4% | 61.8† | - | - |
| DeepSeek V4 Pro (preview)April preview (0424 build), scored separately from the August 13 GA build. | DeepSeek | 43.0%v1 | 94.1%v1 | -10.7v1 | 8.6% | - | - | - | - |
| DeepSeek V4 Flash (0420) | DeepSeek | 36.8%v1 | 96.1%v1 | -23.9v1 | - | - | - | - | - |
| DeepSeek-R1Vectara figures are the original R1 release. AA figures are the 0528 build. | DeepSeek | 30.5%v1 | 83.4%v1 | -27.4v1 | 11.3% | 14.3% | - | - | - |
| Grok 4.1 FastAA configuration: reasoning. Vectara (new) figure is with reasoning. | xAI | 25.1%v1 | 73.4%v1 | -29.9v1 | 19.2% | - | - | - | - |
| Llama 4 Maverick | Meta | 24.9%v1 | 88.9%v1 | -41.9v1 | 8.2% | 4.6% | - | - | - |
| Claude 3.7 Sonnet | Anthropic | - | - | - | - | 4.4% | - | - | - |
| Claude 4.1 OpusArtificial Analysis no longer lists this model, so its AA-Omniscience cells are blank. | Anthropic | - | - | - | 11.8% | 4.2% | 46.5† | - | - |
| DeepSeek-V3 | DeepSeek | - | - | - | 6.1% | 3.9% | - | 27.4% | - |
| Gemini 2.0 Flash | Google DeepMind | - | - | - | - | 0.7% | - | - | - |
| Gemini 2.5 Pro | Google DeepMind | - | - | - | 7.0% | - | 62.1† | - | - |
| GPT-4.1 | OpenAI | - | - | - | 5.6% | 2.0% | 50.5† | - | - |
| GPT-5.4 nano | OpenAI | - | - | - | 3.1% | - | - | - | - |
| Grok-3Vectara (old) figure is listed as Grok-3-Beta. | xAI | - | - | - | 5.8% | 2.1% | - | 39.3% | - |
| o3-mini-high | OpenAI | - | - | - | - | 0.8% | - | - | - |
| Perplexity Sonar Pro | Perplexity | - | - | - | - | - | - | - | - |
Sources: Artificial Analysis AA-Omniscience v1.1 model records, read November 7, 2026 [2]. final AA-Omniscience v1 records, read October 4, 2026, marked v1 [2]. Vectara's new 7,700-article dataset, snapshot of October 22, 2026 [1]. Vectara's original dataset, archived October 16, 2025 [100]. FACTS on Kaggle, last updated November 5, 2026, and its December 2025 launch table [3]. SimpleQA Verified on Kaggle, last updated October 20, 2026 [101]. HalluHard with web search, read November 7, 2026 [5].
Artificial Analysis moved AA-Omniscience to v1.1 on October 27, 2026, with a new question set, and re-ran these models. Their accuracy, hallucination and Index cells show v1.1 records, read November 7, 2026.
Artificial Analysis has not re-run these models on v1.1. Their final v1 records, read October 4, 2026, are shown in grey, sort after every v1.1 record and are left out of every ranking.
Gemini 4 Carbon (high and medium), GPT-6.1 Terra, Claude Haiku 5.5, Muse Wonder Full, Muse Wonder, Muse Spark Open, Kimi K3.1 Pro, Mistral Large 4, Tencent Hy4, MiniMax-M3.1-Flash, DeepSeek V4.1 Flash 1017 and Inkling 2 Small, with their AA-Omniscience v1.1 records.
Google opened it in the paid tier of the Gemini API and in the Gemini app for Google AI Pro and Ultra subscribers, so the not-yet-public badge is gone.
Added to the board on October 22, October 16 and October 22, 2026.
GPT-6 Astra 78.1, GPT-6.1 Sol 76.8, Gemini 4 Argon 72.4, Gemini 3.8 Flash 71.2, Gemini 3.1 Pro 69.1, Claude Opus 5.5 66.5, GPT-6 Luna 64.8 and Claude Haiku 5.5 47.3. The board averages only the slices each model has been scored on, so the column now shows models scored on all four.
The November 5 board scores these models on one to three of the four slices, so their averages are not comparable with full-coverage rows. The partial figures are in the row notes.
These models are no longer on the FACTS board. Their September 28, 2026 averages are in the row notes.
Gemini 4 Argon 75.6%, DeepSeek V4.1 Flash 42.3%, GPT-5.6 Terra 41.5%, GPT-5.6 Luna 39.1%, Claude Opus 4.5 39.0%, GPT-5.1 34.9%, DeepSeek-V3 27.4% and Claude Haiku 5.5 23.9%.
The column now reads the FACTS board on Kaggle. Models that had a December 2025 launch-table figure keep it, marked †, and their 2026 figure is in the row note where it exists.
Short factual questions answered without tools, from Google DeepMind's board on Kaggle.
It held two figures from one March 2025 study. Both, 94% and 37%, are still covered in the benchmark and Perplexity sections.
The model is not on the board, and the table now shows board figures only. The estimate from Vectara's November 2025 launch post is in the row note.
The model has never been on Vectara's new-dataset board.
The model has never been on Vectara's new-dataset board.
The figure belonged to o3.
The figure belonged to GPT-5. Filled again from the 2026 Kaggle board on October 8.
The figure belonged to Grok 4 Fast.
No source supports 0%. Artificial Analysis's launch analysis gave 48%, and it no longer lists the model.
The board figure replaces the estimate from Vectara's November 2025 launch post.
Filled from the board.
From the archived original-dataset board.
20.2% was Grok 4 Fast's score.
88% was the launch figure. Artificial Analysis re-ran the model before August, then moved every model to a new grader on August 6, 2026.
36% was the launch figure. The current record follows Artificial Analysis's move to a new grader on August 6, 2026.
81% was GPT-5 (high)'s launch figure, shown on this row by mistake. GPT-5.1 (high) launched at 51.1%.
Every AA-Omniscience value that Artificial Analysis still lists was re-read from its records of October 4, 2026.
GPT-6 Astra, GPT-6 Sol, GPT-6.1 Sol, GPT-6 Luna, Claude Fable 5.1, Claude Opus 5.5, Claude Sonnet 5.5, Gemini 4 Argon, Gemini 3.8 Flash, Gemini 3.5 Flash-Lite, Grok 4.7, Muse Spark 1.3, Qwen3.8 Max (0902) and DeepSeek V4.1 Flash, with their October 4 AA-Omniscience records.
Earlier changes, and changes to the rest of this page, are in the revision log.
Best knowledge reliability index: Gemini 4 Carbon (high), at Index 53.5 on AA-Omniscience v1.1, the highest on Artificial Analysis's board, with 58.3% accuracy and 11.4% hallucination (not yet publicly available). Among public models, Claude Opus 5.5 leads at 48.1, ahead of Claude Fable 5.1 (46.3) and Gemini 4 Argon (46.1). Calibration is still weak for Opus 5.5: when it can't answer correctly, it gives a wrong answer instead of declining 50.3% of the time. The Fable 5.1, Opus 5.5 and Sonnet 5.5 rows are Artificial Analysis's max runs with the default fallback model.
Best public Index without a fallback model: Gemini 4 Argon, at 46.1 with 48.3% accuracy and 4.3% hallucination (high). GPT-6 Astra follows at 44.6 on its high setting (61.1% accuracy, 42.5% hallucination) and 42.4 at max, the setting in our table.
Highest accuracy: Claude Fable 5.1, at 68.4% on AA-Omniscience v1.1, the best in this table. It also has the highest hallucination rate of any current Claude, 70.0% (72.6% on v1).
Lowest hallucination rate (knowledge tasks): Gemini 4 Carbon (medium), at 4.2% on AA-Omniscience v1.1 while answering 48.9% of questions correctly (not yet publicly available). Gemini 4 Argon, public since October 13, 2026, is essentially level at 4.3% (48.3% accuracy). The previous holder, Command A+ (Cohere, open weights), reads 13.9%, reached by refusing most questions it can't verify (9.8% accuracy).
Biggest single improvement: GPT-6.1 Terra cut hallucination to 34.5% on AA-Omniscience v1.1 from 89.4% for its direct predecessor, GPT-5.6 Terra, a 54.9-point drop, while answering more questions correctly (47.6% against 42.3%). On v1, GPT-6 Astra had cut GPT-5.6 Sol's 92.2% to 51.3%.
Best calibration among the most accurate models: Gemini 4 Carbon (high), at 11.4% hallucination with 58.3% accuracy (not yet publicly available). Among public models that answer at least 60% of questions correctly, GPT-6 Astra is best calibrated at 49.8% (61.6% accuracy, max) and 42.5% on its high setting.
Lowest hallucination among open-weight models answering at least 25% correctly, in our table: Muse Spark Open (Meta), at 28.0% with 42.0% accuracy (xhigh), just ahead of Mistral Large 4 at 28.2% (26.0% accuracy). Kimi K3.1 Pro, open since November 2, has the highest open-weight Index in our table, 29.9, with 37.3% hallucination. Inkling 2 Small reads 26.7%, but its weights are not out yet.
Largest hallucination rate (knowledge questions), in our table: DeepSeek V4 Pro 0813, at 94.1% on AA-Omniscience v1.1, just above MiniMax-M3.1-Flash (93.7%) and OpenAI's GPT-5.6 Luna (92.3%). DeepSeek's October build of V4.1 Flash reads 64.1% on v1.1. On v1 it read 66.8%, far below the 96.5% of the September build.
Biggest variable across all models: Web search access, which reduces hallucination 73-86% when enabled (OpenAI FActScore evaluations of its own models)
Best citation accuracy: Perplexity Sonar Pro, at 37% hallucination on CJR (lowest, but still high)
Lowest hallucination rate (summarization): Ant Group finix_s1_32b, at 0.6% on Vectara's original dataset (Gemini-2.0-Flash: 0.7%) and 1.8% on the new 7,700-article dataset, where GPT-5.4 nano is the best frontier-lab model at 3.1%. DeepSeek V4.1 Flash, added on October 22, 2026, ranks sixth of 111 at 4.2%.
Best in realistic conversations: GPT-6 Astra, at 27.2% on HalluHard with web search, on its updated question set, ahead of Claude Opus 4.5 at 30.2%
Highest factuality score (multi-dimensional): GPT-6 Astra, at 78.1 on the FACTS board on Kaggle (November 5, 2026), the best of the models scored on all four slices, ahead of GPT-6.1 Sol (76.8) and Gemini 4 Argon (72.4). Gemini 3 Pro led the December 2025 launch table at 68.8, on a scale that is not directly comparable
Best short-answer factuality without tools: Gemini 3.1 Pro Preview, at 77.5% on SimpleQA Verified (Kaggle board, October 20, 2026), ahead of GPT-6 Astra at 75.8% and Gemini 4 Argon at 75.6%
The November 2026 pattern: AA-Omniscience v1.1 reshuffled the numbers but not the split. Google's Gemini 4 models now hold the lowest hallucination rates of any model that answers about half of questions correctly: Carbon (medium) at 4.2% and Argon, the public one, at 4.3%. OpenAI improved on both counts again: GPT-6.1 Terra answers more questions correctly than GPT-5.6 Terra (47.6% against 42.3%) and hallucinates far less (34.5% against 89.4%). Anthropic still has the model that knows the most: Claude Fable 5.1 answers 68.4% of questions correctly and gives a wrong answer on 70.0% of the rest. Opus 5.5 gives up about 3 points of accuracy for about 20 points less hallucination (65.5% and 50.3%). Accuracy and calibration still move independently.
Application
These benchmarks show which models perform better under specific conditions, but no single model is flawless and every leaderboard tests something slightly different. If you're looking for the lowest hallucination AI workflow for real high-stakes work, Suprmind runs your question through five frontier AI models who read each other’s responses, argue, challenge, and build on each other. When one model hallucinates, the others catch it before it reaches your decision.
See how the multi-AI workflow worksListen to the full research (32 min)
An AI hallucination is when an AI model makes something up and presents it as fact. It doesn't flag uncertainty. It doesn't say "I'm guessing." It delivers fabricated statistics, invented legal cases, or nonexistent research papers with the same confidence it uses for basic arithmetic. The output reads perfectly. That's what makes it dangerous.
Hallucination refers to generated output not grounded in the provided input or factual reality. Two types:
Intrinsic hallucination (faithfulness failure): The model contradicts information it was explicitly given. Hand it a contract and ask for a summary, and it adds clauses that don't exist in the original document.
Extrinsic hallucination (factuality failure): The model generates information that can't be verified against any known source. It invents facts, statistics, citations, or events from scratch. No source material was contradicted because no source material was consulted.
Cash and Oppenheimer put numbers on this in Memory & Cognition (July 2025). Both humans and LLMs began overconfident about how they would perform on a 20-item identification task. After answering, humans revised their self-assessments downward. The models revised theirs upward. Gemini predicted it would score 10.03 out of 20, actually scored 0.93, then estimated in retrospect that it had scored 14.40. The models simply could not tell how badly they had done. [82]
An AI sounds the same when it is right and when it is wrong.
Large language models are prediction engines, not knowledge bases. They generate text by predicting the most statistically likely next token based on patterns in training data. They don't understand truth. They predict plausibility.
When the model hits a gap in its training data or faces an ambiguous query, it fills the gap with something plausible rather than admitting it doesn't know. Next-token prediction supplies no "I'm not sure" on its own - it just picks the next most probable word. Post-training can teach a model to abstain, and how well that lesson took is exactly what AA-Omniscience measures below.
And this isn't a bug that will be fixed in the next update. Two independent research teams have published formal impossibility results showing that hallucination cannot be engineered out of a general-purpose language model, only managed. Not an engineering shortcoming waiting on the next release. A structural property of the approach. (More on this, including what the proofs do and do not claim, in the Mathematical Impossibility section below.) [20][21]
Before looking at any hallucination data, you need to understand why different benchmarks give wildly different scores for the same model.
Grok-3 scores 2.1% on the Vectara summarization benchmark. Excellent. That same model scores 94% on the Columbia Journalism Review citation accuracy test. Catastrophic. Same model, same time period, opposite conclusions.
This isn't an error. It's measuring different things. And treating any single benchmark as "the hallucination rate" will mislead you.
The matrix below summarizes what each benchmark actually tests. Click any benchmark name to jump to its dedicated section.
| Benchmark | What It Measures | Good For | Not Good For |
|---|---|---|---|
| Vectara HHEM | Summarization faithfulness: does the model add unsupported facts when summarizing source documents? | RAG pipelines, document Q&A, knowledge base search | Open-ended knowledge questions |
| AA-Omniscience | When the model doesn't know an answer, does it admit it or fabricate one? The Omniscience Index penalizes wrong answers and rewards refusal. | High-stakes advisory work (legal, medical, financial) | Summarization or grounded tasks |
| FACTS | Multi-dimensional factuality across grounding, multimodal, parametric, and search. Each dimension scored separately. | Comparing where models are strong and weak across task types | Producing a single hallucination rate number |
| SimpleQA / PersonQA | Short factual questions and accuracy about real people. SimpleQA Verified is Google DeepMind's cleaned-up 1,000-question version of SimpleQA. Newer reasoning models often perform worse than predecessors here. | Quick factuality testing on straightforward questions | Complex, multi-step, or domain-specific queries |
| HalluHard | Hallucination rate in realistic conversational settings. Even the best entry, GPT-6 Astra with web search, still hallucinates 27.2% of the time. | Predicting real-world rates in production chat applications | Controlled, reproducible model comparisons |
| CJR Citation | Whether AI models correctly attribute information to cited sources. Failure mode: real URLs with fabricated content attached. | Research, journalism, any source-attribution task | General knowledge or summarization evaluation |
| BullshitBench v2 | Whether the model pushes back on a nonsense premise or confidently builds on it. 100 prompts across software, finance, legal, medical and physics, scored by a three-model judge panel. Measures sycophancy, not recall. | Advisory work where the user's own premise may be wrong | Measuring factual knowledge or grounded accuracy |
Sources: Vectara HHEM [1], AA-Omniscience [2], FACTS [3], SimpleQA/PersonQA [4], SimpleQA Verified [101], HalluHard [5], CJR Citation Study [6], BullshitBench v2 [94]
TruthfulQA was once the gold standard. It's now partially saturated: models have been trained on its questions. Worse, researchers showed a simple decision tree can score 79.6% on TruthfulQA multiple choice without even seeing the question being asked, just by exploiting structural patterns in answer formatting. A 2025-2026 TruthfulQA score tells you little about a frontier model on its own. [29]
HaluEval has a similar problem. A length-based classifier achieves 93.3% accuracy on HaluEval QA simply by flagging answers longer than 27 characters as hallucinated. The benchmark measures answer length more than it measures truthfulness. [30]
Both remain useful for tracking a model family over time. Neither is sufficient as a hallucination rate for a 2026 model, which is why this page does not use them in its tables.
No single benchmark gives you "the hallucination rate" of any model. If someone quotes one number, they're either simplifying for convenience or cherry-picking for marketing.
The responsible approach: cross-reference at least two benchmarks that measure different things (one grounded task like Vectara, one open-ended knowledge task like AA-Omniscience), specify the exact model version and calling conditions, and note whether tool access was enabled. The sections that follow do exactly that.
Vectara's leaderboard is the most cited hallucination benchmark in the industry. It measures summarization faithfulness: given a source document, does the model's summary stick to what's actually in the document, or does it add unsupported facts? This makes it a direct proxy for how AI behaves in RAG pipelines, enterprise search tools, and document analysis workflows. The leaderboard exists in two versions, and the gap between them tells an important story. [1]
This is the dataset most articles reference when they quote hallucination rates. The documents are relatively short and the summarization tasks are straightforward.
| Model | Provider | Hallucination Rate | Factual Consistency |
|---|---|---|---|
| antgroup/finix_s1_32b | Ant Group | 0.6% | 99.4% |
| Gemini-2.0-Flash-001 | 0.7% | 99.3% | |
| Gemini-2.0-Pro-Exp | 0.8% | 99.2% | |
| o3-mini-high | OpenAI | 0.8% | 99.2% |
| Gemini-2.5-Pro-Exp | 1.1% | 98.9% | |
| GPT-4.5-Preview | OpenAI | 1.2% | 98.8% |
| Gemini-2.5-Flash-Preview | 1.3% | 98.7% | |
| o1-mini | OpenAI | 1.4% | 98.6% |
| GPT-5 (high) | OpenAI | 1.4% | 98.6% |
| GPT-4o | OpenAI | 1.5% | 98.5% |
| GPT-4o-mini | OpenAI | 1.7% | 98.3% |
| GPT-4-Turbo | OpenAI | 1.7% | 98.3% |
| GPT-4 | OpenAI | 1.8% | 98.2% |
| Grok-2 | xAI | 1.9% | 98.1% |
| GPT-4.1 | OpenAI | 2.0% | 98.0% |
| Grok-3-Beta | xAI | 2.1% | 97.8% |
| Qwen3-14B | Qwen/Alibaba | 2.2% | 97.8% |
| DeepSeek-V3 | DeepSeek | 3.9% | 96.1% |
| Claude-3.7-Sonnet | Anthropic | 4.4% | 95.6% |
| Claude-3.5-Sonnet | Anthropic | 4.6% | 95.4% |
| o4-mini | OpenAI | 4.6% | 95.4% |
| Llama-4-Maverick | Meta | 4.6% | 95.4% |
| DeepSeek-V3.2-Exp | DeepSeek | 4.6% | 95.4% |
| Grok-4 | xAI | 4.8% | 95.2% |
| Claude-3.5-Haiku | Anthropic | 4.9% | 95.1% |
| Claude-3-Opus | Anthropic | 10.1% | 89.9% |
| DeepSeek-R1 | DeepSeek | 14.3% | 85.7% |
Source: Vectara HHEM Leaderboard, original ~1,000-document dataset, archived GitHub branch (hhem-2.3-old-dataset, last updated October 16, 2025). Ant Group's finix_s1_32b leads this archived table at 0.6%. Rows checked against the archived branch on August 27, 2026: GPT-5.4 nano, GPT-5.4 mini and Gemma-4-26B were never evaluated on this dataset and have moved to the new-dataset table below, where they belong. [1][100]
On this dataset, the numbers look encouraging. Ant Group's finix_s1_32b and two Gemini 2.0 models take the top three spots, with OpenAI's o3-mini-high tied for third. OpenAI's GPT models in this table sit between 1.2% and 2.0%. Every model in this table stays under 15%, though the full archived board runs up to 29.9% for older small models.
Correction, August 2026: an earlier version of this page listed finix_s1_32b at 1.8% on the original dataset. That is its rate on the new 7,700-article dataset, where it also leads. On the archived original dataset it scores 0.6%, one tenth of a point below Gemini-2.0-Flash. It is the first time a Chinese enterprise model has topped either Vectara table. Vectara froze the original dataset in October 2025, so no model released after that date will appear here. [100]
But this dataset is easy. The documents are short, the summarization tasks are clean, and the real world is neither.
Vectara launched a refreshed benchmark in late 2025 with longer documents (up to 32K tokens) spanning law, medicine, finance, technology, and education. This version better reflects what enterprise AI systems actually face.
Rates rose for most models:
| Model | Provider | Hallucination Rate |
|---|---|---|
| Grok 4 Fast (reasoning) | xAI | 20.2% |
| Grok 4.1 Fast (reasoning) | xAI | 19.2% |
| GPT-5 (high) | OpenAI | 15.1% |
| Gemini 3 Pro Preview | 13.6% | |
| Gemini 3 Flash Preview | 13.5% | |
| GPT-5.6 Sol | OpenAI | 12.4% |
| Claude Opus 4.6 | Anthropic | 12.2% |
| Gemini 4 Argon | 12.1% | |
| Claude Opus 4.7 | Anthropic | 12.0% |
| Claude Sonnet 4.5 | Anthropic | 12.0% |
| Claude Opus 4.1 | Anthropic | 11.8% |
| DeepSeek-R1 | DeepSeek | 11.3% |
| Claude Opus 4.5 | Anthropic | 10.9% |
| GPT-5.2 (high) | OpenAI | 10.8% |
| Claude Sonnet 4.6 | Anthropic | 10.6% |
| Gemini 3.1 Pro Preview | 10.4% | |
| Claude Opus 5.5 | Anthropic | 9.9% |
| Claude Haiku 4.5 | Anthropic | 9.8% |
| GPT-5.5 | OpenAI | 9.3% |
| GPT-6 Astra | OpenAI | 8.7% |
| DeepSeek V4 Pro | DeepSeek | 8.6% |
| GPT-5.2 (low) | OpenAI | 8.4% |
| Llama 4 Scout | Meta | 7.7% |
| GPT-5.4 | OpenAI | 7.0% |
| Gemini 2.5 Pro | 7.0% | |
| Command R+ | Cohere | 6.9% |
| GPT-6 Sol | OpenAI | 6.5% |
| DeepSeek-V3 | DeepSeek | 6.1% |
| Grok-3 | xAI | 5.8% |
| GPT-4.1 | OpenAI | 5.6% |
| GPT-5.4 mini | OpenAI | 5.5% |
| DeepSeek V3.2-Exp | DeepSeek | 5.3% |
| Gemma 4 26B | 5.2% | |
| Mistral Large (2411) | Mistral | 4.5% |
| DeepSeek V4.1 Flash | DeepSeek | 4.2% |
| Gemini 2.5 Flash-Lite | 3.3% | |
| GPT-5.4 nano | OpenAI | 3.1% |
| finix_s1_32b | Ant Group | 1.8% |
Source: Vectara Hallucination Leaderboard, new 7,700-article dataset, last updated October 22, 2026 and read November 7, 2026 [1]. The table shows 38 of the 111 models on the board, sorted from the highest rate to the lowest. Click a column header to re-sort. Ant Group's finix_s1_32b leads at 1.8%, and GPT-5.4 nano (3.1%) is the best frontier-lab entry. DeepSeek V4.1 Flash is listed as DeepSeek-V4.1-Flash, with no build date. DeepSeek-R1 scores 11.3% here. An earlier version of this table listed it at 7.7%, which is the original-dataset score of its 0528 build. GPT-5 is shown at its high setting, which scored 19.2% when the board launched in November 2025 and 15.1% now.
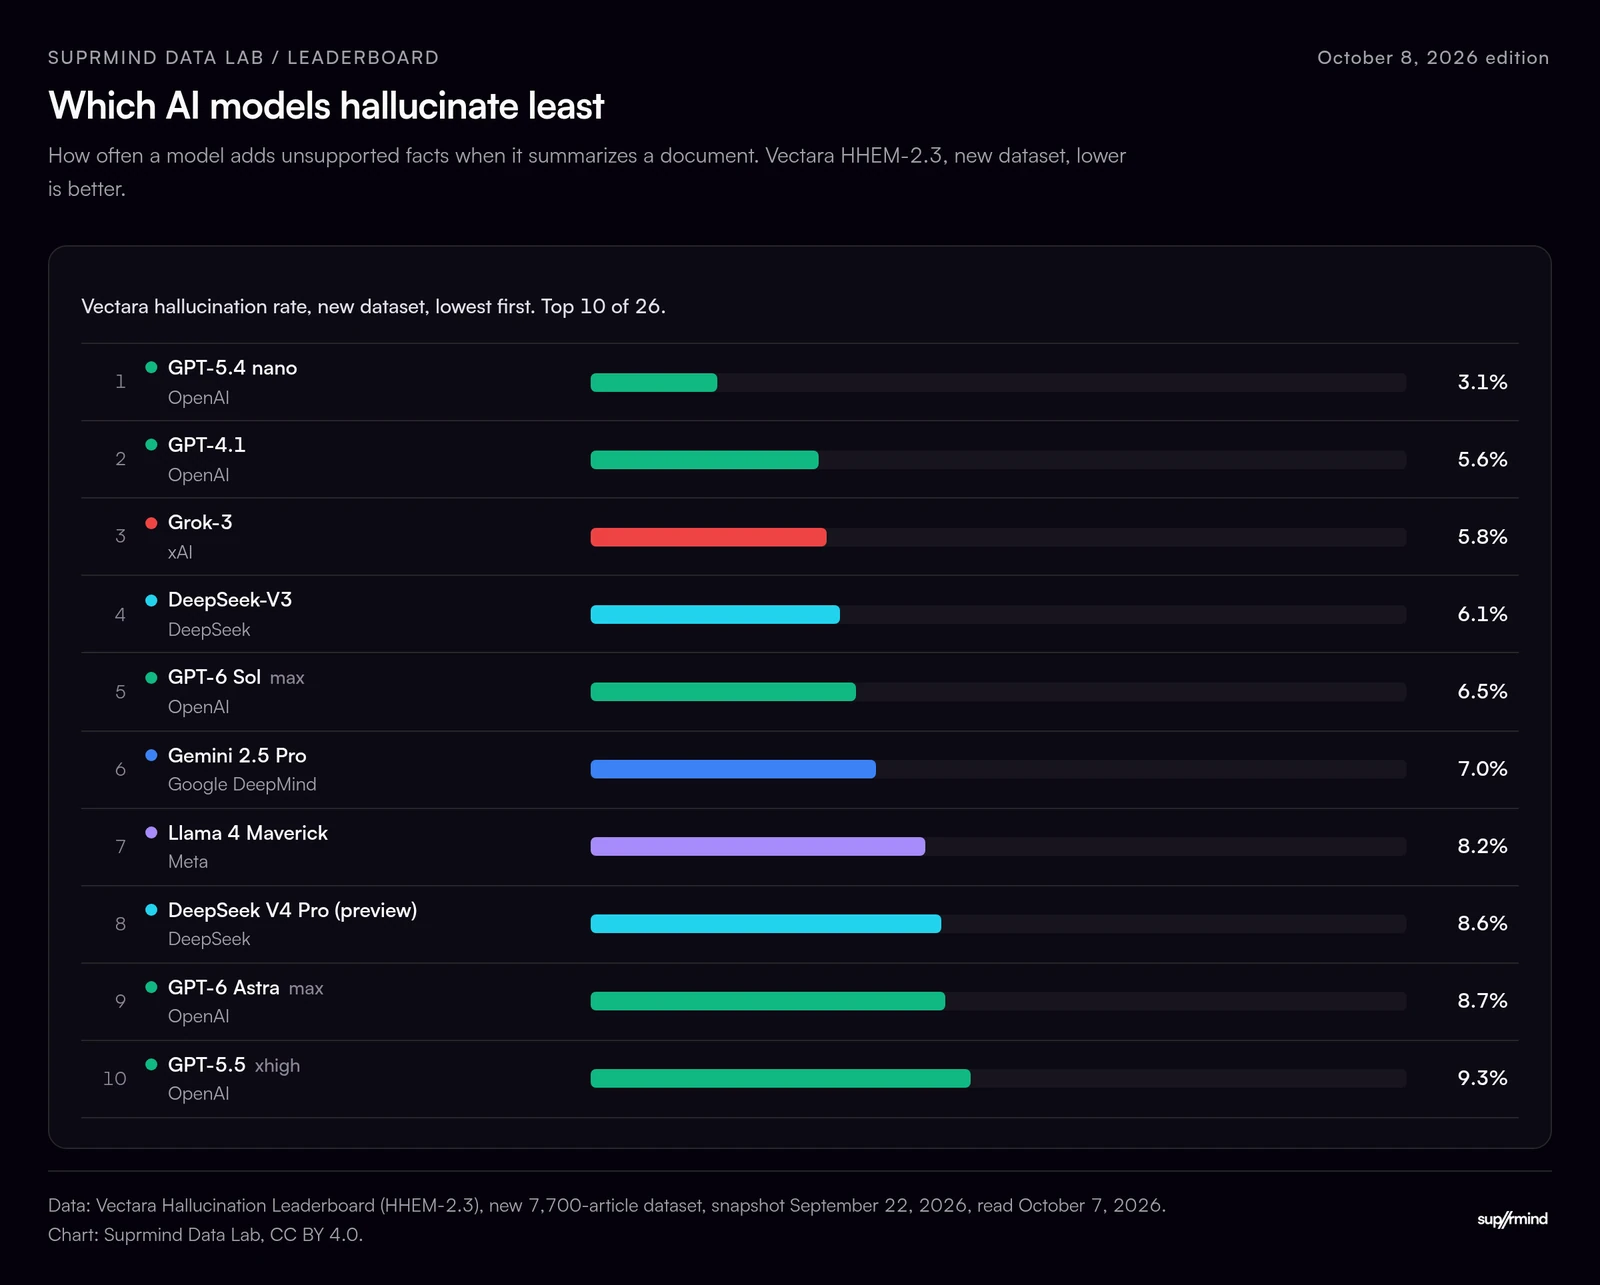
The same Vectara scores for the models this page tracks, with a filter by lab. Switch tabs for the original dataset or any other benchmark.
Vectara added Gemini 4 Argon on October 16, 2026 at 12.1%, then Claude Opus 5.5 at 9.9% and DeepSeek V4.1 Flash at 4.2% on October 22. Opus 5.5 is the first Claude Opus under 10% on the new dataset (Opus 4.7: 12.0%). Among Anthropic's models only Claude Haiku 4.5 reads lower there, at 9.8%. DeepSeek V4.1 Flash has the sixth-lowest rate of the 111 models on the board. Argon shows how far apart the two kinds of hallucination can sit: it has the lowest AA-Omniscience v1.1 hallucination rate of any public model, 4.3%, yet on Vectara it reads 12.1%, higher than Gemini 3.1 Pro Preview's 10.4%. Declining to guess on knowledge questions does not stop a model from adding unsupported detail to a summary. [1][2]
The September 22 update had added three OpenAI models: GPT-6 Sol at 6.5%, GPT-6 Astra at 8.7% and GPT-5.6 Sol at 12.4%. Both GPT-6 models score better than GPT-5.6 Sol, in line with their lower hallucination rates on AA-Omniscience. Claude Fable 5.1, Claude Sonnet 5.5, GPT-6.1 Sol, Gemini 4 Carbon and every Grok released since May 2026 have no score yet, so the board's latest Grok is still Grok 4.1 Fast (19.2% with reasoning). Earlier snapshots are covered in our February 2026 research report. [1]
When Vectara launched the new dataset in November 2025, the thinking models it named, including GPT-5, Claude Sonnet 4.5 and Grok-4, all came in above 10%, and Gemini-3-Pro read 13.6%. Grok-4-fast-reasoning reads 20.2% on the current board. Several of OpenAI's newer models have since come in under 10% on the same dataset: GPT-6 Sol at 6.5%, GPT-5.4 at 7.0%, GPT-6 Astra at 8.7% and GPT-5.5 at 9.3%, though GPT-5.6 Sol reads 12.4%. Anthropic's newest entry, Claude Opus 5.5, is its first Opus under 10%, at 9.9%, just above Claude Haiku 4.5 (9.8%). Google's newest, Gemini 4 Argon, reads 12.1%, above Gemini 3.1 Pro Preview's 10.4%. [102][1][48][49]
The hypothesis is straightforward. Reasoning models invest computational effort into "thinking through" answers. During summarization, this thinking leads them to add inferences, draw connections, and generate insights that go beyond what's in the source document. That's helpful for analysis. It's hallucination on a summarization benchmark.
This creates a critical decision for enterprise teams: reasoning mode helps on open-ended tasks and hurts on grounded tasks. Knowing when to enable it and when to turn it off is not optional.
AA-Omniscience asks a fundamentally different question than Vectara. Instead of "can you summarize without adding stuff," it asks "when you don't know something, do you admit it or make something up?" [2]
Artificial Analysis moved the benchmark to version 1.1 on October 27, 2026. It removed saturated questions and its old public set, added new questions and revised ambiguous or erroneous ones, which leaves 3,000 questions in six domains, 300 of them public. Version 1 had 6,000 questions across 42 topics. The Omniscience Index (scale: -100 to +100) penalizes wrong answers and doesn't penalize refusal. This makes it the only major benchmark that explicitly rewards models for knowing their own limits. [2][124]
How to read the three numbers together. Accuracy is the share of questions answered correctly. Hallucination rate is the share of non-correct responses that were wrong answers rather than refusals. The Index is correct minus incorrect. So a model can post the highest accuracy while still fabricating most of the time it doesn't know. That is Claude Fable 5.1's profile: 68.4% accuracy and a 70.0% hallucination rate. On Artificial Analysis's v1.1 board on November 7, 2026, 72 of 124 models have a positive Index. The other 52 give more wrong answers than right ones. [2]
Snapshot policy. Artificial Analysis re-runs models and adds effort configurations over time, so figures drift after launch, usually by a point or two and sometimes by much more. The two tables below hold every model in our table that has a v1.1 record, read from Artificial Analysis's own model records on November 7, 2026. Its v1.1 board lists 124 models, most of them released from July 2026 on. Models it did not re-run keep their final v1 record, read October 4, 2026, in the v1 archive under the second table and in the cross-benchmark table, marked v1. Artificial Analysis reports that models score about 2 points lower on the v1.1 Index on average, with a median drop of 0.6 points. The question sets still differ, so compare a v1.1 figure only with another v1.1 figure. [2][124]
| Model | Provider | Accuracy | Hallucination Rate | Omniscience Index |
|---|---|---|---|---|
| Claude Fable 5.1 (max) | Anthropic | 68.4% | 70.0% | 46.3 |
| Claude Opus 5.5 (max) | Anthropic | 65.5% | 50.3% | 48.1 |
| GPT-6.1 Sol (max) | OpenAI | 61.8% | 51.9% | 42.0 |
| GPT-6 Astra (max) | OpenAI | 61.6% | 49.8% | 42.4 |
| Claude Opus 5 (max) | Anthropic | 60.9% | 59.4% | 37.6 |
| Gemini 4 Carbon (high) | 58.3% | 11.4% | 53.5 | |
| Claude Sonnet 5.5 (max) | Anthropic | 51.5% | 43.3% | 30.5 |
| GPT-6 Sol (max) | OpenAI | 51.1% | 60.8% | 21.4 |
| Gemini 3.8 Flash (high) | 50.5% | 55.1% | 23.3 | |
| Tencent Hy4 | Tencent | 50.0% | 89.1% | 5.4 |
| Gemini 4 Carbon (medium) | 48.9% | 4.2% | 46.8 | |
| Kimi K3.1 Pro | Moonshot | 48.9% | 37.3% | 29.9 |
| Gemini 4 Argon (high) | 48.3% | 4.3% | 46.1 | |
| GPT-6.1 Terra (max) | OpenAI | 47.6% | 34.5% | 29.6 |
| DeepSeek V4 Pro 0813 (GA) (max) | DeepSeek | 45.2% | 94.1% | -6.4 |
| MiniMax-M3.1-Flash | MiniMax | 45.1% | 93.7% | -6.4 |
| Grok 4.7 (xhigh) | xAI | 42.7% | 20.0% | 31.2 |
| GPT-5.6 Terra (max) | OpenAI | 42.3% | 89.4% | -9.3 |
| Muse Spark Open (xhigh) | Meta | 42.0% | 28.0% | 25.8 |
| Muse Wonder Full (max) | Meta | 41.0% | 17.6% | 30.6 |
| DeepSeek V4.1 Flash 1017 (max) | DeepSeek | 39.6% | 64.1% | 0.9 |
| GPT-6 Luna (max) | OpenAI | 39.6% | 79.3% | -8.3 |
| GPT-5.6 Luna (max) | OpenAI | 39.1% | 92.3% | -17.1 |
| Muse Wonder (max) | Meta | 38.0% | 20.9% | 25.1 |
| Muse Spark 1.3 (max) | Meta | 38.0% | 25.2% | 22.4 |
| Claude Haiku 5.5 (max) | Anthropic | 34.7% | 34.2% | 12.3 |
| Inkling 2 Small | Thinking Machines Lab | 33.8% | 26.7% | 16.1 |
| GLM-5.3 (max) | Z.ai | 32.3% | 38.9% | 6.0 |
| Qwen3.8 Max (0902) | Alibaba | 29.5% | 27.1% | 10.5 |
| Gemini 3.5 Flash-Lite | 26.5% | 26.7% | 6.9 | |
| Mistral Large 4 (high) | Mistral AI | 26.0% | 28.2% | 5.1 |
| Command A+ | Cohere | 9.8% | 13.9% | -2.7 |
Source: Artificial Analysis AA-Omniscience v1.1 model records, read November 7, 2026 [2][124]. All 32 models in the cross-benchmark table that have a v1.1 record. Every row was checked for internal consistency (Index equals correct minus incorrect). A row without a named configuration is the one Artificial Analysis lists by default. The Claude Fable 5.1, Opus 5.5 and Sonnet 5.5 rows are max runs with the default fallback model. GPT-6 Astra's high setting reads 61.1% accuracy, 42.5% hallucination and Index 44.6, above its max run. Gemini 4 Carbon is not yet publicly available. Models without a v1.1 record are in the v1 archive below and in the cross-benchmark table at the top of the page.
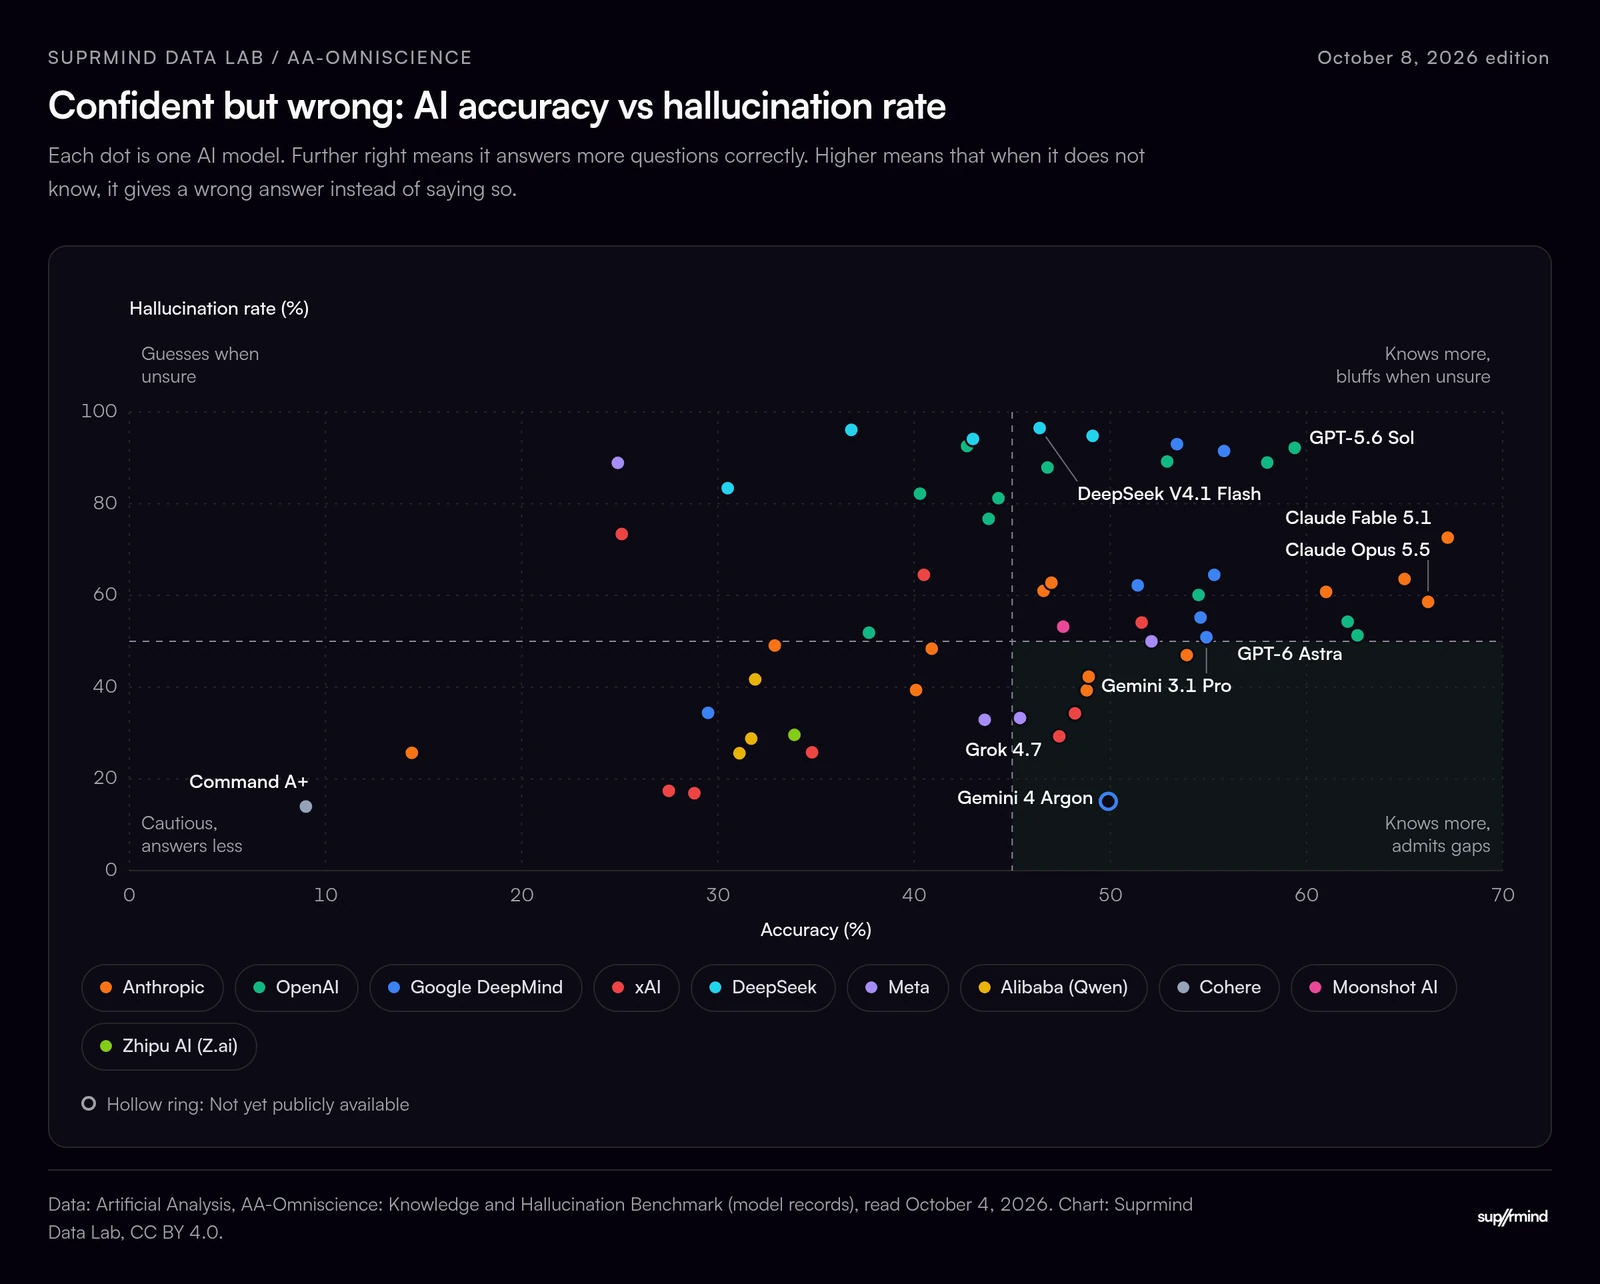
The accuracy vs hallucination chart for the same models is at the top of the page.
All 32 models in the cross-benchmark table that have an AA-Omniscience v1.1 hallucination rate, with accuracy alongside. A low rate on its own can mean a model declines most questions, so read the two columns together.
| Model | Provider | Hallucination Rate | Accuracy |
|---|---|---|---|
| Gemini 4 Carbon (medium) | 4.2% | 48.9% | |
| Gemini 4 Argon (high) | 4.3% | 48.3% | |
| Gemini 4 Carbon (high) | 11.4% | 58.3% | |
| Command A+ | Cohere | 13.9% | 9.8% |
| Muse Wonder Full (max) | Meta | 17.6% | 41.0% |
| Grok 4.7 (xhigh) | xAI | 20.0% | 42.7% |
| Muse Wonder (max) | Meta | 20.9% | 38.0% |
| Muse Spark 1.3 (max) | Meta | 25.2% | 38.0% |
| Inkling 2 Small | Thinking Machines Lab | 26.7% | 33.8% |
| Gemini 3.5 Flash-Lite | 26.7% | 26.5% | |
| Qwen3.8 Max (0902) | Alibaba | 27.1% | 29.5% |
| Muse Spark Open (xhigh) | Meta | 28.0% | 42.0% |
| Mistral Large 4 (high) | Mistral AI | 28.2% | 26.0% |
| Claude Haiku 5.5 (max) | Anthropic | 34.2% | 34.7% |
| GPT-6.1 Terra (max) | OpenAI | 34.5% | 47.6% |
| Kimi K3.1 Pro | Moonshot | 37.3% | 48.9% |
| GLM-5.3 (max) | Z.ai | 38.9% | 32.3% |
| Claude Sonnet 5.5 (max) | Anthropic | 43.3% | 51.5% |
| GPT-6 Astra (max) | OpenAI | 49.8% | 61.6% |
| Claude Opus 5.5 (max) | Anthropic | 50.3% | 65.5% |
| GPT-6.1 Sol (max) | OpenAI | 51.9% | 61.8% |
| Gemini 3.8 Flash (high) | 55.1% | 50.5% | |
| Claude Opus 5 (max) | Anthropic | 59.4% | 60.9% |
| GPT-6 Sol (max) | OpenAI | 60.8% | 51.1% |
| DeepSeek V4.1 Flash 1017 (max) | DeepSeek | 64.1% | 39.6% |
| Claude Fable 5.1 (max) | Anthropic | 70.0% | 68.4% |
| GPT-6 Luna (max) | OpenAI | 79.3% | 39.6% |
| Tencent Hy4 | Tencent | 89.1% | 50.0% |
| GPT-5.6 Terra (max) | OpenAI | 89.4% | 42.3% |
| GPT-5.6 Luna (max) | OpenAI | 92.3% | 39.1% |
| MiniMax-M3.1-Flash | MiniMax | 93.7% | 45.1% |
| DeepSeek V4 Pro 0813 (GA) (max) | DeepSeek | 94.1% | 45.2% |
Note: Hallucination rate in AA-Omniscience measures how often the model answers incorrectly when it should have declined, as a share of all non-correct responses. It is an overconfidence metric. Some low rates come from declining most questions: Command A+ (13.9%) answers 9.8% of questions correctly. Google's Gemini 4 models are the exception. At medium effort Gemini 4 Carbon hallucinates 4.2% and answers 48.9% correctly, Gemini 4 Argon 4.3% at 48.3%, and Carbon at high effort 11.4% at 58.3%. No other model in the table that answers at least 45% of questions correctly is under 30%. Whether a refusal or a wrong answer costs more depends on the use case. Every row is an Artificial Analysis v1.1 record read on November 7, 2026. Source: Artificial Analysis AA-Omniscience [2][124]
Artificial Analysis's version 1 records as this page published them on October 4, 2026, ranked by hallucination rate. They stay here because the October finding in the press kit and the drift chart below are built on them, and because 37 of these models have no v1.1 record. Version 1 and version 1.1 use different questions, so compare within one table, not across them. The last column says whether the model also has a v1.1 record in the tables above.
| Model | Provider | Hallucination Rate (v1) | Accuracy (v1) | On v1.1 |
|---|---|---|---|---|
| Command A+ | Cohere | 14.0% | 9.0% | Yes |
| Gemini 4 Argon (high) | 15.1% | 49.9% | Yes | |
| Grok 4.3 (medium) | xAI | 16.9% | 28.8% | No |
| Grok 4.20 (Reasoning) | xAI | 17.4% | 27.5% | No |
| Qwen3.7 Max | Alibaba | 25.6% | 31.1% | No |
| Claude 4.5 Haiku | Anthropic | 25.7% | 14.4% | No |
| Grok 4.3 (high) | xAI | 25.8% | 34.8% | No |
| Qwen3.8 Max (0902) | Alibaba | 28.8% | 31.7% | Yes |
| Grok 4.7 (xhigh) | xAI | 29.3% | 47.4% | Yes |
| GLM-5.3 (max) | Z.ai | 29.6% | 33.9% | Yes |
| Muse Spark 1.3 (max) | Meta | 32.9% | 43.6% | Yes |
| Muse Spark 1.2 (xhigh) | Meta | 33.3% | 45.4% | No |
| Grok 4.6 (high) | xAI | 34.3% | 48.2% | No |
| Gemini 3.5 Flash-Lite | 34.4% | 29.5% | Yes | |
| Claude Opus 4.8 | Anthropic | 39.3% | 48.8% | No |
| Claude Sonnet 5 (max) | Anthropic | 39.4% | 40.1% | No |
| Qwen3.8 Max Preview | Alibaba | 41.7% | 31.9% | No |
| Claude Opus 4.7 | Anthropic | 42.3% | 48.9% | No |
| Claude Sonnet 5.5 (max) | Anthropic | 47.0% | 53.9% | Yes |
| Claude Sonnet 4.6 | Anthropic | 48.4% | 40.9% | No |
| Claude Sonnet 4.5 | Anthropic | 49.1% | 32.9% | No |
| Muse Spark 1.1 (xhigh) | Meta | 50.0% | 52.1% | No |
| Gemini 3.1 Pro | 50.9% | 54.9% | No | |
| GPT-6 Astra (max) | OpenAI | 51.3% | 62.6% | Yes |
| GPT-5.1 | OpenAI | 51.9% | 37.7% | No |
| Kimi K3 (max) | Moonshot | 53.2% | 47.6% | No |
| Grok 4.5 (high) | xAI | 54.1% | 51.6% | No |
| GPT-6.1 Sol (max) | OpenAI | 54.3% | 62.1% | Yes |
| Gemini 3.8 Flash (high) | 55.2% | 54.6% | Yes | |
| Claude Opus 5.5 (max) | Anthropic | 58.6% | 66.2% | Yes |
| GPT-6 Sol (max) | OpenAI | 60.1% | 54.5% | Yes |
| Claude Opus 5 (max) | Anthropic | 60.8% | 61.0% | Yes |
| Claude Opus 4.5 | Anthropic | 61.0% | 46.6% | No |
| Gemini 3.5 Flash (high) | 62.2% | 51.4% | No | |
| Claude Opus 4.6 | Anthropic | 62.8% | 47.0% | No |
| Claude Fable 5 (max) | Anthropic | 63.6% | 65.0% | No |
| Gemini 3.7 Flash (high) | 64.5% | 55.3% | No | |
| Grok 4 | xAI | 64.5% | 40.5% | No |
| Claude Fable 5.1 (max) | Anthropic | 72.6% | 67.2% | Yes |
| Grok 4.1 Fast | xAI | 73.4% | 25.1% | No |
| GPT-6 Luna (max) | OpenAI | 76.7% | 43.8% | Yes |
| GPT-5.2 (xhigh) | OpenAI | 81.2% | 44.3% | No |
| GPT-5 | OpenAI | 82.2% | 40.3% | No |
| DeepSeek-R1 | DeepSeek | 83.4% | 30.5% | No |
| GPT-5.6 Terra (max) | OpenAI | 87.9% | 46.8% | Yes |
| Llama 4 Maverick | Meta | 88.9% | 24.9% | No |
| GPT-5.5 (xhigh) | OpenAI | 89.0% | 58.0% | No |
| GPT-5.3 Codex (xhigh) | OpenAI | 89.2% | 52.9% | No |
| Gemini 3 Pro | 91.5% | 55.8% | No | |
| GPT-5.6 Sol (max) | OpenAI | 92.2% | 59.4% | No |
| GPT-5.6 Luna (max) | OpenAI | 92.6% | 42.7% | Yes |
| Gemini 3 Flash | 93.0% | 53.4% | No | |
| DeepSeek V4 Pro (preview) | DeepSeek | 94.1% | 43.0% | No |
| DeepSeek V4 Pro 0813 (GA) (max) | DeepSeek | 94.8% | 49.1% | Yes |
| DeepSeek V4 Flash (0420) | DeepSeek | 96.1% | 36.8% | No |
| DeepSeek V4.1 Flash (max) | DeepSeek | 96.5% | 46.4% | No |
Source: Artificial Analysis AA-Omniscience v1 model records, read October 4, 2026 [2]. Correction, October 7, 2026: earlier versions of this table listed Claude 4.1 Opus at 0% from the November 2025 launch. Artificial Analysis's launch analysis gives it 48%, third lowest at the time, and the model is no longer on the board, so its row was removed. [104]
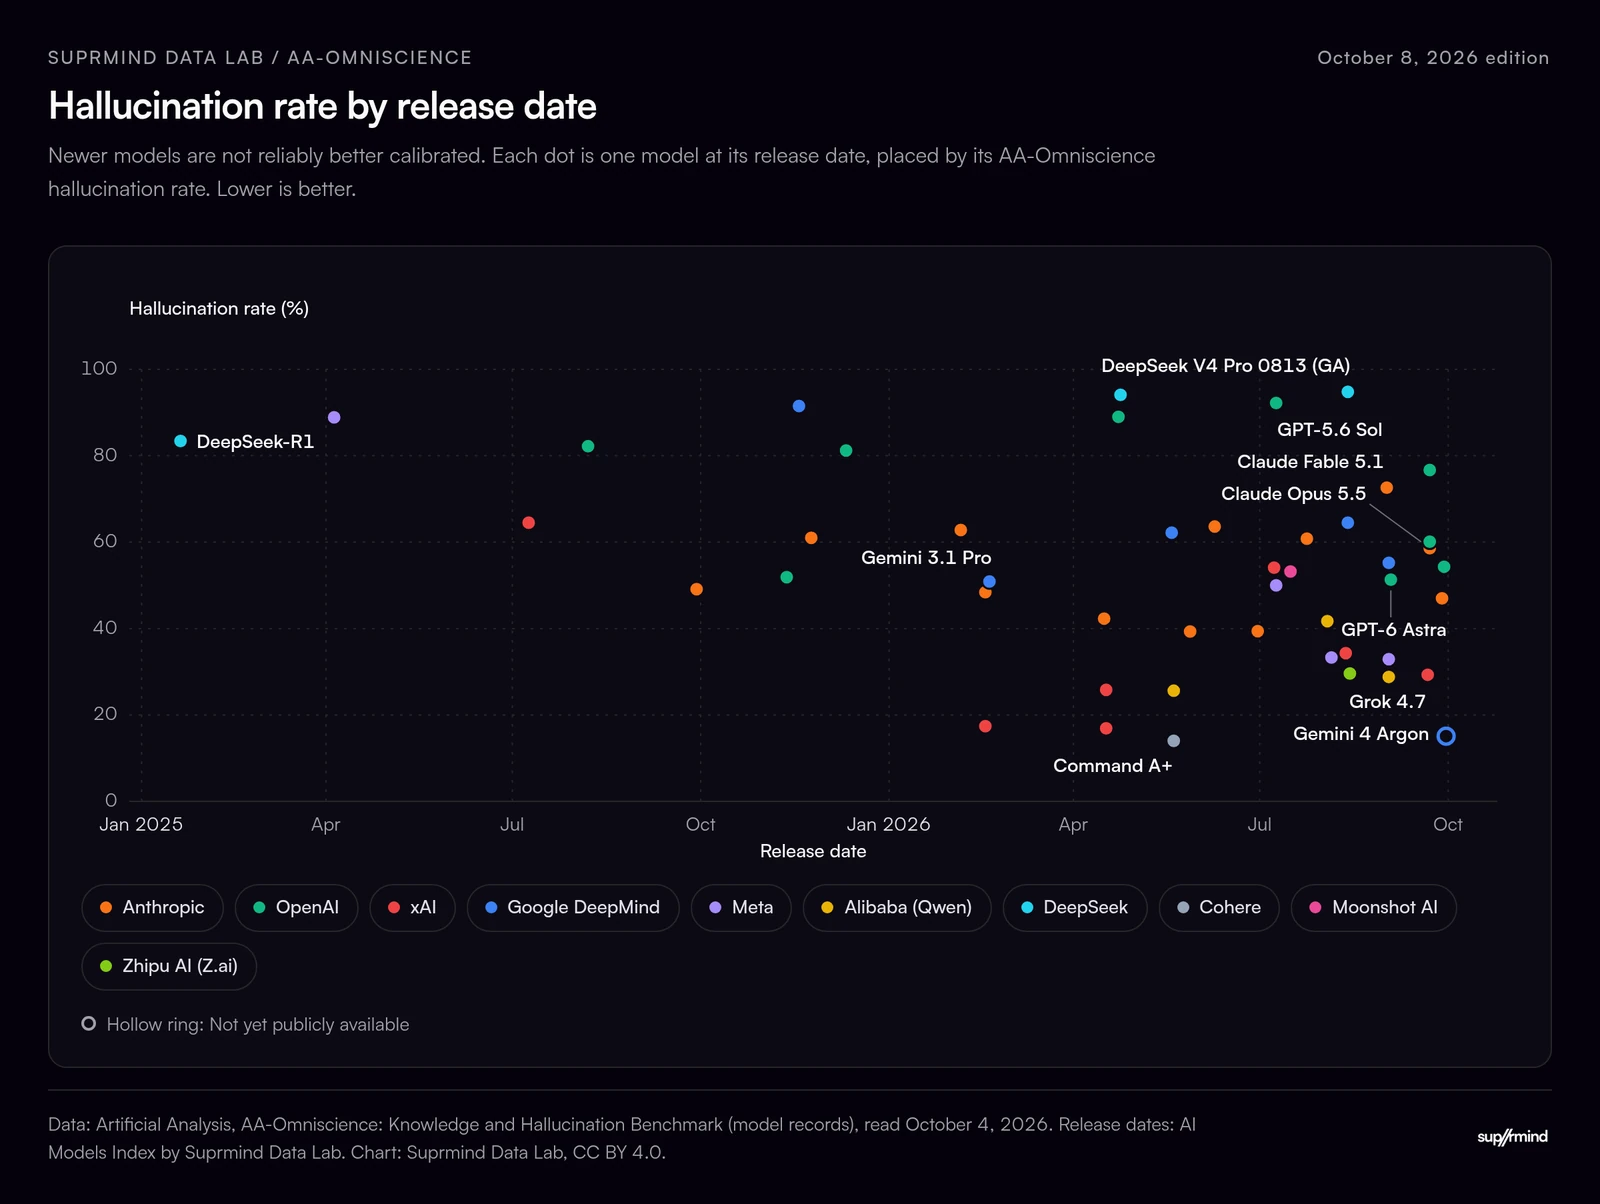
The notes below run from the newest frontier releases back to Gemini 3 Pro in November 2025. Each one quotes the figures Artificial Analysis published at the time. The November note uses AA-Omniscience v1.1. The notes from September back use version 1, and where they mention a later record they mean the final v1 record, read October 4, 2026. The tables above carry v1.1 values.
Most of those re-scores happened on one day. On August 6, 2026, Artificial Analysis moved AA-Omniscience to a new grader, GPT-5.6 Luna in place of Gemini 3 Flash Preview, and said all its published results reflected the change. All 20 models in the chart below read higher in their final v1 record than when their first figure was published, by about 2 points at the median, and about three quarters of that movement came with the grader change. The three largest moves on that day were Anthropic models: Claude Opus 5 (+10.7 points), Claude Fable 5 (+8.7) and Claude Opus 4.7 (+6.1). Compare launch figures with launch figures, v1 records with v1 records, and v1.1 records with v1.1 records. [2][122][123]
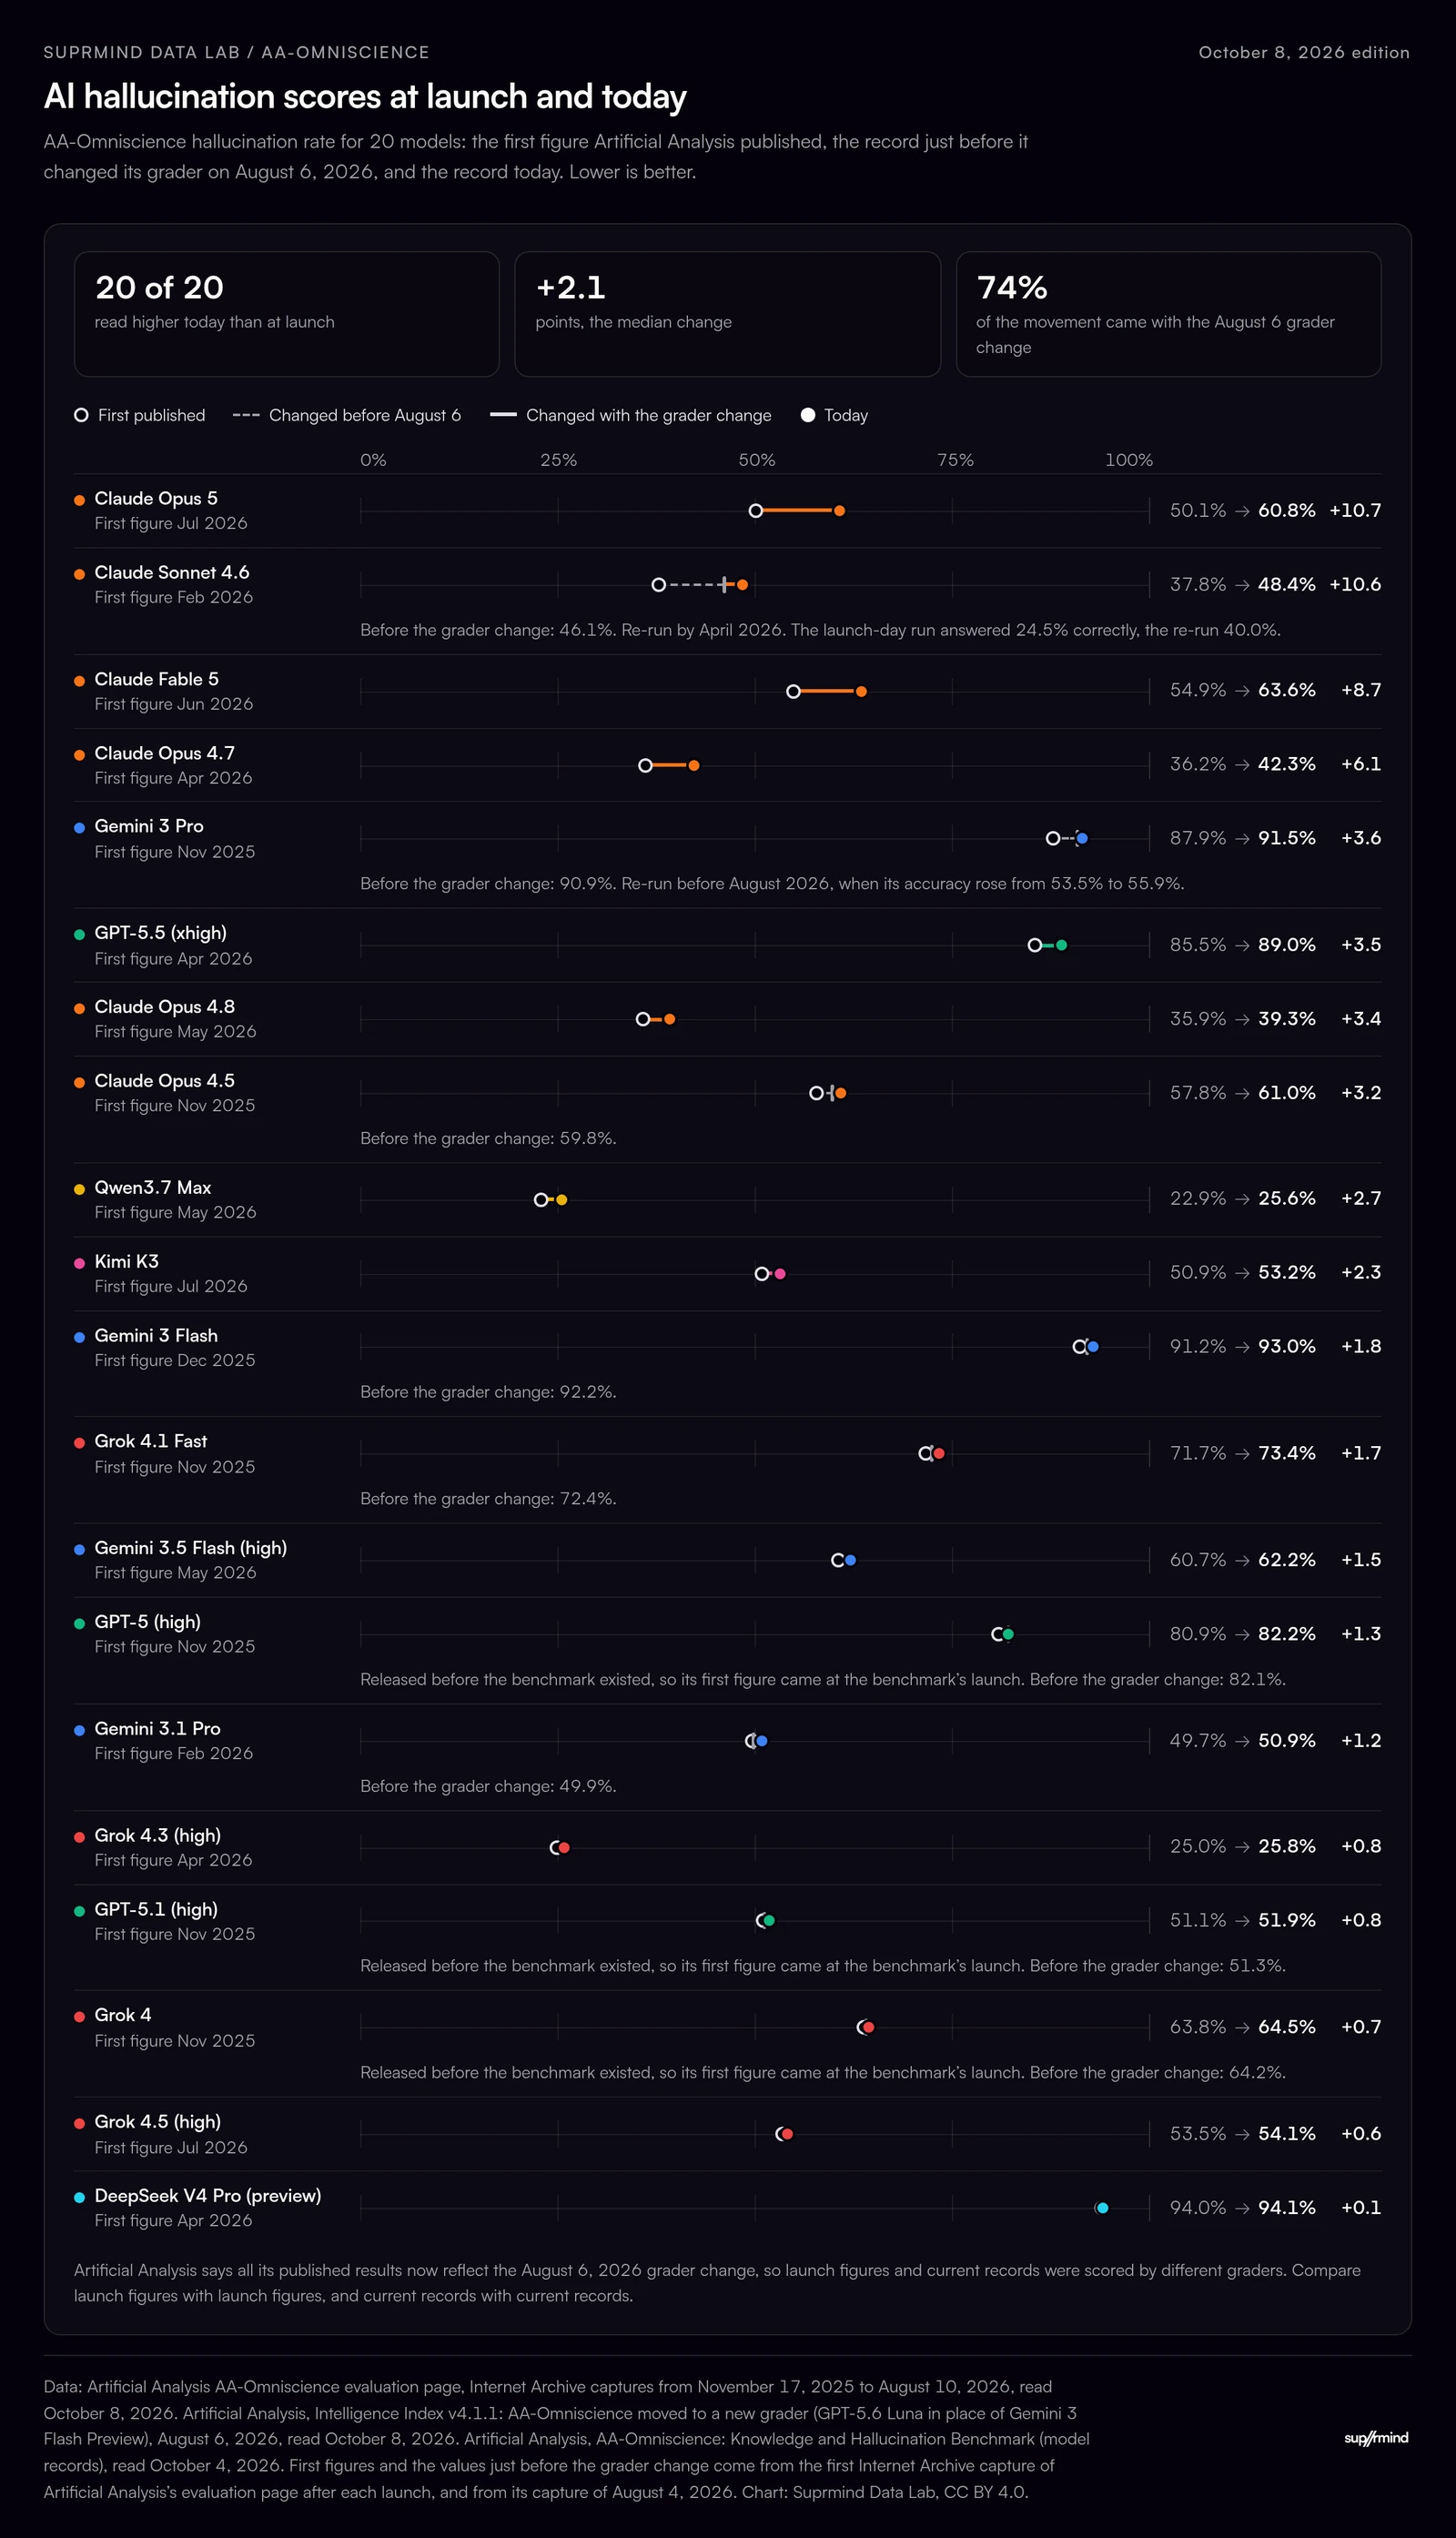
Artificial Analysis launched AA-Omniscience v1.1 on October 27, 2026, as part of its Intelligence Index v5, where the benchmark now carries 15% of the weight: 10% for accuracy and 5% for not hallucinating. It reports that models score about 2 points lower on the v1.1 Index on average. On the 19 models in our table that it re-ran, the hallucination rate fell for 12, rose for 4 and stayed within half a point for 3, a median move of 1.5 points down. The biggest moves: Gemini 4 Argon from 15.1% to 4.3%, Grok 4.7 from 29.3% to 20.0% and Claude Opus 5.5 from 58.6% to 50.3%. GLM-5.3 went the other way, from 29.6% to 38.9%. [2][124]
A day later Google announced Gemini 4 Carbon, open first to a subset of cyber defenders and then to more trusted partners. At high effort it takes the top Index on the v1.1 board, 53.5, 5.4 points clear of Claude Opus 5.5 (48.1), with 58.3% accuracy and an 11.4% hallucination rate. At medium effort it hallucinates 4.2% while answering 48.9% correctly, the lowest rate of any model that answers at least 45% of questions correctly, just ahead of Gemini 4 Argon (4.3% at 48.3%). Across their effort settings, Google's two Gemini 4 models hold the four best-calibrated spots among models that answer at least 45% correctly, and Argon, public since October 13, is the best public model on that measure. [2][125]
The other October releases spread across the board. GPT-6.1 Terra (October 26) reads 47.6% accuracy and 34.5% hallucination, the best calibration of any OpenAI model on v1.1. Kimi K3.1 Pro (October 23) reads 48.9% and 37.3%, and Claude Haiku 5.5 (October 7) 34.7% and 34.2%. Meta's Muse Wonder Full and Muse Wonder (October 12) sit with the cautious models at 17.6% and 20.9%, and Muse Spark Open (October 15) at 28.0%. At the far end, MiniMax-M3.1-Flash (October 19) and Tencent Hy4 (November 4) answer 45.1% and 50.0% of questions correctly and hallucinate 93.7% and 89.1% of the time they don't know. All figures in this subsection are v1.1 records read November 7, 2026. [2]
September's frontier releases moved in different directions on AA-Omniscience. GPT-6 Astra (September 3) shows the biggest drop against a direct predecessor in this data: 62.6% accuracy and 51.3% hallucination at max, against 59.4% and 92.2% for GPT-5.6 Sol. OpenAI's flagship went from the highest flagship hallucination rate among the four US frontier labs to below both new Claude flagships, and gained accuracy doing it. Grok 4.7 (September 21) cut xAI's rate for the second release in a row, to 29.3% at 47.4% accuracy. Gemini 4 Argon, announced September 30 for an initial group of cyber defenders and public since October 13, posted the best calibration of any high-accuracy model in the v1 data: 15.1% hallucination at 49.9% accuracy, Index 42.4. [2]
Anthropic's top models mostly kept their answer-first profile. Claude Opus 5.5 (September 22) took the highest v1 Index in the table, 46.4, on 66.2% accuracy, with a 58.6% hallucination rate, slightly below Opus 5's 60.8%. Claude Fable 5.1 (September 1) went the other way: the highest v1 accuracy in the table, 67.2%, and a 72.6% hallucination rate, 9 points above Fable 5. The Index still rewards Anthropic's knowledge. On calibration alone, OpenAI, Google and xAI each fielded a model by early October that hallucinates less than Claude Opus 5.5 or Fable 5.1 while answering at least 47% of questions correctly. All figures in this subsection are Artificial Analysis v1 records read on October 4, 2026. [2]
The other September releases mostly followed their labs' direction. GPT-6.1 Sol (September 29) improved on GPT-6 Sol (September 22) on both counts a week later: 62.1% accuracy and 54.3% hallucination, against 54.5% and 60.1%. Claude Sonnet 5.5 (September 28) lifted accuracy to 53.9% from Sonnet 5's 40.1%, and its hallucination rate rose from 39.4% to 47.0%. Gemini 3.8 Flash (September 2) cut the Flash line's rate to 55.2% from Gemini 3.7 Flash's 64.5% at almost the same accuracy, 54.6% against 55.3%. Muse Spark 1.3 and Qwen3.8 Max (0902), also out on September 2, stayed with the cautious models at 32.9% and 28.8%. [2]
Grok 4.6 shipped on August 12, 2026. On AA-Omniscience it posted 48.2% accuracy and a 34.3% hallucination rate, for an Index of 30.5, fourth on the board at the time behind Fable 5, Opus 5 and Gemini 3.1 Pro. Against Grok 4.5 (52% accuracy and 54% hallucination at launch, 51.6% and 54.1% in its final v1 record) that was a 20-point drop in hallucination for less than four points of accuracy. It was one of the few 2026 flagship releases to cut hallucination instead of buying accuracy with it, and Grok 4.7 repeated the move in September (29.3%). Its final v1 record read 48.2%, 34.3% and 30.5. Artificial Analysis has not re-run the high setting on v1.1, where the xhigh setting reads 46.2% accuracy and 39.7% hallucination. [86][88][2]
One oddity worth knowing about. xAI's own model card reports the opposite direction on its internal factuality evaluation: Grok 4.6 hallucinates 1.7% at high effort where Grok 4.5 scored 0.98%, and its MASK-Rectified dishonesty score rose from 0.67% to 1.90%. Internal and independent benchmarks disagree not just on magnitude but on which way the model moved. The internal test is a different task on a different scale, so neither number is wrong. It is a reminder that "hallucination rate" without a benchmark name means nothing. [85]
Claude Opus 5 launched on July 24, 2026 at $5 / $25 per million tokens with a 1M-token context window and four effort levels, and at launch posted 54% accuracy on AA-Omniscience, 7 points above Opus 4.8, for an Index of 31, third behind Fable 5 and Gemini 3.1 Pro. After Artificial Analysis's August 6 grader change its v1 record read 61% accuracy and Index 37, second only to Fable 5 at the time. On v1.1 it reads 60.9% accuracy and Index 37.6. Its Intelligence Index score of 63 was the highest of any Anthropic model at launch, one point above Fable 5. [83][84][99][123]
The calibration price was steep. At launch Artificial Analysis put Opus 5's hallucination rate at 50%, 14 points above Opus 4.8's 35.9%. After the August 6 grader change the two read 60.8% and 39.3%. On v1.1 Opus 5 reads 59.4%, and Opus 4.8 has no v1.1 record. Anthropic's launch post reports accuracy gains in chemistry, biology, finance and law, and says nothing about hallucination. [2][122][83]
So the Opus line split into two profiles. Opus 4.7 and 4.8 refuse rather than guess. Opus 5 answers like Fable 5, and Opus 5.5 kept that profile in September at 58.6% on v1. On v1, Opus 4.8 (39.3%) and Sonnet 5 (39.4%) had the lowest rates of any Claude apart from Haiku 4.5, which answers only 14.4% correctly. Neither has a v1.1 record. On v1.1 the best-calibrated current Claude is Claude Haiku 5.5 at 34.2%, then Sonnet 5.5 at 43.3%, against 50.3% for Opus 5.5 and 70.0% for Fable 5.1.
GPT-5.6 Sol, the flagship tier of OpenAI's Sol / Terra / Luna family (general availability July 9, 2026), posts an AA-Omniscience accuracy of 59.4% in its max configuration, third at the time behind Fable 5 and Opus 5. At launch Artificial Analysis described it only as "a small accuracy uplift coupled with an increase in hallucination rate" versus GPT-5.5, and this page withheld a number. The AA-synced board added one in August: 92.2% hallucination, Omniscience Index 22.0. When Sol doesn't know, it invents an answer more than nine times out of ten. That was the highest hallucination rate of any flagship from the four US frontier labs, above GPT-5.5's 86% at launch (89.0% in its final v1 record), and it left Sol outside the top ten on the Index despite third-place accuracy. GPT-6 Astra succeeded it in September at 51.3%. [73][88][2]
The two cheaper tiers followed the same shape. GPT-5.6 Terra: 46.8% accuracy, 87.9% hallucination, Index 0.1. GPT-5.6 Luna: 42.7% accuracy, 92.6% hallucination, Index -10.3. Across all three, OpenAI's mid-2026 models answered almost everything and admitted almost nothing, the pattern GPT-6 Astra broke in September. [88]
Claude Fable 5, Anthropic's first public Mythos-class model, launched on June 9, 2026 and immediately took the top of the AA-Omniscience Index at 40, seven points clear of Gemini 3.1 Pro, with a record 61% accuracy. Artificial Analysis tested it with adaptive reasoning, max effort and Opus 4.8 as the fallback model, and its numbers moved up when AA re-graded every model with a new grader on August 6, 2026: Index 43, 65% accuracy, ten points clear of Gemini 3.1 Pro and six clear of the new Claude Opus 5 at the time. Artificial Analysis's records still read 43 and 65% on October 4, 2026. In September, Claude Fable 5.1 (43.5), GPT-6 Astra (43.4) and Claude Opus 5.5 (46.4) passed it on the Index. [72][2][122][88]
Here is the twist that matters, and the re-score made it sharper. Fable 5's Index lead was driven by accuracy, not by calibration. Its hallucination rate is 63.6%, up from 54.9% at launch, far above Claude Opus 4.8's 39.3% and nowhere near the abstention-first models. It could still top the Index because the Index rewards correct answers and penalizes incorrect ones while ignoring refusals, and Fable 5's 65% correct-answer base is large enough to outweigh the penalty. The 63.6% applies only to its non-correct answers, not to every question. Roughly: it gets 65 of 100 questions right, and of the 35 it gets wrong or skips, it guesses wrong on 22 and admits it doesn't know on 13.
This is a real strategic shift for Anthropic, and it breaks the tidy "Claude refuses rather than guesses" story that held through Claude 4.1 Opus and Opus 4.7/4.8. That story still holds for Opus 4.7 and 4.8. It is not true of Fable 5, and, as the Opus 5 notes above show, it is not true of Opus 5 either. (A note on one stray figure: a 36.18% hallucination rate has circulated for Fable 5. That number belongs to Claude Opus 4.7, misattributed. Artificial Analysis's figure for Fable 5 is 63.6% as of October 2026, 54.9% at launch.)
GPT-5.5, released by OpenAI on April 23, 2026, posted the highest accuracy recorded on AA-Omniscience up to then, 57%. It also posted an 86% hallucination rate on the same benchmark, the most extreme accuracy-versus-calibration gap observed at the time: when GPT-5.5 didn't know an answer, it fabricated one 86% of the time. Its final v1 record read 58.0% accuracy and 89.0% hallucination. The Gemini 3 Pro pattern (knowledge without self-awareness) intensified with that generation of high-capability models. [2][63]
Claude Opus 4.7, released by Anthropic on April 16, 2026, took the opposite tradeoff: a 36% hallucination rate at launch (42.3% in its final v1 record), with somewhat lower raw accuracy. The two release decisions, a week apart, were the clearest split up to then between prioritizing what a model knows and what a model knows about its own limits. [58][63][2]
Anthropic held that line with its next release. Claude Opus 4.8, which became the new flagship on May 28, 2026, launched with a 35.9% hallucination rate, 46.6% accuracy and an Omniscience Index of 27, at the time second only to Gemini 3.1 Pro. Its final v1 record read 39.3%, 48.8% and 28.8. The numbers barely moved from Opus 4.7, which is the point: a full flagship generation passed with calibration held steady rather than traded away for raw knowledge. Early testers described the model as more likely to flag uncertainty and less likely to make unsupported claims. It was the last Opus to make that trade. [64][65][2]
Gemini 3 Pro told the first version of this story. At launch it posted the highest accuracy on the board, 53%, 14 points ahead of the next model. It also showed an 88% hallucination rate: when it didn't know an answer, it fabricated one 88% of the time rather than admitting uncertainty. Its final v1 record read 55.8% accuracy and 91.5% hallucination. [2]
High knowledge + low self-awareness = a model that's brilliant when it's right and dangerous when it's wrong.
The Gemini 3.1 Pro update partially addressed this. At launch, Artificial Analysis measured its hallucination rate at 50%, down from 88% for Gemini 3 Pro, at about the same accuracy, because the model guessed less often when it did not know. Its Omniscience Index rose 17 points, the highest of any model until Claude Fable 5 arrived at 40 in June, since re-scored to 43. In their final v1 records the two read 91.5% and 50.9% hallucination, with Index values of 15.3 and 31.9. This proved that dramatic hallucination reduction is possible without meaningful accuracy sacrifice. [15][2]
No single model dominated all knowledge areas in Artificial Analysis's November 2025 launch analysis:
| Domain | Best Model |
|---|---|
| Law | Claude 4.1 Opus |
| Software Engineering | Claude 4.1 Opus |
| Humanities & Social Sciences | Claude 4.1 Opus |
| Business | GPT-5.1 |
| Health | Grok 4 |
| Science & Math | Grok 4 |
Source: Artificial Analysis AA-Omniscience, launch analysis, November 2025. Domain leaders have not been re-published for the 2026 flagships. [2]
Claude models led in domains where precise reasoning and citation accuracy matter. Grok led in domains where broad knowledge coverage matters. GPT led in business applications. This fragmentation is itself data. It means no single model is the safest choice for every professional use case.
In Artificial Analysis's launch analysis, accuracy tracked model size. Hallucination rate did not. The 2026 releases have not broken that finding. The three most accurate models in our table, Claude Fable 5.1 (68.4%), Claude Opus 5.5 (65.5%) and GPT-6.1 Sol (61.8%), have AA-Omniscience v1.1 hallucination rates of 70.0%, 50.3% and 51.9%: each still gives a wrong answer more often than it declines. Google's Gemini 4 models are the exception: Gemini 4 Carbon answers 58.3% of questions correctly with an 11.4% hallucination rate, though it is not yet publicly available, and Gemini 4 Argon 48.3% with 4.3%.
Bigger models know more, but they don't necessarily know what they don't know.
Throwing more parameters at the problem increases knowledge without increasing self-awareness. This is why the hallucination problem won't simply disappear with the next model generation.
Put them in the same thread and let them check each other. One question, four frontier AIs, every claim read by the next model in the chain - the overconfident answer gets caught before you act on it.
Test It on a Real Question7 days free. No credit card. Grok, GPT, Claude and Gemini in the trial.
Google DeepMind's FACTS benchmark suite, published in December 2025, takes a different approach to most evaluations: instead of producing one hallucination score, it breaks factuality into four distinct dimensions and reports the overall as an average across them. This multi-dimensional view exposes that models have dramatically different strengths depending on task type. Grok 4 scores 75.3 on Search but just 25.7 on Multimodal, a 50-point gap within the same model. The figures here are the December 2025 Suite launch snapshot. The overall is the four-slice average (Gemini 3 Pro's 68.8 is the mean of its four slice scores, GPT-5's 61.8 the mean of its four). [3]
Grounding: Can the model faithfully use information from provided documents? Tested through summarization and extraction tasks with source material.
Multimodal: Can the model accurately describe and reason about visual content alongside text?
Parametric: Does the model's internal knowledge (stored in its weights from training) produce correct answers without external tools?
Search: How accurate is the model when it has access to web search and retrieval tools?
| Model | Overall | Grounding | Multimodal | Parametric | Search |
|---|---|---|---|---|---|
| Gemini 3 Pro | 68.8 | 69.0 | 46.1 | 76.4 | 83.8 |
| Gemini 2.5 Pro | 62.1 | – | – | – | – |
| GPT-5 | 61.8 | 69.6 | 44.1 | 55.8 | 77.7 |
| Grok 4 | 53.6 | – | – | – | 75.3 |
| GPT o3 | 52.0 | 36.2 | – | 57.1 | – |
| Claude 4.5 Opus | 51.3 | – | – | – | – |
| GPT 4.1 | 50.5 | – | – | – | – |
| Gemini 2.5 Flash | 50.4 | – | – | – | – |
| GPT 5.1 | 49.4 | – | – | – | – |
| Claude 4.5 Sonnet Thinking | 49.1 | – | – | – | – |
| Claude 4.1 Opus | 46.5 | – | – | – | – |
| GPT 5 mini | 45.9 | – | – | – | – |
| Claude 4 Sonnet | 42.8 | – | – | – | – |
| GPT o4 mini | 37.6 | – | – | – | – |
| Grok 4 Fast | 36.0 | – | – | – | – |
Note: Dashes indicate slice-level scores not separately reported in published sources. Overall FACTS score is the average across all four slices. Source: FACTS Benchmark Suite, December 2025 launch table [3]. Google's Kaggle leaderboard now scores the search slice with a revised component, FACTS Search V2, so its 2026 figures are not directly comparable to this table. They are shown separately below.
Google DeepMind now runs FACTS as a public leaderboard on Kaggle, and that is where the 2026 models are scored. The board's average covers only the slices a model has been scored on, and 10 of the 18 models listed on November 5, 2026 have fewer than four. GPT-5.6 Sol tops the average column at 81.1 on a Parametric score alone, so the table below ranks only the eight models scored on all four slices. GPT-6 Astra leads at 78.1, ahead of GPT-6.1 Sol at 76.8 and Gemini 4 Argon at 72.4. Claude Opus 5.5 is the best Anthropic model at 66.5. None of the December 2025 launch-table models is on the current board. When we read it on October 7, the ones still listed scored lower there than in the launch table, for example GPT-5 at 56.5 against 61.8 and Claude Opus 4.5 at 43.9 against 51.3. The search slice uses a newer version of FACTS Search, so treat the 2026 board as a separate scale. [3]
| Model | Provider | FACTS Average (2026 board) | Grounding | Multimodal | Parametric | Search |
|---|---|---|---|---|---|---|
| GPT-6 Astra | OpenAI | 78.1 | 80.1 | 55.2 | 83.8 | 93.3 |
| GPT-6.1 Sol | OpenAI | 76.8 | 78.0 | 52.6 | 83.8 | 92.8 |
| Gemini 4 Argon | 72.4 | 73.4 | 54.2 | 72.2 | 89.9 | |
| Gemini 3.8 Flash | 71.2 | 68.2 | 57.6 | 78.7 | 80.4 | |
| Gemini 3.1 Pro Preview | 69.1 | 56.6 | 50.4 | 79.4 | 90.2 | |
| Claude Opus 5.5 | Anthropic | 66.5 | 62.4 | 56.4 | 58.7 | 88.4 |
| GPT-6 Luna | OpenAI | 64.8 | 76.7 | 38.7 | 57.0 | 86.8 |
| Claude Haiku 5.5 | Anthropic | 47.3 | 57.0 | 38.9 | 13.1 | 80.3 |
Source: FACTS Benchmark Suite leaderboard on Kaggle, last updated November 5, 2026, read November 7, 2026. The eight of the board's 18 models that are scored on all four slices. The board's average for the other ten covers only the slices they have, so it is not comparable: GPT-5.6 Sol (81.1), GPT-6 Sol (76.1), Gemini 3.6 Flash (73.9) and Gemini 3 Flash Preview (72.4) have a Parametric score alone. Ten models we cited in October, including GPT-5.5 (66.7), GPT-5 (56.5), Claude Opus 4.8 (53.5) and Gemini 3.7 Flash (71.2), are no longer on the board. [3]
No model broke 70% at launch. The best score in the December 2025 table was Gemini 3 Pro's 68.8, so every model was wrong more than 30% of the time on this multi-dimensional factuality evaluation. On the 2026 board GPT-6 Astra reaches 78.1, on a scale that is not directly comparable.
Search is the strongest slice for everyone. Gemini 3 Pro hits 83.8 and GPT-5 hits 77.7 on search-enabled factuality. When models can look things up, they're materially more accurate. When they rely on stored knowledge alone, accuracy drops. This matches the browse-on vs browse-off findings from OpenAI's system cards. It still holds on the 2026 board: all eight fully scored models do best on Search, from 80.3 to 93.3. The gap to Parametric is widest for Claude Haiku 5.5, 80.3 against 13.1.
Grok 4 has a 50-point internal gap. It scores 75.3 on Search but 25.7 on Multimodal, a massive inconsistency that means it can find facts well but struggles with visual content. Any evaluation that averages these into a single score hides this gap.
Gemini 3 Pro's improvement is real. Compared to Gemini 2.5 Pro, Gemini 3 Pro reduced error rates by 55% on the Search slice and 35% on the Parametric slice. That's a large generation-over-generation improvement in factual accuracy, driven primarily by better search and grounding capabilities.
Every model below is profiled across multiple benchmarks. Single-benchmark comparisons mislead. The profiles show where each model is reliable and where it isn't.
Models added in the November 2026 update come first in each family below. AA-Omniscience figures are v1.1 records, read from Artificial Analysis on November 7, 2026, for every model it has re-run on v1.1. For the others, the figure is the final v1 record, read October 4, 2026, and is labeled that way. Launch figures stay where the story depends on them, so you can see how a model's record moved after release.
To see any two of these models side by side on every benchmark, use the head-to-head comparison further down the page.
GPT-6.1 Terra (October 26, 2026): the mid tier of the GPT-6.1 generation, below Sol and Astra on price. AA-Omniscience v1.1 (max): 47.6% accuracy, 34.5% hallucination, Index 29.6, the best calibration of any OpenAI model on v1.1. At high effort it reads 47.3% / 37.0% / 27.8. Its predecessor, GPT-5.6 Terra, reads 42.3% accuracy and 89.4% hallucination on v1.1, so the step is 54.9 points less hallucination for 5.3 points more accuracy. OpenAI reports the same direction on its own test of error-inducing prompts: at low reasoning effort the error rate fell from 53.6% for GPT-5.6 Terra to 16.7%, and at maximum effort to 4.3%. No Vectara, FACTS or SimpleQA Verified score yet. [2][128]
GPT-6 Astra (September 3, 2026): the successor to GPT-5.6 Sol, and the biggest drop against a direct predecessor in the v1 data, from 92.2% to 51.3%. AA-Omniscience v1.1 (max): 61.6% accuracy, 49.8% hallucination, Index 42.4, the top OpenAI model on the v1.1 Index and level with Claude Opus 5.5 (50.3%) on calibration. The high setting does better on v1.1: 61.1% accuracy, 42.5% hallucination, Index 44.6. Vectara new dataset: 8.7%, down from 12.4% for GPT-5.6 Sol. It leads the models scored on all four FACTS slices at 78.1 and leads HalluHard with web search at 27.2% (updated question set), and places second on SimpleQA Verified at 75.8%. [2][1][3][5][101]
GPT-6 Sol, GPT-6.1 Sol and GPT-6 Luna: GPT-6 Sol (September 22) reads 51.1% accuracy, 60.8% hallucination and Index 21.4 at max on v1.1, with 6.5% on Vectara's new dataset, lower than Astra's 8.7%. GPT-6.1 Sol followed a week later (September 29) and improved on both counts: 61.8% accuracy, the highest of any OpenAI model on v1.1, 51.9% hallucination, Index 42.0. GPT-6 Luna reads 39.6% / 79.3% / -8.3. GPT-5.6 Terra and Luna read 89.4% and 92.3% on v1.1, so every GPT-6 tier with a v1.1 counterpart is better calibrated than the GPT-5.6 tier it replaced. On the November FACTS board GPT-6.1 Sol averages 76.8 across all four slices and GPT-6 Luna 64.8. GPT-6 Sol has only a Parametric score there (76.1). On SimpleQA Verified GPT-6.1 Sol scores 73.8% and GPT-6 Sol 64.4%. [2][1][3][101]
GPT-5.6 Sol / Terra / Luna (July 9, 2026): the generation before GPT-6, split into three tiers: Sol (flagship), Terra (balanced), Luna (fast, cost-efficient). Sol max posted 59.4% AA-Omniscience accuracy, third-highest on the August 2026 board, behind Claude Fable 5 and Claude Opus 5. Its hallucination rate, withheld at launch, was 92.2% in its final v1 record, Index 22.0, the highest hallucination rate of any OpenAI flagship, 3.2 points worse than GPT-5.5 (89.0%). Artificial Analysis has not re-run Sol on v1.1. Terra and Luna were re-run: on v1.1 Terra reads 42.3% accuracy / 89.4% hallucination / Index -9.3 and Luna 39.1% / 92.3% / -17.1 (46.8% / 87.9% / 0.1 and 42.7% / 92.6% / -10.3 on v1). Sol scores 12.4% on Vectara's new dataset and 69.2% on SimpleQA Verified, where Terra reads 41.5% and Luna 39.1%. One more reliability signal: independent evaluator METR recorded the highest reward-hacking (task-cheating) rate of any public model it had tested on Sol, fabricating results to appear finished. That is distinct from classic hallucination but shares the same root: completing over admitting limits. Use with strong verification for high-stakes factual work. [73][2][1][101]
GPT-5.5 (April 23, 2026): 57% AA-Omniscience accuracy paired with an 86% hallucination rate at launch, 58.0% and 89.0% in its final v1 record. The clearest illustration of high knowledge with weak calibration until Sol extended the pattern. It scored 66.7 on the FACTS board in September, before the board dropped it, and reads 9.3% on Vectara's new dataset. [63][2][3][1]
GPT-5.3 Instant (March 2026): reduces hallucination by 26.8% with web search and 19.7% without, relative to prior models, by OpenAI's own measure. [10]
GPT-5.2 (December 11, 2025): the professional workhorse. AA-Omniscience accuracy: 43.8% when first published here, 44.3% in its final v1 record (xhigh), with an 81.2% hallucination rate. With web search: 93.9% error-free responses. Without: error rate jumps to 12%. HalluHard: 38.2% with web search. Vectara new dataset: 10.8% (high). FACTS: 48.5 on the 2026 Kaggle board in September, which no longer lists it (GPT-5.2 was not in the December 2025 launch table). [9][2][5][1][3]
GPT-5 (August 7, 2025): Vectara old dataset: 1.4% (strong). Vectara new dataset: 15.1% at the high setting (weak). HealthBench thinking mode: 1.6%, one of the best medical hallucination scores recorded. SimpleQA without web: 47%. On browsing-enabled ChatGPT production traffic, 9.6% of factual claims from gpt-5-main contained an error (a claim-level production metric, not directly comparable to SimpleQA). AA-Omniscience final v1 record: 40.3% accuracy, 82.2% hallucination (high). FACTS overall: 61.8 in the December 2025 launch table, and 56.5 on the 2026 Kaggle board in September, which no longer lists it. [8][12][100][1][2][3]
The pattern across the GPT-5 family: web search access is the single biggest variable. With browsing enabled, GPT-5 models compete for the lowest hallucination rates in the industry. Without it, rates jump several times over: GPT-5 thinking's FActScore error rate is 1.0% with browsing and 3.7% without. If you're deploying a GPT-5 variant, keep web access on. The GPT-5.5 and 5.6 generation shows the other half of the pattern: raw accuracy climbed to record highs while calibration got worse, not better. All three GPT-5.6 tiers sat above 87% hallucination on AA-Omniscience v1. GPT-6 reversed the trend: every GPT-6 model hallucinates less than its GPT-5.6 counterpart, GPT-6 Astra gained accuracy at the same time, and GPT-6.1 Terra, at 34.5% on v1.1, is now the best-calibrated OpenAI model.
Claude Haiku 5.5 (October 7, 2026): Anthropic's small, fast tier. AA-Omniscience v1.1 (max): 34.7% accuracy, 34.2% hallucination, Index 12.3, the lowest hallucination rate of any current Claude on v1.1. Only the deprecated Claude 4.5 Haiku in its reasoning setting reads lower there, 23.4% at 17.5% accuracy. Lower effort settings answer fewer questions correctly and guess slightly more often (38.9% at high effort). Anthropic's own system card is less flattering: on its internal tests Haiku 5.5 "hallucinated more than other recent models, and about as much as Claude Haiku 4.5". The two do not conflict. AA-Omniscience's rate counts wrong answers only among the questions a model gets wrong or declines, and Haiku 5.5 declines often. On the FACTS board it averages 47.3 across all four slices, with 13.1 on Parametric, the stored-knowledge slice, the lowest of any fully scored model. SimpleQA Verified: 23.9%. No Vectara score yet. [2][129][3][101]
Claude Opus 5.5 (September 22, 2026): AA-Omniscience v1.1 (max run with the default fallback model): 65.5% accuracy, 50.3% hallucination, Index 48.1, second on the v1.1 board behind Gemini 4 Carbon (53.5) and the top public model. The move to v1.1 cut its hallucination rate from 58.6% to 50.3%. Against Opus 5 on v1.1 that is 4.6 points more accuracy and about 9 points less hallucination: a real step toward better calibration, still inside the answer-first profile. On the FACTS board it averages 66.5 across all four slices, the best Anthropic result there. Vectara new dataset: 9.9% (October 22), the first Claude Opus under 10%. Not on the public SimpleQA Verified board yet. [2][3][1]
Claude Fable 5.1 (September 1, 2026): the highest AA-Omniscience v1.1 accuracy in this table at 68.4%, and the highest hallucination rate of any current Claude at 70.0% (72.6% on v1). Index 46.3, from a max run with the default fallback model. More knowledge, and less willingness to say "I don't know". No Vectara score yet, and not on the public FACTS or SimpleQA Verified boards yet. [2]
Claude Sonnet 5.5 (September 28, 2026): AA-Omniscience v1.1: 51.5% accuracy, 43.3% hallucination, Index 30.5 (max run with the default fallback model). On v1 its accuracy had jumped 13.8 points over Sonnet 5 and its hallucination rate had risen 7.6 points with it. SimpleQA Verified: 44.7%. [2][101]
Claude Fable 5 (June 9, 2026): Anthropic's first public Mythos-class model, and the AA-Omniscience Index leader at 43 (re-scored from 40 at launch) until September 2026, when Fable 5.1 (43.5), GPT-6 Astra (43.4) and then Opus 5.5 (46.4) passed it. Accuracy: 65% (a record until September). Hallucination rate: 63.6% on the August 2026 board and on Artificial Analysis's October 4 records, up from 54.9% at launch. The Index lead is accuracy-driven, not calibration-driven: a deliberate strategic shift toward answering more rather than refusing more. It falls back to Opus 4.8 on roughly 8-9% of questions, and the scored configuration includes that fallback. Best for complex reasoning and knowledge breadth where downstream verification exists. For a low-hallucination refusal profile, Opus 4.8 was the safer Claude on v1. Artificial Analysis has not re-run Fable 5 on v1.1. HalluHard, on its updated question set: 38.9% with web search, 50.9% without. No Vectara score yet, and not on the public FACTS board yet. BullshitBench v2 clear-pushback rate: 56%, against 95% for Opus 4.8 (54% until the board corrected 75 historical records on September 10). [72][2][5][94]
Claude Opus 5 (July 24, 2026): the Opus flagship until Opus 5.5, $5 / $25 per million tokens, 1M-token context, effort levels from low to max. AA-Omniscience at launch: 54% accuracy and a 50% hallucination rate, against 46.6% and 35.9% for Opus 4.8 at its launch. Final v1 record, after Artificial Analysis's August 6 grader change: Index 37 (second on the August board), 61% accuracy, 60.8% hallucination. On v1.1: 60.9% accuracy, 59.4% hallucination, Index 37.6. Its Intelligence Index score of 63 was the highest of any Anthropic model at launch, one point above Fable 5. Read the two numbers together: Anthropic traded the Opus line's refusal profile for a double-digit accuracy gain. Anthropic's launch post reports large accuracy gains in chemistry, biology, financial modeling and legal work and does not report a hallucination figure. SimpleQA Verified: 63.3%, the best Anthropic score on that board. No Vectara score yet, and not on the public FACTS board yet. [83][84][2][101]
Claude Sonnet 5 (June 30, 2026): the default mid-tier model, built for autonomous execution and multi-step tool use. AA-Omniscience final v1 record: 40.1% accuracy, 39.4% hallucination, Index 16.5. Artificial Analysis has not re-run it on v1.1. Artificial Analysis lists Sonnet 5 (max) at Intelligence Index 55. Anthropic's pre-deployment evals report lower hallucination and sycophancy than Sonnet 4.6 and stronger prompt-injection resistance. BullshitBench v2: 80% clear pushback. HalluHard without web search: 59.7% on the updated question set. SimpleQA Verified: 32.1%. No Vectara score yet. [74][2][99][94][5][101]
Claude Opus 4.8 (May 28, 2026): the calibration-first flagship, superseding Opus 4.7 after 42 days and itself superseded by Opus 5 after 57. AA-Omniscience Index at launch: 27 (then second-highest overall, behind only Gemini 3.1 Pro's 33). Accuracy at launch: 46.6%. Hallucination rate at launch: 35.9%, essentially flat against Opus 4.7, which is the headline: a full flagship generation passed with calibration held steady rather than traded away for raw knowledge. Its final v1 record reads 48.8% / 39.3% / Index 28.8, the best-calibrated frontier Claude on v1. Artificial Analysis has not re-run it on v1.1. It also took the top spot on the Artificial Analysis Intelligence Index at 61.4 when it launched, with SWE-bench Pro at 69.2% and Terminal-Bench 2.1 at 74.6%. Early testers reported it was more likely to flag uncertainty and less likely to make unsupported claims. BullshitBench v2: 95% clear pushback, the highest score on that board, now tied with Qwen3.8 Max at its minimal reasoning setting. It scored 53.5 on the FACTS board in September, before the board dropped it, and 44.5% on SimpleQA Verified. [64][65][2][94][3][101]
Claude 4.1 Opus (August 5, 2025): the leader when AA-Omniscience launched in November 2025, with 36% accuracy and an Omniscience Index of 4.8, one of only three models above zero. Its hallucination rate was 48%, third lowest at the time, behind Claude 4.5 Haiku and level with Claude Sonnet 4.5. Artificial Analysis has since deprecated the model and no longer lists it on the AA-Omniscience board. Domain leader in Law, Software Engineering, and Humanities in the launch analysis. FACTS: 46.5 in the December 2025 launch table. Vectara: 4.2% on the original dataset, 11.8% on the new one. Earlier versions of this page gave it a 0% hallucination rate, a figure no source supports. [2][104][3][100][1]
Claude Opus 4.6 (February 5, 2026): AA-Omniscience final v1 record: 47.0% accuracy, 62.8% hallucination, Index 13.7. Vectara new dataset: 12.2%. It scored 41.5 on the FACTS board in September, before the board dropped it. SimpleQA Verified: 45.2%, second among Anthropic models after Opus 5. [2][1][3][101]
Claude Opus 4.5 (November 24, 2025): AA-Omniscience at launch: 58% hallucination, 43% accuracy. Final v1 record: 46.6% accuracy, 61.0% hallucination, Index 14.0. HalluHard: 30.2% with web search, the best result on its original question set and second on the board behind GPT-6 Astra's 27.2% on the updated set, and 60.0% without search. FACTS: 51.3 in the December 2025 launch table, and 43.9 on the 2026 Kaggle board in September, which no longer lists it. Vectara new dataset: 10.9%. SimpleQA Verified: 39.0%. [14][2][5][3][1][101]
Claude Sonnet 4.6 (February 17, 2026): AA-Omniscience hallucination on launch day: about 38%, down from Sonnet 4.5's 48%, at 24% accuracy. By April, after a re-run, Artificial Analysis's record read 46% at 40% accuracy. Final v1 record: 48.4% at the max setting, against 49.1% for Sonnet 4.5 (reasoning), with accuracy at 40.9% against 32.9%. Users preferred Sonnet 4.6 over Opus 4.5 59% of the time, citing fewer hallucinations. Vectara new dataset: 10.6%. It scored 37.0 on the FACTS board in September, before the board dropped it, and reads 30.9% on SimpleQA Verified. [13][50][123][2][1][3][101]
Claude Opus 4.7 (April 16, 2026): AA-Omniscience at launch: Index 26 (second-highest overall at release, behind only Gemini 3.1 Pro's 33) and a 36% hallucination rate, the strongest calibration profile of any frontier model attempting questions at scale at the time, and 50 percentage points better than GPT-5.5's launch figure. Final v1 record: 48.9% accuracy, 42.3% hallucination, Index 27.3. BenchLM overall: 87 (April 2026). Long-context retrieval dropped to 32.2% (down from Opus 4.6's 78.3%). Anthropic explicitly attributes this to the model now reporting errors when information is missing rather than fabricating an answer. The refusal strategy made measurable. Vectara new dataset: 12.0%, the newest Claude on that board until Opus 5.5 (9.9%) in October. It scored 45.5 on the FACTS board in September, before the board dropped it. HalluHard without web search: 59.6%. [58][63][2][1][3][5]
The pattern across Claude: by Opus 4.7 and 4.8, Anthropic's models were calibrated to refuse rather than guess, trading raw accuracy for some of the lowest hallucination rates on knowledge benchmarks. On v1 that still described Opus 4.7 and 4.8 (42.3% and 39.3%) and Sonnet 5 (39.4%). Fable 5 and Opus 5 were the deliberate exceptions: they answer more, know more, and hallucinate more (63.6% and 60.8% on v1). Their successors kept the answer-first profile on v1.1, less sharply in Opus 5.5's case: Fable 5.1 at 70.0% and Opus 5.5 at 50.3%. Haiku 5.5 (34.2%) and Sonnet 5.5 (43.3%) are the best-calibrated current Claude models. BullshitBench v2 tells the same story from a different angle: Opus 4.8 pushes back on a nonsense premise 95% of the time, Sonnet 4.6 91%, Fable 5 56%. For applications where a wrong answer is worse than no answer (legal research, medical consultation, compliance work), no single Claude is a safe default: Opus 5.5 still gives a wrong answer on about half of the questions it doesn't answer correctly. [2][94]
Gemini 4 Carbon (October 28, 2026, not yet publicly available): Google's second Gemini 4 model and the new leader of the AA-Omniscience v1.1 Index. Google is giving access to a subset of cyber defenders first, then to more trusted partners through its Fairwind Program, before a wider release. At high effort: 58.3% accuracy, 11.4% hallucination, Index 53.5, 5.4 points clear of Claude Opus 5.5. At medium effort: 48.9% accuracy and 4.2% hallucination, the lowest rate of any model that answers at least 45% of questions correctly. It leads the Index while giving a wrong answer on only about one in nine of the questions it doesn't answer correctly. Artificial Analysis also puts it first on its Intelligence Index v5. Google says that in its internal testing Carbon cuts unsupported claims by about half against Argon. On FACTS it leads the Search and Multimodal sub-boards (94.4 and 60.2) but has no suite average yet. No Vectara or SimpleQA Verified score yet. [2][125][126][3]
Gemini 4 Argon (announced September 30, 2026, public since October 13): Google gave an initial group of cyber defenders access first, then opened it on October 13 in the paid tier of the Gemini API and to Google AI Pro and Ultra subscribers in the Gemini app. AA-Omniscience v1.1 (high): 48.3% accuracy, 4.3% hallucination, Index 46.1. The move to v1.1 cut its rate from 15.1% to 4.3%, and it is now the best-calibrated public model that answers at least 45% of questions correctly. On v1 it already read 15.1% against Gemini 3.1 Pro's 50.9%, a clean break from the Gemini pattern below. The other boards have caught up with it since October. FACTS: 72.4, third among models scored on all four slices. SimpleQA Verified: 75.6%, third on the board. Vectara's new dataset is the exception: 12.1%, higher than Gemini 3.1 Pro Preview's 10.4%, so the model that guesses least on knowledge questions still adds unsupported detail to summaries. [2][103][127][3][101][1]
Gemini 3.8 Flash (September 2, 2026): AA-Omniscience v1.1 (high): 50.5% accuracy, 55.1% hallucination, Index 23.3. On v1 it had cut the Flash line's rate to 55.2% from Gemini 3.7 Flash's 64.5% at nearly the same accuracy. On the FACTS board it averages 71.2 across all four slices, and on SimpleQA Verified it scores 74.6%, fourth on that board. [2][3][101]
Gemini 3.5 Flash-Lite (July 21, 2026): 26.5% accuracy, 26.7% hallucination, Index 6.9 on v1.1 (29.5% / 34.4% / 5.2 on v1). Google's lightweight tier answers fewer questions correctly than the Flash models and guesses less often. FACTS: 53.5 on the 2026 board in September. The November board has no Grounding score for it, so it is not ranked here. SimpleQA Verified: 33.1%. [2][3][101]
Gemini 3.7 Flash (August 13, 2026): Google's workhorse until 3.8 Flash, shipped three weeks after 3.6 Flash as a refinement rather than a new pretraining run. AA-Omniscience final v1 record: 55.3% accuracy, 64.5% hallucination, Index 26.5. Artificial Analysis has not re-run it on v1.1. That is Gemini-typical: near the top on knowledge, weak on admitting gaps, though far better calibrated than Gemini 3 Flash's 93.0%. Google's launch post reports coding and agent benchmarks and no factuality figure. No Vectara score yet. It scored 71.2 on the FACTS board in September, third at the time behind GPT-6 Astra and GPT-6 Sol, before the board dropped it. SimpleQA Verified: 73.2%, though that board now marks the model deprecated. [87][2][3][101]
Gemini 3.1 Pro Preview (February 19, 2026): AA-Omniscience Index 30 at launch (33 after a re-run by April), third on the August 2026 board behind Claude Fable 5 (43) and Claude Opus 5 (37), and Google's best public model on that measure until Gemini 4 Argon opened to the public in October. Accuracy at launch: 53%. Hallucination rate: 50%, down from Gemini 3 Pro's 88%. Its final v1 record reads 54.9% accuracy, 50.9% hallucination and Index 31.9, against 91.5% hallucination for Gemini 3 Pro. This was the biggest single-update hallucination improvement until GPT-6 Astra in September 2026. It tops SimpleQA Verified at 77.5% and averages 69.1 on the FACTS board. Vectara new dataset: 10.4%. HalluHard without web search: 57.1%. BullshitBench v2: 37% clear pushback, the lowest of the US frontier flagships. [15][2][101][3][1][5][94]
Gemini 3 Pro (November 18, 2025): FACTS overall: 68.8 (highest in the December 2025 launch table). FACTS Search: 83.8. FACTS Parametric: 76.4. AA-Omniscience at launch: 53% accuracy, then the highest of any model, with 88% hallucination. Final v1 record: 55.8% and 91.5%. Vectara new dataset: 13.6% (preview). SimpleQA Verified: 72.1% (preview). The Gemini Paradox at launch: the most knowledgeable model, and one of the least self-aware. [3][2][1][101]
Gemini 3 Flash (December 2025): AA-Omniscience at launch: 55% accuracy, the highest of any model tested at the time, and a 91% hallucination rate. Final v1 record: 53.4% and 93.0%. Speed: 218 tokens/s. The most extreme version of the Gemini Paradox, brilliant and unreliable in equal measure. Suitable only for tasks with external verification. The May 2026 successor, Gemini 3.5 Flash, addresses this directly. [16][2]
Gemini 3.5 Flash (May 19, 2026): AA-Omniscience hallucination at launch: 61%, down 31 percentage points from the 92% Artificial Analysis then listed for Gemini 3 Flash. Final v1 record: 51.4% accuracy, 62.2% hallucination, Index 21.2 (high), against 93.0% for Gemini 3 Flash. That single generation cut the most extreme version of the Gemini Paradox by roughly a third and lifted the Omniscience Index 11 points. MMMU-Pro multimodal: 84%, the highest score recorded on that evaluation at launch. Intelligence Index: 55. It scored 63.1 on the FACTS board in September, before the board dropped it, and 70.4% on SimpleQA Verified, which now marks it deprecated. One caveat worth stating plainly: unlike Anthropic and OpenAI, Google has not published first-party hallucination data for this model. The 61% figure is independent benchmarking from Artificial Analysis, not a vendor disclosure. [64][66][67][68][2][3][101]
In 2025, Google's models knew the most but rarely admitted what they didn't know.
The pattern across Gemini: Gemini 3 Pro and 3 Flash attempted nearly every question, which gave them top accuracy scores but catastrophic hallucination rates when they hit their knowledge limits. The 3.1 Pro update showed this is addressable: by guessing less often, it cut the hallucination rate 40.6 percentage points on their final v1 records (91.5% to 50.9%) for under one point of accuracy. Gemini 3.5 Pro, announced at Google I/O in May, was never publicly released. When Google announced Gemini 4 Argon on September 30, a spokesperson told Reuters the company no longer plans to release it. From May to September, Google's public releases were Flash-only: 3.5 Flash in May, 3.6 Flash in July, 3.7 Flash in August and 3.8 Flash in September. The Gemini 4 models break the pattern: Argon, public since October 13, reads 4.3% on v1.1, and Carbon, so far open only to a subset of cyber defenders and trusted partners, 11.4% at high effort and 4.2% at medium. [98][103][2]
Grok 4.7 (September 21, 2026): AA-Omniscience v1.1 (xhigh): 42.7% accuracy, 20.0% hallucination, Index 31.2 (47.4% / 29.3% / 32.0 on v1). On v1 it was the second release in a row in which xAI cut the rate, 5 points below Grok 4.6. Configurations differ: Artificial Analysis lists Grok 4.7 at xhigh and Grok 4.6 at high. On v1.1 it answers fewer than 45% of questions correctly, so it falls outside the group the headline figures use, but its 20.0% is the lowest rate of any OpenAI, Anthropic or xAI model on the v1.1 board. SimpleQA Verified: 59.4%, the best xAI score on that board. [2][101]
Grok 4.6 (August 12, 2026): xAI's flagship until Grok 4.7, $2/$6 per million tokens, 500K context, Intelligence Index 61 (tied with GPT-5.6 Sol max). AA-Omniscience final v1 record (high): 48.2% accuracy, 34.3% hallucination, Index 30.5, fourth on the August 2026 board. On v1.1 only its xhigh setting was re-run: 46.2%, 39.7%, Index 24.9. Against Grok 4.5's final v1 record that is 19.8 points less hallucination for 3.4 points less accuracy. xAI's own model card points the other way: 1.7% on its internal factuality evaluation at high effort versus 0.98% for Grok 4.5, MASK-Rectified dishonesty 1.90% versus 0.67%. Internal and independent measurements disagree on direction, not just size. SimpleQA Verified: 52.9%. Strong candidate for the verification seat in a multi-model setup, still not a sole model for high-stakes factual work. [85][86][2][101]
Grok 4.5 (July 8, 2026): released under the SpaceXAI brand. AA-Omniscience accuracy jumped to 52% at launch (from Grok 4.3's 35%), but the hallucination rate more than doubled, from 25% to 54%. The Index still rose 8 points to 26 because accuracy climbed faster than the penalty. Final v1 record: 51.6% accuracy, 54.1% hallucination, Index 25.3. It ranked 4th on the Artificial Analysis Intelligence Index at 54 at launch. Pricing $2/$6 per million tokens, 500K context. A textbook case of buying knowledge at the cost of calibration, and, five weeks later, the baseline that Grok 4.6 corrected. xAI's model card for 4.6 gives 4.5 a 0.98% score on the internal factuality evaluation. FACTS: 50.2 on the 2026 board in September. The November board scores it on the Parametric slice only (42.5). SimpleQA Verified: 53.8%. [75][85][2][3][101]
Grok 4.3 (April 2026): AA-Omniscience in two configurations. High: 34.8% accuracy, 25.8% hallucination, Index 18.0. Medium: 28.8% accuracy and 16.9% hallucination, a lower-attempt setting that edges the older Grok 4.20 Reasoning (17.4%) for the lowest-hallucination Grok. API pricing $1.25/$2.50 per million tokens. [69][2]
Grok 4 (July 9, 2025): Vectara old dataset: 4.8%. AA-Omniscience at launch: 39% accuracy, the highest at the time and level with GPT-5 (high), with a 64% hallucination rate, one of only three models with a positive Index. Final v1 record: 40.5%, 64.5%, Index 2.1. FACTS: 53.6 in the December 2025 launch table (Search: 75.3, Multimodal: 25.7). Domain leader in Health and Science in the AA-Omniscience launch analysis. [100][104][2][3]
Grok 4.1 Fast: xAI claims a 65% hallucination reduction (12.09% to 4.22% on internal benchmarks). AA-Omniscience tells a different story: 72% hallucination at launch and 73.4% in its final v1 record, worse than Grok 4's 64.5%. Vectara new dataset: 19.2% with reasoning, the 9th-highest rate of the 111 models on that board. Sycophancy also increased (MASK benchmark: 0.07 to 0.19-0.23). [17][2][1]
Grok-3 (February 17, 2025): Columbia Journalism Review: 94% citation hallucination rate, by far the worst score in that study. Vectara: 2.1% on the original dataset (as Grok-3-Beta) and 5.8% on the new one, the best xAI score on the current board. SimpleQA Verified: 39.3%. [6][100][1][101]
The pattern across Grok: internal benchmarks and independent benchmarks disagree sharply, and with Grok 4.6 they disagree on direction. AA-Omniscience v1 says 4.6 cut hallucination to 34.3% (down from 4.5's 54.1%), and 4.7 cut it again to 29.3%, which reads 20.0% on v1.1. xAI's own factuality evaluation says 4.6 got slightly worse (1.7% versus 0.98%). Grok 4.5 remains the textbook case of buying knowledge at the cost of calibration: more knowledgeable than Grok 4.3 and hallucinating more than twice as often. The 94% CJR citation hallucination rate comes from Grok-3, tested in March 2025, and no newer Grok has been through that study. Domain-specific value exists in Health and Science, and the calibration of 4.6 and 4.7 makes them stronger second voices than any Grok before them. The gap between vendor and independent numbers still makes Grok risky as a sole model for any high-stakes application.
Sonar Reasoning Pro (2025): Search Arena score: 1136, statistically tied with Gemini 2.5 Pro for #1. SimpleQA F-score: 0.858, the highest of any model at time of testing. CJR citation accuracy: 37% hallucination (best tested). Response accuracy: >90% for factual queries (94% overall, 95% academic, 94% technical). [18][19]
Sonar Pro (2025): Built on Llama 3.3 70B, fine-tuned for search factuality. SimpleQA F-score: 0.858. Outperforms GPT-4o and Claude 3.5 Sonnet on factuality benchmarks. [19]
The Perplexity risk: Perplexity introduces a failure mode no other model shares. It cites real URLs with fabricated claims. The sources look legitimate, with real websites and real publication names, but the information attributed to those sources may be invented. This makes Perplexity hallucinations harder to detect than hallucinations from models that don't present external citations. A 37% citation hallucination rate means more than one in three source attributions may contain fabricated content. [51]
DeepSeek V4.1 Flash 1017 (October 17, 2026): the October build of V4.1 Flash, with open weights under the MIT license. AA-Omniscience v1.1 (max): 39.6% accuracy, 64.1% hallucination, Index 0.9. On v1 this build read 66.8%, against 96.5% for the earlier V4.1 Flash build, so DeepSeek's newest model is far better calibrated than the one it replaced, though still answer-first. On October 27, before Kimi K3.1 Pro's weights came out, Artificial Analysis ranked it level with GLM-5.3 as the top model with released open weights on its Intelligence Index v5. [2][124][138]
DeepSeek V4.1 Flash: the highest hallucination rate in the v1 data, 96.5% at 46.4% accuracy (max), Index -5.3, in its final v1 record. Artificial Analysis has not re-run this build on v1.1. Against V4 Flash, accuracy rose almost 10 points and the hallucination rate barely moved. Vectara's new dataset: 4.2%, sixth-lowest of the 111 models there. SimpleQA Verified: 42.3%. Both boards list the model as DeepSeek V4.1 Flash with no build date, so either build could be behind those two figures. [2][1][101]
DeepSeek V4 Pro and V4 Flash (preview April 24, 2026): a cautionary data point. At launch the V4 Pro preview posted a 94% AA-Omniscience hallucination rate and an Omniscience Index of -10, and V4 Flash hit 96% with an Index of -23, among the highest ever recorded on the benchmark, in the same territory as Gemini 3 Flash (93.0% in its final v1 record) and Llama 4 Maverick (88.9%). Final v1 records: V4 Pro preview 43.0% accuracy, 94.1% hallucination, Index -10.7. V4 Flash 36.8%, 96.1%, Index -23.9. Strong coding performance paired with near-total overconfidence on knowledge questions. Vectara new dataset: 8.6% for V4 Pro. [70][2][1]
DeepSeek V4 Pro 0813 (general availability August 13, 2026): the GA build that took V4 Pro out of preview. AA-Omniscience v1.1 (max): 45.2% accuracy, 94.1% hallucination, Index -6.4, the highest hallucination rate of any model in our table on v1.1 (94.8% on v1). On v1, accuracy rose 6.1 points over the preview and the hallucination rate barely moved, which is why the Index climbed from -10.7 to about zero: DeepSeek added knowledge without adding any willingness to say "I don't know". The two builds are scored separately on this page because the checkpoints differ. [92][88][2]
DeepSeek-V3 (December 26, 2024): Vectara: 3.9% on the original dataset, 6.1% on the new one. A strong performer on grounded summarization. SimpleQA Verified: 27.4%. [100][1][101]
DeepSeek-R1 (January 20, 2025): Vectara old dataset: 14.3%, nearly 4x higher than V3, and 11.3% on the new dataset. AA-Omniscience (0528 build): 83.4% hallucination at 30.5% accuracy. Vectara analysis found R1 produces 71.7% "benign hallucinations" (plausible-sounding additions) vs V3's 36.8%. [49][48][100][1][2]
The pattern: DeepSeek's reasoning model (R1) hallucinates dramatically more than its base model (V3). This is the reasoning tax in its most extreme form. The gap (3.9% vs 14.3%) makes it one of the clearest examples that reasoning capabilities and factual reliability don't move in the same direction. On Vectara's new dataset the gap narrows (6.1% vs 11.3%) but holds.
Kimi K3.1 Pro (Moonshot AI, October 23, 2026): AA-Omniscience v1.1: 48.9% accuracy, 37.3% hallucination, Index 29.9. Artificial Analysis ranked it the top open-weights model on its Intelligence Index v5 on October 27, and Moonshot released the weights on November 2. On v1 it read 43.9% hallucination, against Kimi K3's 53.2%. Moonshot reports that on its own Kimi Hallu Bench Hard stress test, the claim-level hallucination rate fell from 23.4% for K3 to 8.3%. [2][124][132]
Muse Wonder and Muse Wonder Full (Meta, October 12, 2026): Meta's new top models. AA-Omniscience v1.1 (max): Muse Wonder Full 41.0% accuracy, 17.6% hallucination, Index 30.6, and Muse Wonder 38.0%, 20.9%, Index 25.1. Both sit with the cautious models: Wonder Full has the lowest hallucination rate in our table outside the Gemini 4 models and Command A+. Muse Wonder is available through Meta's Model API and Muse Code, Wonder Full to Muse Code subscribers, and neither has open weights. Wonder Full also leads Artificial Analysis's Harvey LAB-AA v1.1 legal benchmark, which zeroes any task with a material hallucination, at 13.1%. [2][130][139]
Muse Spark Open (Meta, October 15, 2026): Meta's open-weights model, released under the Muse Model License with limited commercial terms. AA-Omniscience v1.1 (xhigh): 42.0% accuracy, 28.0% hallucination, Index 25.8. [2][131]
Mistral Large 4 (Mistral AI, October 29, 2026, after a preview on October 6): released with open weights under a modified MIT license. AA-Omniscience v1.1 (high): 26.0% accuracy, 28.2% hallucination, Index 5.1. The preview read 23.9%, 41.3% and Index -7.5, so the release answered slightly more questions correctly and guessed much less. [2][133]
Inkling 2 Small (Thinking Machines Lab, November 5, 2026): AA-Omniscience v1.1: 33.8% accuracy, 26.7% hallucination, Index 16.1. It is available through Thinking Machines' Tinker platform, and the company plans to release its weights under Apache 2.0, which Artificial Analysis says would make it the highest-scoring open-weights model developed outside China. [2][135][136]
Tencent Hy4 (Tencent, November 4, 2026): the clearest vendor-versus-independent gap in this update. Tencent's research blog says Hy4 cut its hallucination rate from 15.76% to 5.45%, and its press release gives 12.95% to 7.2% for the same step. Artificial Analysis measures 50.0% accuracy and an 89.1% hallucination rate on AA-Omniscience v1.1. The figures measure different tests, and Tencent's two do not agree with each other. Tencent has promised open weights but not yet released them. [2][134]
MiniMax-M3.1-Flash (MiniMax, October 19, 2026, open weights): 45.1% accuracy and a 93.7% hallucination rate on AA-Omniscience v1.1. Like Hy4, it attempts almost every question, about 99% of them, so almost every gap in its knowledge becomes a wrong answer. [2][137]
Qwen3.8 Max (0902) (Alibaba, September 2, 2026): 29.5% accuracy, 27.1% hallucination, Index 10.5 on v1.1 (31.7% / 28.8% / 12.0 on v1). On v1 the September build pulled the hallucination rate back down from the preview's 41.7% at the same accuracy, close to the abstention-first profile of Qwen3.7 Max. [2]
Muse Spark 1.3 (Meta, September 2, 2026): 38.0% accuracy, 25.2% hallucination, Index 22.4 at max on v1.1 (43.6% / 32.9% / 25.0 on v1). On v1 it sat close to Muse Spark 1.2 (xhigh) on calibration, 1.8 points lower on accuracy. [2]
Kimi K3 (Moonshot AI, July 2026, open weights released July 27): a 2.8-trillion-parameter open-weights MoE model with a 1M-token context window, the first open model in the 3T class. AA-Omniscience: 46% accuracy, 51% hallucination, Index 18 at launch (47.6% / 53.2% / 19.7 in its final v1 record). Like Grok 4.5, its accuracy gain over the prior generation came with a calibration regression. Ranks among the top open-weight models on the Artificial Analysis Intelligence Index. [76][93][2]
Command A+ (Cohere, open weights, May 20, 2026): 13.9% hallucination on v1.1 (14% on v1), the lowest on Artificial Analysis's board when it launched in May 2026, reached by refusing most questions it can't verify (9.8% accuracy, Index -2.7). Only the Gemini 4 models read lower in our table on v1.1. A "knows-its-limits" archetype similar to Claude 4.5 Haiku, useful as a verification layer in a multi-model pipeline. [77][2]
Qwen3.7 Max (Alibaba, May 19, 2026): an abstention-first model that refuses whenever its internal confidence threshold isn't met. At launch: 30% accuracy, 23% hallucination, Index 14. Final v1 record: 31.1%, 25.6%, Index 13.5. It has a 1M-token context window, and its refusal habit makes it another strong verification-layer candidate. [78][2]
Qwen3.8 Max Preview (Alibaba, previewed July 19, 2026, launched August 3, the build Artificial Analysis scores): a 2.4-trillion-parameter MoE flagship with open weights promised. AA-Omniscience final v1 record: 31.9% accuracy, 41.7% hallucination, Index 3.4. Accuracy barely moved from Qwen3.7 Max, and the hallucination rate rose from 25.6% to 41.7%: Alibaba loosened the abstention policy that made 3.7 Max a verification-layer candidate, and got almost no knowledge in return. The clearest recent example of calibration being a training choice, not a capability. [90][2]
GLM-5.3 (Z.ai, August 14, 2026): a coding and cyber-security flagship built on the GLM-5.2 base without retraining. On v1 it read 33.9% accuracy, 29.6% hallucination and Index 14.3, the best-calibrated new open-weight model of the summer, in the Qwen3.7 Max and Grok 4.3 band. Version 1.1 moved it the other way: 32.3%, 38.9%, Index 6.0, the largest rise of any model in our table that Artificial Analysis re-ran. [91][2]
Llama 4 Maverick (Meta, April 5, 2025): Vectara: 4.6% on the original dataset (competitive) and 8.2% on the new one. AA-Omniscience: 88.9% hallucination in its final v1 record (87.6% when first published here), at 24.9% accuracy. The gap between grounded summarization and open-ended knowledge is wider for open-source models than for any proprietary family. [100][1][2]
In a 2025 clinical test with planted fake details, a distilled DeepSeek-R1 model built on the fake detail 80.0-82.7% of the time, while Llama-3.3-70B did about as well as GPT-4o. For critical applications, the gap between open and proprietary models depends on the model and the task. [105]
Muse Spark 1.1 (Meta, July 9, 2026): carries an AA-Omniscience profile, not just a HealthBench score. July launch configuration: Index 18 (up from Muse Spark 1.0's 4), accuracy 41% (roughly flat), hallucination 38% (down from 73%). The entire gain came from abstention: attempt rate dropped from 95% to 82%. It is the clearest recent example of a model getting more reliable by learning when to stay silent rather than by learning more. The xhigh configuration in our table reads 52.1% accuracy / 50.0% hallucination / Index 28.1: more knowledge, and the abstention discipline gone. HealthBench Professional: 59.3%. Its HealthBench Hard leadership (42.8) belongs to the original Muse Spark. A 1.1-specific Hard score is not yet confirmed. [71][88][2]
Muse Spark 1.2 (Meta, August 5, 2026): a coding-focused update to 1.1, co-trained with Meta's Muse Code agent. AA-Omniscience final v1 record (xhigh): 45.4% accuracy, 33.3% hallucination, Index 27.2. Set against the xhigh configuration of 1.1, that is a 16.7-point cut in hallucination for 6.7 points of accuracy. On v1, among models in our table that are now public and answered at least 45% of questions correctly, only Gemini 4 Argon and Grok 4.7 were better calibrated. Meta's launch post reports coding benchmarks only and no factuality figure. [89][88][2]
The model profiles in Section 6 show individual performance. This section answers the questions people actually search for: "Is Claude or GPT more accurate?" "Should I use Gemini or Claude?" The answer depends on what you're doing, but the data makes the tradeoffs specific. In the Claude, GPT, Gemini and Grok tables every cell names the model behind the figure, and most rows compare the best result each family posts on a benchmark. Current figures come from Artificial Analysis's AA-Omniscience v1.1 records of November 7, 2026, Vectara's October 22 board, the FACTS Kaggle board of November 5, the SimpleQA Verified board of October 20 and HalluHard's current board. AA-Omniscience rows compare v1.1 records only, so models Artificial Analysis has not re-run, such as Claude Opus 4.8 and Gemini 3.1 Pro, drop out of those rows. Older results are labeled as such: Vectara's original dataset (archived October 2025), the December 2025 FACTS launch table, HealthBench (August 2025), the CJR citation study (March 2025) and the Perplexity comparison, which dates from 2025.
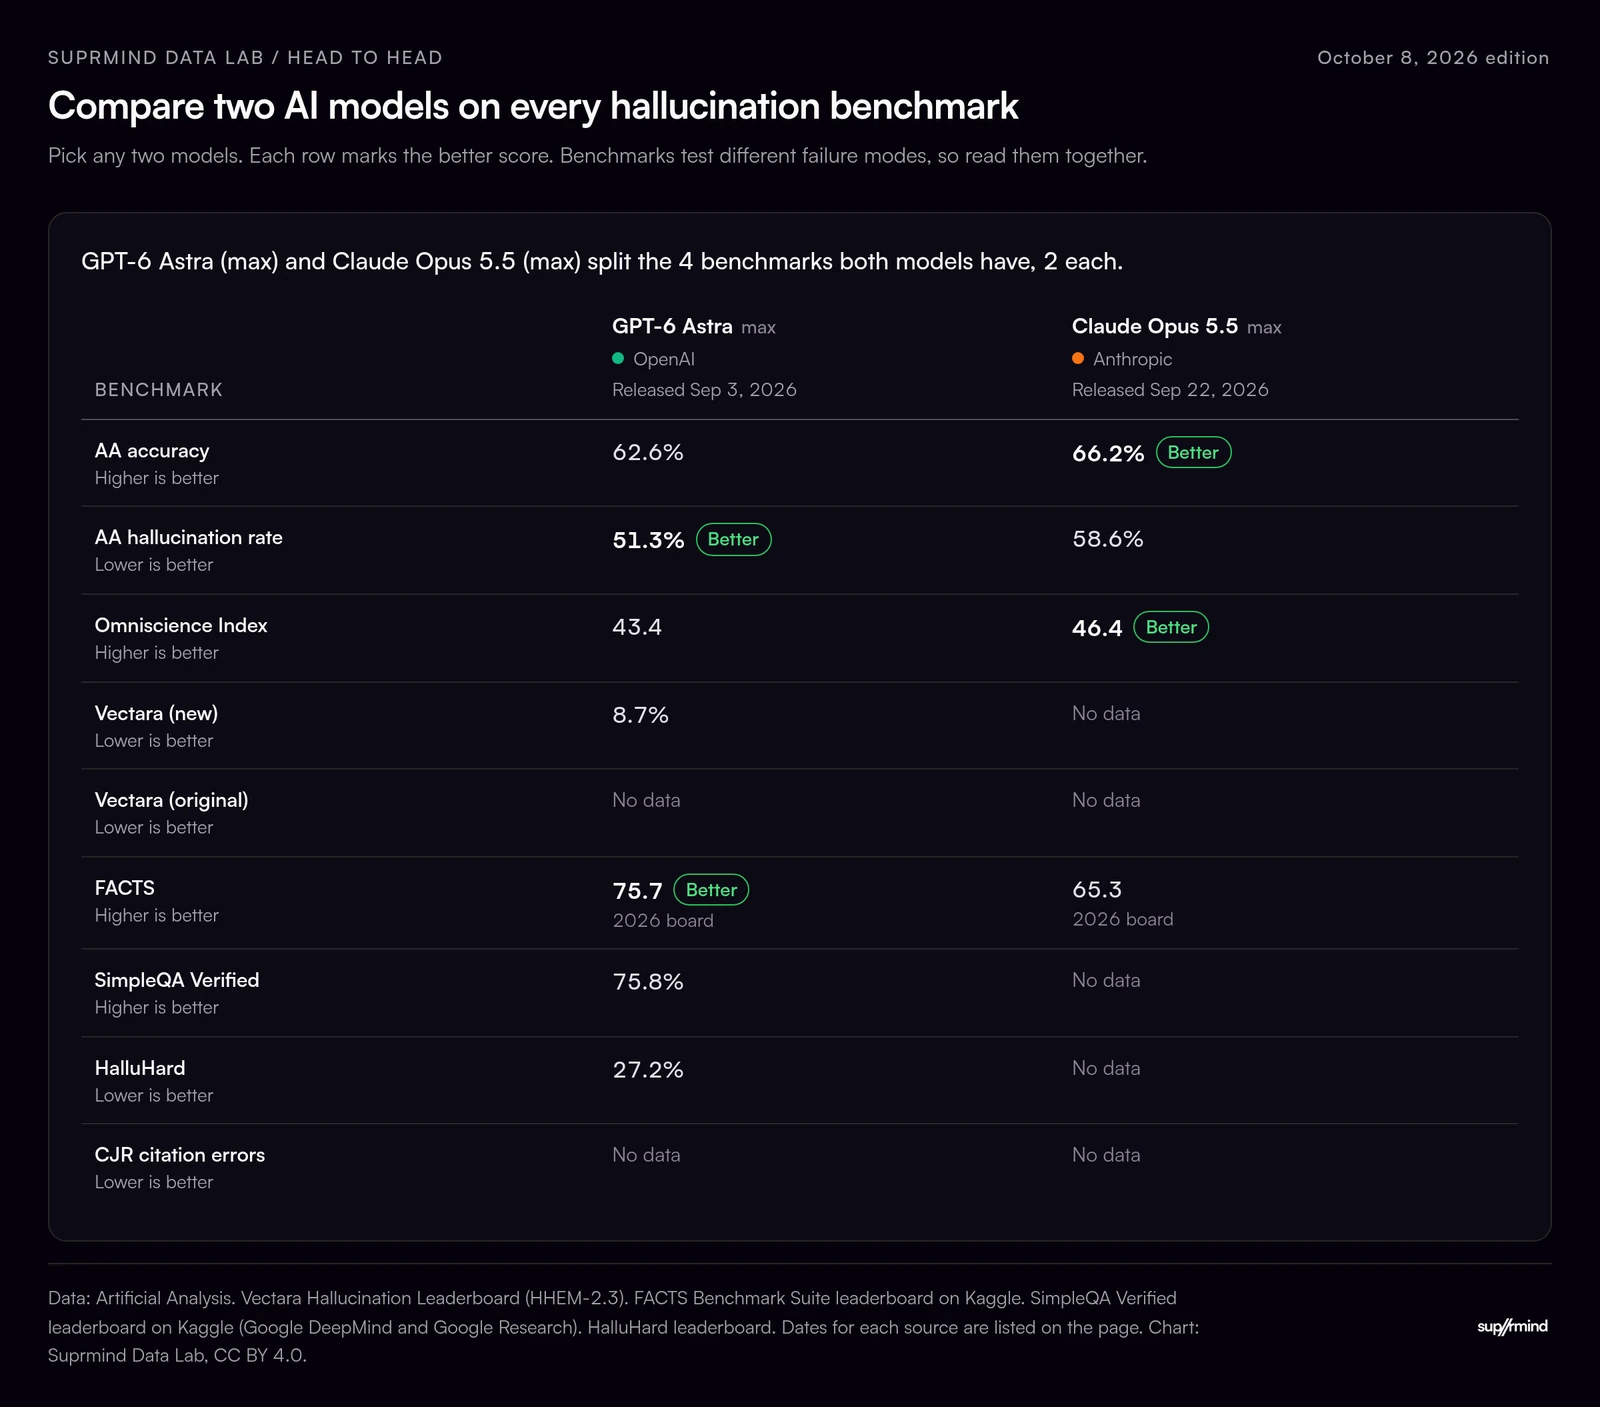
The most searched comparison in AI, and the most context-dependent. On AA-Omniscience v1.1 the newest flagships are close on calibration: Claude Opus 5.5 reads 65.5% accuracy and 50.3% hallucination, GPT-6 Astra 61.6% and 49.8%, and GPT-6.1 Sol 61.8% and 51.9%. Claude Fable 5.1 knows the most, at 68.4%, and guesses the most, at 70.0%. All four give a wrong answer about as often as they decline, or more often. [2][124]
| Benchmark | Claude | GPT | Winner |
|---|---|---|---|
| AA-Omniscience v1.1 accuracy (best model) | 68.4% (Fable 5.1) | 61.8% (GPT-6.1 Sol) | Claude |
| AA-Omniscience v1.1 Index (best model) | 48.1 (Opus 5.5) | 42.4 (GPT-6 Astra max), 44.6 (high) | Claude |
| AA-Omniscience v1.1 hallucination (newest flagships) | 50.3% (Opus 5.5), 70.0% (Fable 5.1) | 49.8% (GPT-6 Astra), 51.9% (GPT-6.1 Sol) | Tied at the top (Opus 5.5, GPT-6 Astra) |
| AA-Omniscience v1.1 hallucination (best-calibrated public model answering 45%+ correctly) | 43.3% (Sonnet 5.5) | 34.5% (GPT-6.1 Terra) | GPT |
| Vectara, new dataset (best model) | 9.8% (Haiku 4.5) | 3.1% (GPT-5.4 nano) | GPT |
| Vectara, original dataset (best model, October 2025 archive) | 4.2% (Opus 4.1) | 0.8% (o3-mini-high) | GPT |
| FACTS, 2026 Kaggle board (models scored on all four slices) | 66.5 (Opus 5.5) | 78.1 (GPT-6 Astra) | GPT |
| FACTS, December 2025 launch table | 51.3 (Opus 4.5) | 61.8 (GPT-5) | GPT |
| SimpleQA Verified (no tools) | 63.3% (Opus 5) | 75.8% (GPT-6 Astra) | GPT |
| HalluHard with web search, updated question set | 38.9% (Fable 5) | 27.2% (GPT-6 Astra) | GPT |
| HalluHard with web search, original question set | 30.2% (Opus 4.5) | 31.9% (GPT-5.4 Thinking) | Claude (slight) |
| HealthBench hallucination (GPT-5 system card, August 2025) | – | 1.6% (GPT-5 thinking) | No Claude score |
Sources: AA-Omniscience v1.1, Artificial Analysis records read November 7, 2026 [2][124]. Vectara new dataset [1] and archived original dataset [100]. FACTS launch table and Kaggle board [3]. SimpleQA Verified [101]. HalluHard [5]. HealthBench: GPT-5 system card [8], via Vellum [52]. GPT-6 Astra is shown at max, the configuration in the cross-benchmark table. Its high setting reads 61.1% accuracy, 42.5% hallucination and Index 44.6.
The pattern isn't "one is better." It's two different philosophies measured on different scales.
GPT models are stronger when the task has source material to work from. Summarization, document analysis, RAG pipelines, search-grounded Q&A: GPT sticks closer to provided text and scores well on faithfulness benchmarks. OpenAI holds the best frontier-lab score on Vectara's new dataset (GPT-5.4 nano, 3.1%, against 9.8% for the best Claude), and GPT-6 Astra leads the FACTS board's fully scored models at 78.1, 11.6 points above Claude Opus 5.5. GPT also leads on short factual questions answered from memory, without tools: GPT-6 Astra scores 75.8% on SimpleQA Verified, against 63.3% for Claude Opus 5, the best Claude on that board. [1][3][101]
Claude used to be the stronger family when the task requires the model to know its own limits. On AA-Omniscience v1, Claude Opus 4.8 gave a wrong answer on 39.3% of the questions it didn't answer correctly, the best calibration of any Claude or GPT model that answered at least 45% correctly. Artificial Analysis has not re-run it on v1.1, and among the models it has re-run, OpenAI now leads: GPT-6.1 Terra reads 34.5% at 47.6% accuracy, against 43.3% for Claude Sonnet 5.5, the best-calibrated Claude that answers at least 45% correctly. When AA-Omniscience launched in November 2025, Anthropic held the three lowest hallucination rates, led by Claude 4.5 Haiku. HalluHard's realistic conversation test splits by question set. On the updated set, GPT-6 Astra with web search (27.2%) beats Claude Fable 5 (38.9%). On the original set, Claude Opus 4.5 (30.2%) edges GPT-5.4 Thinking (31.9%). [2][5]
The practical split: Use GPT for document-grounded workflows where the source material is available and complete, and for short factual lookups. Use Claude Fable 5.1 or Opus 5.5 when the task needs the deepest stored knowledge and you can check the answer: they answer more questions correctly than any GPT. For calibration the edge on v1.1 is OpenAI's: GPT-6.1 Terra hallucinates 34.5% against 43.3% for Sonnet 5.5, the best-calibrated Claude answering at least 45% correctly, and GPT-6 Astra matches Opus 5.5 at about 50%. This isn't brand preference. It's what the benchmark data supports.
One more variable that often gets overlooked: web search access. OpenAI's GPT-5 numbers show it. Its hallucination rate on SimpleQA without web access was 47%, while 9.6% of its factual claims in browsing-enabled ChatGPT traffic contained an error, a different metric that points the same way. HalluHard shows the effect for both labs on the same test: GPT-6 Astra drops from 43.2% without search to 27.2% with it, and Claude Fable 5 from 50.9% to 38.9%. Whichever model you use, turn search on for factual work. [8][12][5]
| Benchmark | Claude | Gemini | Winner |
|---|---|---|---|
| AA-Omniscience v1.1 accuracy (best model) | 68.4% (Fable 5.1) | 58.3% (4 Carbon, not yet publicly available), 50.5% (3.8 Flash, best public) | Claude |
| AA-Omniscience v1.1 Index (best model) | 48.1 (Opus 5.5) | 53.5 (4 Carbon, not yet publicly available), 46.1 (4 Argon, best public) | Gemini with Carbon. Claude (slight) among public models |
| AA-Omniscience v1.1 hallucination (newest flagships) | 50.3% (Opus 5.5), 70.0% (Fable 5.1) | 4.3% (4 Argon), 11.4% (4 Carbon, not yet publicly available) | Gemini |
| AA-Omniscience v1.1 hallucination (best-calibrated public model answering 45%+ correctly) | 43.3% (Sonnet 5.5) | 4.3% (4 Argon) | Gemini |
| Vectara, new dataset (best model) | 9.8% (Haiku 4.5) | 3.3% (2.5 Flash-Lite) | Gemini |
| Vectara, original dataset (best model, October 2025 archive) | 4.2% (Opus 4.1) | 0.7% (2.0 Flash) | Gemini |
| FACTS, 2026 Kaggle board (models scored on all four slices) | 66.5 (Opus 5.5) | 72.4 (4 Argon) | Gemini |
| FACTS, December 2025 launch table | 51.3 (Opus 4.5) | 68.8 (3 Pro) | Gemini |
| SimpleQA Verified (no tools) | 63.3% (Opus 5) | 77.5% (3.1 Pro Preview) | Gemini |
| HalluHard without web search, original question set | 59.6% (Opus 4.7) | 57.1% (3.1 Pro) | Gemini (slight) |
Sources: AA-Omniscience v1.1, Artificial Analysis records read November 7, 2026 [2][124]. Vectara new dataset [1] and archived original dataset [100]. FACTS launch table and Kaggle board [3]. SimpleQA Verified [101]. HalluHard [5], where Gemini has no score with web search.
For eighteen months the shorthand was "Gemini knows more, Claude is more honest about what it doesn't know." Both halves have flipped. On AA-Omniscience v1.1, Claude leads on knowledge: Fable 5.1 answers 68.4% of questions correctly, against 50.5% for the best public Gemini, Gemini 3.8 Flash, and 58.3% for Gemini 4 Carbon, which is not yet publicly available. SimpleQA Verified points the other way: Gemini 3.1 Pro Preview scores 77.5%, 14.2 points above Claude Opus 5, the best Claude on that board. And Gemini now leads on calibration with a model you can use: Gemini 4 Argon, public since October 13, gives a wrong answer on 4.3% of the questions it doesn't answer correctly, against 50.3% for Claude Opus 5.5. [2][101]
Argon changes the trade-off rather than removing it. It answers 48.3% of questions correctly, 17.2 points fewer than Opus 5.5, and declines most of the rest. Claude Sonnet 5.5 sits between them at 51.5% accuracy and 43.3% hallucination. Google's other public model that answers at least 45% correctly on v1.1, Gemini 3.8 Flash, still follows the old Gemini pattern at 55.1%. Before the re-run, Claude Opus 4.8 (39.3%) and Gemini 3.1 Pro (50.9%) were each lab's best-calibrated public model answering at least 45% correctly on v1, and Artificial Analysis has not re-run either on v1.1. [2]
Gemini also still leads on grounded summarization, 0.7% on Vectara's original dataset and 3.3% on the new one, though Gemini 4 Argon itself reads 12.1% there, above Claude Opus 5.5's 9.9%. It leads both FACTS tables: Gemini 4 Argon averages 72.4 across all four slices of the 2026 board, 5.9 points above Opus 5.5, and Gemini 3 Pro led the December 2025 launch table at 68.8. [100][1][3]
The practical split: For depth-of-trust tasks where a fabricated answer has consequences and a declined question is acceptable, such as compliance reviews, legal research and medical consultation, Gemini 4 Argon is now the most cautious public model in either family. Claude Fable 5.1 and Opus 5.5 are the picks for breadth of knowledge when you can check the work. If you can't check the work, don't lean on any single model: Argon answers fewer than half of the questions correctly, and Opus 5.5 gives a wrong answer on half of the questions it doesn't answer correctly. Ask more than one and look at where they disagree.
| Benchmark | GPT | Gemini | Winner |
|---|---|---|---|
| AA-Omniscience v1.1 accuracy (best model) | 61.8% (GPT-6.1 Sol) | 58.3% (4 Carbon, not yet publicly available), 50.5% (3.8 Flash, best public) | GPT |
| AA-Omniscience v1.1 Index (best model) | 42.4 (GPT-6 Astra max), 44.6 (high) | 53.5 (4 Carbon, not yet publicly available), 46.1 (4 Argon, best public) | Gemini |
| AA-Omniscience v1.1 hallucination (newest flagships) | 49.8% (GPT-6 Astra), 51.9% (GPT-6.1 Sol) | 4.3% (4 Argon), 11.4% (4 Carbon, not yet publicly available) | Gemini |
| AA-Omniscience v1.1 hallucination (best-calibrated public model answering 45%+ correctly) | 34.5% (GPT-6.1 Terra) | 4.3% (4 Argon) | Gemini |
| Vectara, new dataset (best model) | 3.1% (GPT-5.4 nano) | 3.3% (2.5 Flash-Lite) | GPT (slight) |
| Vectara, original dataset (best model, October 2025 archive) | 0.8% (o3-mini-high) | 0.7% (2.0 Flash) | Tied |
| FACTS, 2026 Kaggle board (models scored on all four slices) | 78.1 (GPT-6 Astra) | 72.4 (4 Argon) | GPT |
| FACTS, December 2025 launch table | 61.8 (GPT-5) | 68.8 (3 Pro) | Gemini |
| SimpleQA Verified (no tools) | 75.8% (GPT-6 Astra) | 77.5% (3.1 Pro Preview) | Gemini (slight) |
| HalluHard without web search, original question set | 46.8% (GPT-5.4 Thinking) | 57.1% (3.1 Pro) | GPT |
| HealthBench hallucination (GPT-5 system card, August 2025) | 1.6% (GPT-5 thinking) | – | No Gemini score |
Sources: AA-Omniscience v1.1, Artificial Analysis records read November 7, 2026 [2][124]. Vectara new dataset [1] and archived original dataset [100]. FACTS launch table and Kaggle board [3]. SimpleQA Verified [101]. HalluHard [5]. HealthBench: GPT-5 system card [8], via Vellum [52]. GPT-6 Astra is shown at max, the configuration in the cross-benchmark table. Its high setting reads 61.1% accuracy, 42.5% hallucination and Index 44.6.
GPT vs Gemini changed most in October. Gemini 4 Argon opened to the public on October 13, and on AA-Omniscience v1.1 it gives a wrong answer on 4.3% of the questions it doesn't answer correctly, against 49.8% for GPT-6 Astra and 34.5% for GPT-6.1 Terra, OpenAI's best-calibrated model. OpenAI keeps the lead on accuracy, 61.8% for GPT-6.1 Sol against 48.3% for Argon and 50.5% for Gemini 3.8 Flash, and on the FACTS board's fully scored models, 78.1 for GPT-6 Astra against 72.4 for Argon. Gemini keeps a narrow lead on SimpleQA Verified, 77.5% against 75.8%, inside the board's confidence intervals, and still leads the December 2025 FACTS launch table. GPT's other advantages are task-specific: medical applications (1.6% HealthBench), the best frontier-lab score on Vectara's new dataset (GPT-5.4 nano, 3.1%), and the sheer volume of internal evaluation data OpenAI publishes. [2][3][101][1]
The practical split: Both are strong with tool access. Without it, the choice is now a trade-off between public models: Gemini 4 Argon declines what it doesn't know, while GPT-6 Astra and GPT-6.1 Sol answer about 13 points more questions correctly and guess on about half of the rest. Gemini 3.1 Pro Preview leads SimpleQA Verified by 1.7 points. The December 2025 FACTS launch table favored Gemini 3 Pro on its parametric slice, 76.4 against GPT-5's 55.8. GPT's thinking mode gives it a specific advantage for medical and health-related queries where reasoning reduces hallucination dramatically.
| Benchmark | Grok | How It Compares |
|---|---|---|
| AA-Omniscience v1.1 hallucination (newest flagship) | 20.0% (Grok 4.7) | 6th lowest of 32. Lower: Gemini 4 Carbon (medium and high), Gemini 4 Argon, Command A+ and Muse Wonder Full |
| AA-Omniscience v1.1 Index (newest flagship) | 31.2 (Grok 4.7) | 9th of 32. Leader: Gemini 4 Carbon (high), 53.5. Best public: Claude Opus 5.5, 48.1 |
| AA-Omniscience v1.1 accuracy (Grok 4.7) | 42.7% (Grok 4.7) | 17th of 32. Leader: Claude Fable 5.1, 68.4% |
| AA-Omniscience hallucination, final v1 records (Fast variant) | 73.4% (Grok 4.1 Fast) | Worse than the base Grok 4 (64.5%) |
| xAI internal factuality evaluation | 1.7% (Grok 4.6), 0.98% (Grok 4.5), 4.22% (Grok 4.1) | xAI's own figures. No independent equivalent |
| FACTS, 2026 Kaggle board | Not scored | No Grok is scored on all four slices. Grok 4.5 has a Parametric score only (42.5). Leader among fully scored models: GPT-6 Astra, 78.1 |
| FACTS, December 2025 launch table | 53.6 (Grok 4) | 4th of 15, above the 50.5 average |
| SimpleQA Verified (no tools) | 59.4% (Grok 4.7) | 10th of 47 scored. Leader: Gemini 3.1 Pro Preview, 77.5% |
| HalluHard without web search, original question set | 75.3% (Grok 4 thinking) | 19th of 29 entries. Best: GPT-5.4 Thinking, 46.8% |
| Vectara, new dataset | 19.2% (Grok 4.1 Fast, reasoning) | 9th-highest rate of 111. Best Grok: Grok 3, 5.8% |
| CJR citation accuracy (March 2025) | 94% hallucination (Grok-3) | Worst of the eight tools tested. Best: Perplexity, 37% |
Sources: AA-Omniscience v1.1, Artificial Analysis records read November 7, 2026, and final v1 records [2]. Grok 4.1 [17]. Grok 4.6 model card [85]. FACTS [3]. SimpleQA Verified [101]. HalluHard [5]. Vectara [1]. CJR [6]. Ranks count the 32 models in this page's AA-Omniscience v1.1 ranking and the entries on each board, within the same question set for HalluHard.
xAI's internal numbers and the independent ones have never agreed on size. With Grok 4.6 they stopped agreeing on direction. AA-Omniscience v1 said 4.6 cut the hallucination rate to 34.3% from Grok 4.5's 54.1%, and Grok 4.7 cut it again to 29.3%. On v1.1, Grok 4.7 reads 20.0%, the lowest of any public model in our table except Gemini 4 Argon, Command A+ and Muse Wonder Full. xAI's own model card says 4.6 got slightly worse on its internal factuality evaluation (1.7% versus 0.98%). Both can be true, because they measure different things on different scales. [2][85]
Calibration is where Grok beats most of the field. Knowledge is where it trails: Grok 4.7 answers 42.7% of AA-Omniscience v1.1 questions correctly, 25.7 points behind Claude Fable 5.1, and places 10th of 47 on SimpleQA Verified. The older Grok 4.1 Fast is the cautionary case: 73.4% hallucination in its final AA-Omniscience v1 record and 19.2% on Vectara's new dataset, the 9th-highest rate of 111 models there. The CJR citation study found Grok-3 hallucinated 94% of the time on news source attribution, the worst of the eight tools tested. [2][101][1][6]
Grok does have genuine domain strengths: it led Health and Science categories in the AA-Omniscience launch analysis. But the gap between xAI's claims and independent measurements is wider than for any other provider.
The practical takeaway: Don't use Grok as a sole model for high-stakes decisions. Its value is as one voice in a multi-model evaluation where its calibration and domain strengths (health, science) can contribute while other models cover its knowledge gaps. Grok 4.7 pairs a 20.0% hallucination rate with 42.7% accuracy and an Index of 31.2 on v1.1, which makes it the strongest Grok yet for that second-voice role.
| Benchmark | Perplexity | ChatGPT | Claude |
|---|---|---|---|
| CJR citation accuracy (March 2025) | 37% hallucination | 67% hallucination | – |
| SimpleQA F-score (Perplexity, 2025) | 0.858 (best at the time) | 0.38 (GPT-4o) | 0.35 (Sonnet 3.5) |
| Search Arena ranking (2025) | #1 (tied) | – | – |
| Response accuracy (Perplexity, 2025) | >90% factual | – | – |
Sources: Perplexity Sonar [18][19], CJR [6]. Every row dates from 2025. No newer test covers Perplexity, ChatGPT and Claude the same way.
In the 2025 tests, Perplexity won on factual search queries. Its RAG-native architecture, built around retrieval rather than parametric knowledge, gives it a structural advantage for questions with verifiable answers. The current search-enabled boards have no Perplexity entry: HalluHard's best search-enabled score is GPT-6 Astra's 27.2%. [5]
The catch: Perplexity cites real URLs with fabricated claims. The sources look legitimate, with real websites and real publication names, but the information attributed to those sources may be invented. At a 37% citation hallucination rate, more than one in three source attributions could contain fabricated content. This makes Perplexity hallucinations harder to spot than hallucinations from models that don't present external citations.
The practical split: Perplexity for initial research and fact-finding where you'll verify key claims. Not for final-answer scenarios where someone reads the cited source and assumes the attribution is accurate.
Hallucination rates vary dramatically by subject matter. A model that looks reliable on general-knowledge benchmarks can be dangerously wrong on legal or medical questions. The domain with the strongest primary research is law.
Stanford RegLab and Stanford HAI tested the paid legal research tools marketed as "hallucination-free" (Magesh, Surani, Dahl, Suzgun, Manning and Ho, Journal of Empirical Legal Studies, April 2025). Lexis+ AI and Ask Practical Law AI gave incorrect or misgrounded answers on 17% of queries, Westlaw AI-Assisted Research on 33% and GPT-4 on 43%. Stanford HAI's summary puts the Westlaw figure at more than 34%. General-purpose chatbots did worse on specific questions about federal court cases, with hallucination rates from 58% (GPT-4) to 88% (Llama 2) (Dahl, Magesh, Suzgun and Ho, Journal of Legal Analysis, 2024). Both studies tested 2023-2024 product versions, not today's. [36][96][97] A newer test by Vals AI (October 14, 2025) put 200 U.S. legal research questions to three legal AI tools and ChatGPT. Where they answered, the legal tools were fully correct on 78-81% of questions and ChatGPT on 80%. Lexis+ AI and Westlaw were not in the test. [112] Domain-specific reliability claims need domain-specific checks.
Agentic legal work shows the same gap. Harvey LAB-AA v1.1, which Artificial Analysis launched with Harvey on October 8, 2026, checks every deliverable from 120 private legal tasks against its source documents and credits a task only when it contains no material hallucination. Across the models tested at launch, more than 60% of otherwise passing results contained one. Without the check, Muse Spark 1.3 would have led with a 26.7% all-pass rate, but two thirds of those passes contained a material hallucination. On the live board Meta's Muse Wonder Full now leads at 13.1%, ahead of Muse Wonder (10.0%) and Grok 4.7 (9.4%). [139]
Court decisions involving AI-hallucinated material rose sharply through 2025 and have stayed high in 2026.
Damien Charlotin's database lists 2,266 court decisions worldwide in which a party relied on AI-hallucinated material, 1,535 of them in U.S. courts (last updated November 5, 2026). By decision date, it shows 16 decisions in 2023, 61 in 2024 and 865 in 2025, plus 1,324 from January 1 to November 3, 2026. Older years keep growing as past rulings are found: a month earlier the database held 855 decisions for 2025. In May 2025 it showed 10, 37 and 73 for 2023, 2024 and the first five months of 2025. New decisions ran at about 145 a month from January to August 2026, close to five a day, and the database lists 24 decisions dated March 31, 2026 alone. The live count on any later day will be higher than the one printed here. [37][38]
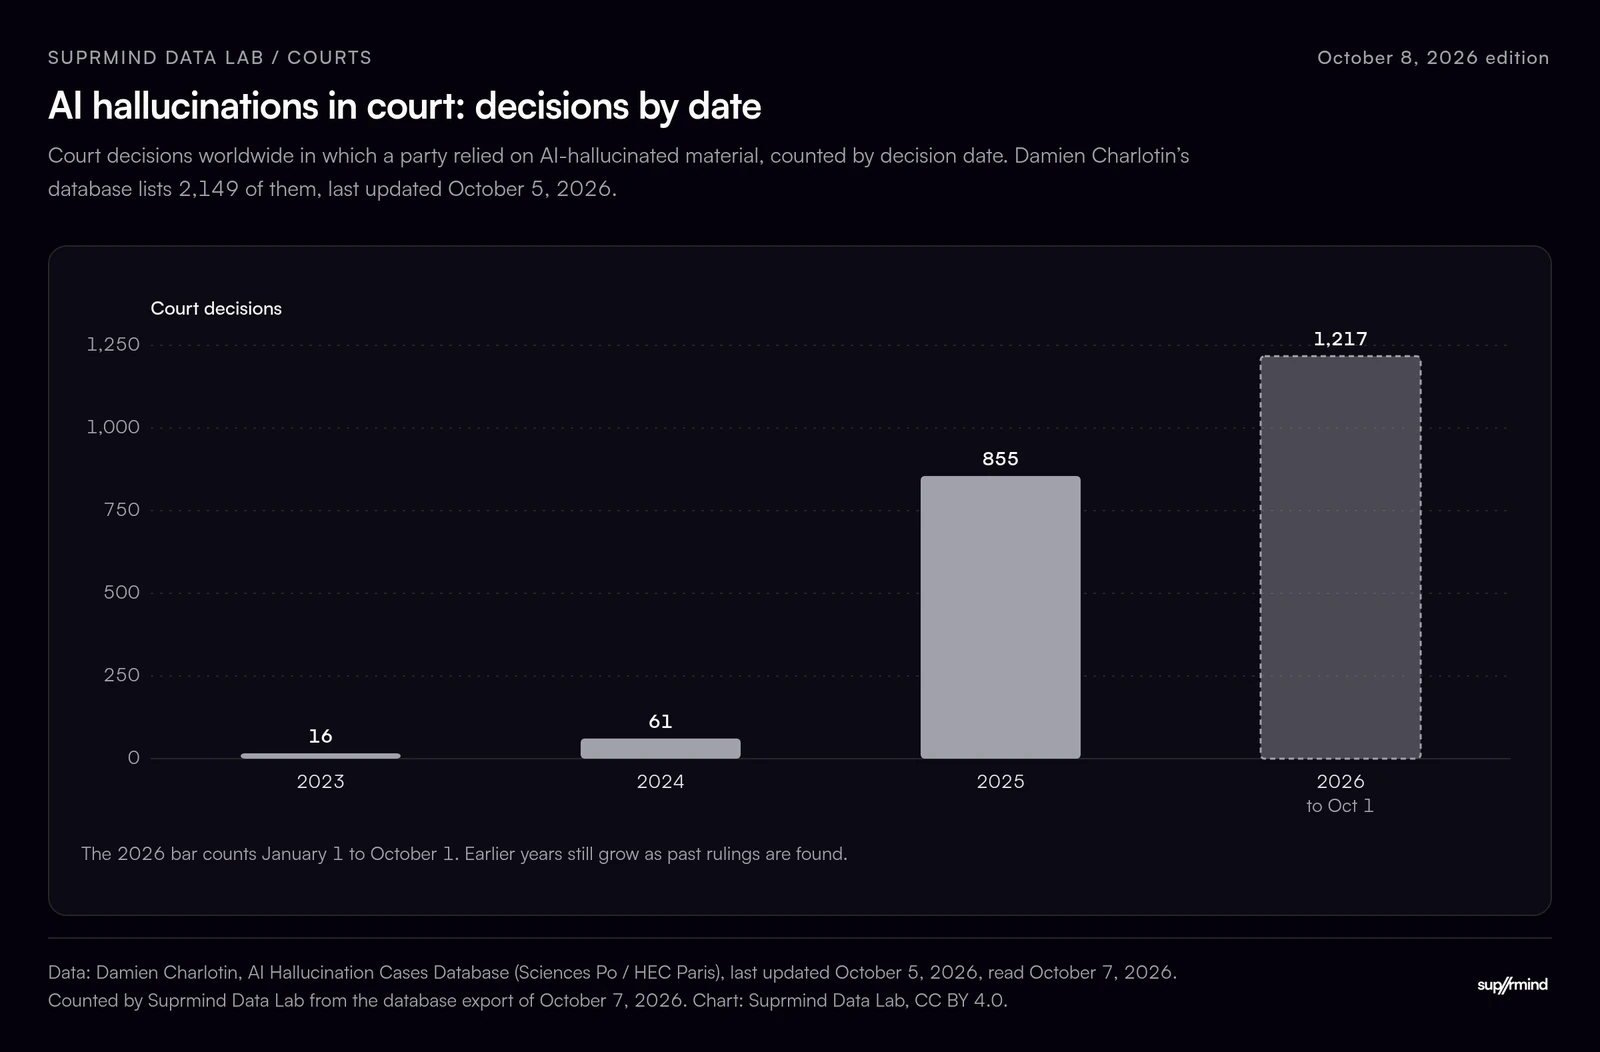
Self-represented litigants still account for most cases, 1,305 of the 2,266, but lawyers appear in 898 (database filters, November 5, 2026). In May 2025, Business Insider reported legal professionals at fault in at least 13 of 23 recent cases. In February 2025, Morgan & Morgan, one of the largest U.S. personal injury firms, emailed its more than 1,000 lawyers that AI can invent case law and that filing fake citations could cost them their jobs. Days later a federal court in Wyoming fined the firm's lawyers in Wadsworth v. Walmart. [37][38][114]
Penalties have grown. The largest U.S. amount in the database is US$110,204 in Couvrette v. Wisnovsky (D. Oregon, March 23, 2026), a US$15,500 sanction plus about US$94,700 in costs. By our tally of the database's U.S. dollar amounts, the highest quarter so far is Q4 2025, at about US$391,000 across 42 decisions, followed by Q1 2026 at about US$361,000 across 35. These totals include costs awards, not only fines. The Fourth Circuit publicly admonished a lawyer on March 11, 2026 (In re Nwaubani). Monthly counts rose through 2025 and held at roughly 125-185 decisions a month from January to August 2026, the months that are close to complete. [37]
The filers now include government lawyers. On October 21, 2026, the Federal Labor Relations Authority found that 22 of 29 footnotes and 35 of 42 legal or record citations in exceptions filed by the U.S. Department of Health and Human Services were fictitious, erroneous or irrelevant, including a citation to a decision that does not exist. It said the agency may have used a generative AI tool, denied the exceptions and imposed no sanction (74 FLRA No. 87). Two days later, in U.S. ex rel. Phillips v. Los Angeles Film School (C.D. California), the court sanctioned the relators' lawyer US$5,000 under Rule 11 for AI-fabricated case law, ordered continuing legal education and made a bar referral. [140][141]
The benchmark data explains why. On the central holding of a case, the published Dahl study found hallucinations in at least 63% of answers, a lower bound. Stanford HAI's January 2024 summary of the earlier preprint, before GPT-4 was added, gave at least 75%. [36][97]
ECRI, the patient safety nonprofit, ranked risks from AI-enabled health technologies as the top health technology hazard for 2025. For 2026 it ranked misuse of AI chatbots first, citing chatbots that suggested wrong diagnoses, recommended unnecessary tests and invented body parts while sounding like a trusted expert (January 21, 2026). [39][108]
The FDA's public list of AI-enabled medical devices holds 1,614 authorized devices, up from 637 through 2022 (list current as of September 4, 2026). A separate study of 950 of these devices found 60 (6.3%) linked to 182 recall events, with 43.4% of recalls within 12 months of clearance (Lee et al., JAMA Health Forum, August 22, 2025). Most recalls were for diagnostic or measurement errors, not chatbot-style hallucination. [107][106]
A 2025 study planted one made-up detail, such as a fake lab value or condition, in each of 300 physician-checked clinical vignettes and asked six models to respond (Omar et al., Communications Medicine, August 2, 2025). The models built on the fake detail in 50-82% of cases. A mitigation prompt cut the average from 66% to 44%. GPT-4o did best, falling from 53% to 23%. A distilled DeepSeek-R1 model did worst, at 80.0-82.7% by default. [105]
OpenAI reports that GPT-5 with thinking hallucinated on 1.6% of its HealthBench Hard hallucination test, against 3.6% without thinking, 12.9% for o3 and 15.8% for GPT-4o (August 7, 2025). This is a vendor-run test. [109]
HealthBench Professional (April 2026): OpenAI's newer benchmark scores models on 525 physician-written tasks from real clinician use, across care consult, writing and documentation, and medical research. In OpenAI's paper, GPT-5.4 inside ChatGPT for Clinicians scored 59.0, base GPT-5.4 48.1 and specialist physicians with web access 43.7. On consult tasks the gap was 51.0 to 42.7. OpenAI built and graded the benchmark, and picked examples that are hard for its own models. [60] Separately, on HealthBench Hard, the hard subset of the original HealthBench, Meta reported Muse Spark at 42.8 at its April 8, 2026 launch. [71]
October 2026 update: OpenAI's GPT-6 Astra launch table gives length-adjusted HealthBench Professional scores of 63.4% for GPT-6 Astra, 60.9% for Claude Fable 5, 60.5% for GPT-5.6 Sol, 58.1% for Claude Fable 5.1, 56.4% for Claude Opus 5 and 52.1% for Gemini 3.8 Flash. These are vendor-reported. [110]
Financial AI hallucinations don't make headlines the way legal ones do. There is no court docket for a wrong number in a model, which is also why the domain has the thinnest primary data on this page.
What can be sourced: EY's 2025 Responsible AI Pulse puts the average loss from AI-related incidents at $4.4 million per affected organization (n=975 C-suite), a figure that covers AI risk broadly, not hallucination alone. [79] A Stanford study found that all 24 models tested struggled to flag a false belief once the user stated it as their own. DeepSeek R1's accuracy fell from over 90% to 14.4% (Nature Machine Intelligence, November 3, 2025). That is the failure that matters most when the false premise is a valuation assumption. [111]
The strongest financial signal is first-party. In the Suprmind Multi-Model AI Divergence Index, AI models contradicted each other about twice as often on financial questions as on medical ones: 40% against 20% of turns under a blind judge. Legal questions came close behind, at 34.5% against finance's 39.9%, too close to tell apart. Where the stakes are a portfolio or a contract, one model's answer is among the most likely to be contradicted by another. [61]
A set of widely circulated finance figures (a 15-25% hallucination rate on financial tasks, 2.3 significant errors per quarter, $50,000 to $2.1 million per incident, a 20.0% versus 76.7% literature-reference comparison, and a $12.7 million SEC total) appeared in earlier versions of this page. None could be traced to a primary study, so they were removed in the August 27, 2026 revision, on the same rule that removed the untraceable business-impact figures on August 8.
Also on its dedicated watch page.
$4.4 million is the average loss per company that experienced AI-related risks, conservatively estimated. The figure covers AI risk broadly, such as regulatory non-compliance and biased outputs, not hallucination alone. EY Responsible AI Pulse, October 8, 2025 (975 C-suite leaders at companies with over US$1 billion in revenue). [79]
51% of respondents from organizations using AI say their organization has seen at least one negative consequence from AI, and nearly one-third report consequences from AI inaccuracy. McKinsey State of AI, November 5, 2025 (n=1,993). [80]
4.5 hours per week is the average time enterprise AI users spend revising or redoing AI output. 74% say low-quality AI output has caused at least one negative consequence, and 24% a compliance, legal or accuracy issue. Zapier survey of 1,100 U.S. AI users, published January 14, 2026. [81]
Inaccuracy is one of the two AI risks that most organizations say they are working to mitigate. McKinsey State of AI, November 5, 2025. [80]
AI-specific governance roles grew 17% in 2025, and the share of businesses with no responsible AI policy fell from 24% to 11%. Stanford AI Index 2026. [58]
At least 53 papers accepted at NeurIPS 2025 contained AI-hallucinated citations that got past three or more peer reviewers each. GPTZero found 100 confirmed fake citations after scanning 4,841 accepted papers (January 21, 2026). The main track accepted 24.52% of 21,575 valid submissions. [45][116]
A February 2026 follow-up analyzed those 100 citations across 53 papers, about 1% of the accepted program, each reviewed by three to five experts. 66% were total fabrications, 27% were real papers with corrupted details such as wrong authors or venues, and 4% hijacked a real identifier. Every one of the 100 combined at least two failure modes, such as a fake title on a plausible venue or a real DOI that points to an invented paper. That is what let them pass. [95]
When hallucinated citations pass peer review at the field's top venue, the verification problem extends beyond enterprise into the foundations of AI research itself.
Stanford HAI published its 2026 AI Index Report in April 2026. Its responsible AI chapter has three findings that bear on hallucination. [58]
362 documented AI incidents in 2025, up from 233 in 2024. That is a 55% rise and a record for the AI Incident Database. [58]
Hallucination rates of 22% to 94% across 26 top models. The AI Index charts AA-Omniscience hallucination rates, from 22% for Grok 4.20 Beta 0305 to 94% for gpt-oss-20B (high). [58][2]
Models confuse belief with fact. A Stanford study tested 24 models on 13,000 questions. When a false belief was stated as the user's own, GPT-4o's accuracy fell from 98.2% to 64.4% and DeepSeek R1's from over 90% to 14.4% (Nature Machine Intelligence, November 3, 2025). The model goes along with the user even when the user is wrong. [58][111]
88% of surveyed organizations report regular AI use in at least one business function, up from 78% a year earlier (McKinsey State of AI, November 2025, cited in the 2026 AI Index). McKinsey's August 2026 survey still finds nearly nine in ten, with 44% now scaling AI across the enterprise, up from 38%. Average Foundation Model Transparency Index scores fell from 58 to 40, with gaps in disclosure on training data, compute and post-deployment impact. [58][80][113]
One of the most counterintuitive findings in 2025-2026 hallucination research: the AI models marketed as most intelligent are often the least reliable on basic factual tasks.
Reasoning models (GPT-5 with thinking, Claude with extended thinking, DeepSeek-R1) use chain-of-thought processes that dramatically improve performance on complex problems. They're measurably better at math, logic, multi-step analysis, and medical diagnosis.
They're also measurably worse at sticking to facts they've been given.
Vectara new dataset: At its November 2025 launch, the thinking models Vectara named, including GPT-5, Claude Sonnet 4.5 and Grok-4, all exceeded 10% hallucination, and Gemini-3-Pro read 13.6%. Grok-4-fast-reasoning reads 20.2% on the current board. Non-reasoning models like Gemini-2.5-Flash-Lite scored 3.3%. OpenAI's GPT-6 models have narrowed the gap since, at 6.5% for GPT-6 Sol and 8.7% for GPT-6 Astra. [102][1]
DeepSeek: R1 (reasoning) hallucinates at 14.3% on Vectara vs V3 (base) at 3.9%. Nearly a 4x difference from the same provider. Vectara analysis found R1 produces 71.7% "benign hallucinations" (plausible-sounding additions) compared to V3's 36.8%. [48][49]
DeepSeek V4 (April 2026): The pattern held at a greater extreme. V4 Pro and V4 Flash post AA-Omniscience hallucination rates of 94% and 96%, among the highest ever recorded, while ranking near the top of open-weights models for coding and agentic work. Strong capability, almost no calibration. [70]
PersonQA regression: OpenAI's o3 hallucinates 33% on questions about real people vs o1's 16%. The o4-mini is worse at 48%. These are newer, more capable models performing worse on a basic factual test. [53][54]
GPT-5 thinking mode: HealthBench hallucination drops to 1.6% (excellent). But on Vectara's new dataset, GPT-5 (high) reads 15.1% (poor). Same model, same thinking mode, opposite results depending on the task.
GPT-5.5 (April 2026): AA-Omniscience accuracy of 57% (a record at the time) paired with an 86% hallucination rate. Knowledge expansion appears to have outpaced calibration improvements at the frontier. Claude Opus 4.7 took the opposite trade at its launch: 36% hallucination at lower raw accuracy (42.3% in its final v1 record). [2][58][63]
The 2026 flagships: the pattern moved to the very top of the leaderboard. On AA-Omniscience v1, Claude Fable 5 (65% accuracy / 63.6% hallucination), Claude Opus 5 (61% / 60.8%, up from Opus 4.8's 39.3%), GPT-5.6 Sol (59.4% / 92.2%, the highest rate of any OpenAI flagship), Grok 4.5 (51.6% / 54.1%, doubled from Grok 4.3), and Kimi K3 (47.6% / 53.2%) all raised accuracy and raised hallucination in the same release. The most capable models shipped in 2026 are among the most overconfident. Before September, counterexamples included Gemini 3.1 Pro (February 2026), which cut Gemini 3 Pro's rate from 91.5% to 50.9%, and Grok 4.6 (August 2026): 48.2% accuracy and 34.3% hallucination, a 19.8-point calibration gain for a 3.4-point accuracy cost. It proves the trade is a choice, not a law. September's releases split the field on v1: GPT-6 Astra cut OpenAI's rate to 51.3% while gaining accuracy (62.6%), Grok 4.7 cut xAI's again to 29.3%, and Gemini 4 Argon read 15.1%, while Claude Fable 5.1 went the other way, to 72.6%. On AA-Omniscience v1.1, Gemini 4 Carbon (October 2026) shows the trade can be avoided at the top: the highest Index on the board, 53.5, with an 11.4% hallucination rate. [2][72][75][88][125]
The mechanism is straightforward. When a reasoning model processes a summarization task, it doesn't just extract. It thinks. It draws inferences, identifies patterns, and generates insights. These additions go beyond the source document. On a benchmark measuring faithfulness to source material, every insight the model adds counts as a hallucination.
It's the difference between "summarize this contract" and "analyze this contract." Reasoning mode adds analysis even when you ask for a summary. That analysis is often useful. On a summarization benchmark, it's scored as a failure.
OpenAI's system card data reveals something that gets less attention: web access has a larger impact on hallucination rates than reasoning mode does. [11][8]
| Model | Browse-OFF | Browse-ON | Reduction |
|---|---|---|---|
| o4-mini FActScore | 37.7% | 5.1% | 86% |
| o3 FActScore | 24.2% | 5.7% | 76% |
| GPT-5 thinking FActScore | 3.7% | 1.0% | 73% |
Source: OpenAI GPT-5 system card, hallucination rate with browsing disabled and enabled [8]. All three models are tested there on the same FActScore prompts.
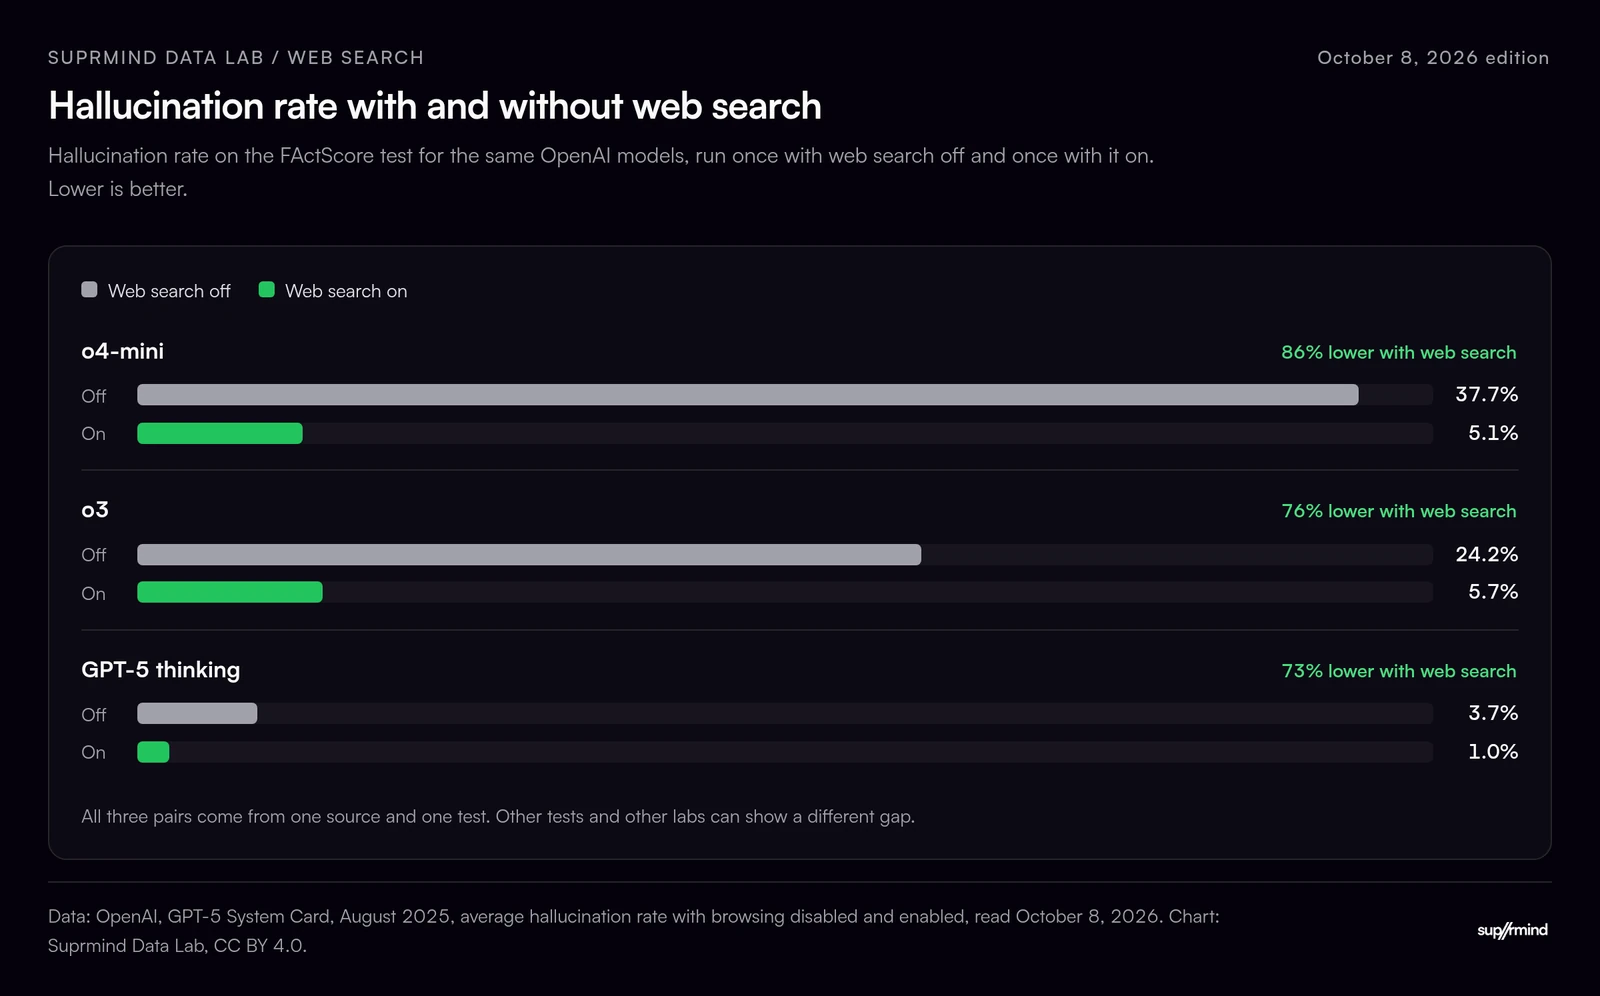
Turning on web search reduces hallucination more than turning on reasoning.
For enterprise deployments, ensuring tool access is more impactful than selecting reasoning vs non-reasoning model variants.
This creates a practical matrix for model selection:
Reasoning ON + Web ON: Best for complex analysis, medical diagnosis, multi-step research where both depth and access to current information matter. Lowest hallucination rates on open-ended tasks.
Reasoning OFF + Web ON: Best for document summarization, RAG pipelines, grounded Q&A where you want the model to stay close to source material. Lower risk of "overthinking" additions.
Reasoning ON + Web OFF: Risky combination. The model overthinks and can't verify. Suitable only for closed-world logic problems, math, and code where external facts aren't needed.
Reasoning OFF + Web OFF: Highest hallucination risk across the board. Avoid for any factual task.
This isn't speculation. Two independent research teams have published formal impossibility results. They are conditional on the formal models they use, which matters, but both point the same way: you can drive hallucination down, you cannot guarantee it away.
Xu, Jain and Kankanhalli (2024) formalized the hallucination problem through learnability and computability and proved that for a general-purpose language model, some inputs will always produce outputs that diverge from the computable ground truth. Not difficult. Not fixable with more compute or better training data. Unavoidable, in their formal setting. One honest caveat: the result is about the class of problems a general model faces, not a fixed error rate on every prompt. On a narrow enough task a model can approach perfect accuracy. On open-ended questions, it cannot be guaranteed to. [20]
The core argument: any system that generates text by predicting probable sequences from learned statistical distributions will, across the full range of things it can be asked, sometimes produce outputs not grounded in fact. The generative mechanism itself guarantees it.
Karpowicz (2025) attacked the problem from three different mathematical frameworks (auction theory, proper scoring theory, and log-sum-exp analysis for transformer architectures) and reached the same conclusion each time. [21]
No LLM inference mechanism can simultaneously achieve all four of these properties:
You can have any three. You cannot get all four. The math doesn't allow it, within the formal information-aggregation model the paper defines.
OpenAI publicly acknowledged these findings and identified three mathematical factors that make hallucination inevitable: [22]
Epistemic uncertainty: when information appears rarely in training data, the model has no reliable basis for generating accurate output about that topic but will attempt to anyway.
Model limitations: some tasks exceed what the architecture can represent, regardless of training data volume or quality.
Computational intractability: certain verification problems are computationally hard enough that even a theoretical superintelligent system couldn't solve them in reasonable time.
Hallucination is not a bug being fixed in the next model release. It's a structural property of how language models work: reducible by training, tools and verification, not removable by any of them.
This changes the question. Every AI hallucinates, so the right question isn't "which AI doesn't hallucinate?" The right question is: what systems do you have in place to catch hallucinations before they reach a decision-maker?
The organizations getting this right aren't waiting for a hallucination-free model. They're building detection layers, cross-validation pipelines, and human review checkpoints. The data on what works (and how much it helps) is in the Reduction Techniques section below.
Not all hallucination reduction techniques are equal. Some are backed by controlled studies with precise measurements. Others have strong theoretical support but limited production data. This ranking reflects the evidence base, not marketing claims.
| Technique | What was measured | Without | With | Change | Evidence |
|---|---|---|---|---|---|
| Web search access [8] | FActScore hallucination rate, OpenAI o4-mini | 37.7% | 5.1% | 86% lower | Vendor test. o3: 76% lower. GPT-5 thinking: 73% lower |
| Retrieval (RAG) | No controlled test isolates it across vendors | No figure | No figure | Depends on setup | Best grounded-summary score on Vectara: 1.8% |
| Reasoning (thinking) mode [109] | HealthBench Hard hallucinations, GPT-5 without and with thinking | 3.6% | 1.6% | 56% lower | Vendor test. Higher on grounded summarization |
| Cross-model ensembles (UAF) [24] | Factual accuracy on TruthfulQA, TriviaQA and FACTOR-news, against the best earlier mitigation methods | No figure | No figure | 8% higher accuracy | Peer-reviewed, WWW Companion 2025 |
| Chain-of-Verification [23] | FActScore on long-form biographies, Llama 65B (a score, higher is better) | 55.9 | 71.4 | 28% higher score | Peer-reviewed, Findings of ACL 2024 |
| VeriFY self-verification training [25] | Factual hallucination rate, open models from 2B to 12B, mostly TriviaQA | No figure | No figure | 9.7-53.3% lower | Preprint, February 2026. Recall 0.4-5.7% lower |
| A model version that guesses less [15] | AA-Omniscience hallucination rate, Gemini 3 Pro Preview to Gemini 3.1 Pro Preview | 88% | 50% | 38 points lower | Independent test (Artificial Analysis), similar accuracy |
| Clinical mitigation prompt [105] | Share of planted fake details the model built on, 300 clinical vignettes, average of six models | 66% | 44% | 33% lower | Peer-reviewed, Communications Medicine 2025. GPT-4o: 53% to 23% |
Each row comes from a different test, model and setup, so the changes cannot be compared across rows. The March 2026 edition showed these as one ranked bar chart, and two of its bars mixed metrics or could not be traced to a primary study. Sources: [8][109][24][23][25][15][105]
Measured impact: 73-86% hallucination reduction (FActScore, browse-on vs browse-off)
The single highest-impact intervention documented in 2025-2026 research. On OpenAI's FActScore evaluations, o4-mini drops from 37.7% to 5.1% with web access and GPT-5 thinking from 3.7% to 1.0%. GPT-5.3 Instant shows 26.8% reduction when using web vs prior models. [8][10]
One scope note. The 73-86% range comes from OpenAI's own FActScore evaluations of its own models. The size of the effect varies by model, benchmark and search system, so treat it as the best-documented case rather than a universal constant, and expect any browse-on number to describe the model plus its search stack, not the model alone.
The mechanism is simple: instead of relying on potentially stale or incorrect training data, the model retrieves current information and grounds its response in external sources. For any enterprise deployment, enabling web or tool access should be the first configuration decision, not an afterthought.
Measured impact: Large and setup-dependent. No cross-vendor benchmark isolates it, and the "up to 71%" figure that circulated for enterprise knowledge-base tasks traces to a secondary compilation rather than a controlled study, so this page no longer quotes it as a benchmark result.
RAG connects models to external knowledge bases (company documents, databases, verified sources) and instructs the model to generate responses grounded in retrieved content rather than parametric memory. Hybrid retrievers combining sparse and dense methods achieve the strongest mitigation. Vectara's own leaderboard, which measures exactly this grounded setting, shows the best models under 2% and most frontier models between 5% and 14%. Retrieval narrows the problem, but it does not close it.
RAG is most effective for knowledge-gap hallucinations (the model lacks relevant training data). It's less effective for logic-based hallucinations (the model reasons incorrectly from correct premises). For enterprise document Q&A and knowledge base applications, RAG is the standard of care.
Measured impact: 56-59% fewer errors on OpenAI's medical and production tests, but more hallucination on grounded summarization [109][8]
GPT-5 with thinking hallucinated on 1.6% of OpenAI's HealthBench Hard hallucination test, against 3.6% without thinking. On production-like ChatGPT traffic with browsing on, 4.8% of GPT-5 thinking responses had at least one major incorrect claim, against 11.6% for GPT-5 main. Both are vendor-run tests, and both are large improvements.
But reasoning mode increases hallucination on Vectara's summarization benchmark (see Section 10). The impact is task-dependent. Enable reasoning for analysis, diagnosis, and complex queries. Disable it for summarization, extraction, and source-faithful tasks.
Measured impact: 8% higher factual accuracy than the best earlier hallucination-mitigation methods (UAF framework) [24]
Amazon's Uncertainty-Aware Fusion framework (WWW Companion 2025) combined multiple LLMs weighted by their accuracy and self-assessment quality. The key finding: different models excel on different question types, so combining them captures complementary strengths.
Cross-model disagreement detection catches hallucinations because models rarely fabricate the same false information. When one model makes an unsupported claim, others typically flag the inconsistency or provide conflicting data. Research on "wisdom of the silicon crowd" shows LLM ensembles can rival human crowd forecasting accuracy through simple aggregation.
The 8% figure understates the practical value. In production, multi-model approaches catch errors that no single-model check would flag, because the checking model has different training data, different biases, and different blind spots.
Measured impact: 28% FActScore improvement [23]
A four-step pipeline: generate baseline response, plan verification questions, answer those verification questions independently, then refine the final output. Published at ACL 2024, it outperforms zero-shot, few-shot, and chain-of-thought prompting on long-form generation accuracy.
The cost is latency and compute: four steps instead of one. For applications where accuracy matters more than speed (report generation, research synthesis, compliance documentation), the tradeoff is worth it.
Measured impact: 9.7-53.3% lower factual hallucination rates on open models from 2B to 12B [25]
VeriFY, described in a February 2026 arXiv preprint, teaches models to assess factual uncertainty during generation rather than relying on post-hoc checking. The model learns to verify its own claims as it produces them. Recall loss is modest: 0.4-5.7%.
This is a training-time intervention, meaning end users don't control it. Its value is in signaling where the field is heading: future model generations will likely internalize verification as a core capability rather than bolting it on after generation.
Measured impact: 38 percentage points lower AA-Omniscience hallucination rate (Gemini 3 Pro Preview 88%, Gemini 3.1 Pro Preview 50%) at about the same accuracy [15]
Artificial Analysis traced the drop to the model guessing less often when it does not know the answer, and its Omniscience Index rose 17 points. Neither Artificial Analysis nor Google's model card names the training method behind it. In their final v1 records the two models read 91.5% and 50.9%.
Like VeriFY, this is a provider-side intervention. Users benefit from it when selecting newer model versions but can't apply it themselves.
Measured impact: the average across six models fell from 66% to 44% on planted-detail clinical tests, and GPT-4o from 53% to 23% [105]
Structured prompts that instruct the model to constrain outputs to verified information, flag uncertainty, and avoid speculation. These work best in narrow domains with clear boundaries and well-defined terminology.
The medical results are encouraging but the absolute rates remain high (44% on average with mitigation is still dangerously wrong for clinical use). Domain prompts are a layer, not a solution.
Larger models alone: In Artificial Analysis's launch analysis, accuracy tracked model size and hallucination rate did not. The 2026 flagships confirmed it: on AA-Omniscience v1.1 the three most accurate models in our table, Claude Fable 5.1, Claude Opus 5.5 and GPT-6.1 Sol, all give a wrong answer more often than they decline (70.0%, 50.3% and 51.9%). Bigger models know more but don't necessarily know what they don't know.
Simple temperature reduction: Lowering generation temperature reduces variety but doesn't eliminate hallucination. The model still picks the most probable token. It just does so more consistently, including consistently wrong tokens.
"Be accurate" system prompts: Generic instructions to avoid hallucination show minimal measured effect. Models already "try" to be accurate. The issue is architectural, not motivational.
Web search and RAG you already run. The next measured reduction is models catching each other, the mechanism the production data below documents on 17,885 real questions.
Try Cross-Validation Free7 days free. No credit card. About twenty seconds to the first answer.
Research published across 2024-2026 increasingly converges on a specific finding: querying multiple AI models on the same question catches errors that single-model approaches miss. This isn't a theoretical argument. Multiple peer-reviewed studies provide measured evidence.
The Uncertainty-Aware Fusion (UAF) framework combines multiple LLMs weighted by two factors: each model's accuracy on the task and each model's ability to self-assess when it's uncertain. The measured result: 8% higher factual accuracy than the best earlier hallucination-mitigation methods on TruthfulQA, TriviaQA and FACTOR-news. [24]
The critical insight from the study: "LLMs' accuracy and self-assessment capabilities vary widely with different models excelling in different scenarios." No single model dominates all question types. GPT may be strongest on grounded tasks, Claude on knowledge-calibration tasks, Gemini on breadth-of-knowledge tasks. The ensemble captures all three strengths.
Models trained on different data, with different architectures and different alignment tuning, develop different failure patterns. When five models analyze the same question, they rarely fabricate the same false information.
One model claims a legal precedent exists. Four others don't mention it. That disagreement is a signal. A human reviewer can investigate the specific claim rather than reviewing the entire output.
This works because hallucinations are stochastic, not systematic. A model doesn't consistently hallucinate the same incorrect fact. It fills gaps with different plausible-sounding content each time. When multiple models fill the same gap with conflicting content, the gap becomes visible.
Multiple studies show that simple aggregation across LLM outputs can rival the accuracy of human crowd forecasting. The mechanism parallels Galton's ox-weight experiment and Surowiecki's "Wisdom of Crowds": individual estimates are biased, but the aggregate cancels out uncorrelated errors. [28]
For AI, this means: five models with 60% individual accuracy, with uncorrelated errors, can produce aggregate outputs significantly above 60% accuracy. The math favors diversity over individual excellence.
The academic findings above describe the mechanism. The Suprmind Multi-Model AI Divergence Index measures it on real questions. Its Q3 2026 Edition re-checked 17,885 real questions answered side by side by GPT, Claude, Gemini, Grok and Perplexity between July 30 and September 10, 2026, with model names hidden and answers in random order. A blind judge found at least one contradiction in 29.9% of them and at least one correction in 35.8%. Judges from OpenAI, Anthropic and Google then read 3,262 of the questions, to test which findings hold. [61]
What the index measures, and what it does not. A separate AI judge reads all the answers to a question and records each contradiction, correction and addition it finds between them. "Judged corrected by another model" is the judge's reading, not proof that an answer was wrong. The index complements accuracy benchmarks like Vectara and AA-Omniscience. It does not replace them. It is also Suprmind's own production measurement, not an independently reproduced benchmark, so its percentages should never be ranked against AA-Omniscience, Vectara or FACTS scores.
A blind judge found a correction in 45% of high-stakes turns, against 28% of low-stakes ones, at the same point in the conversation. Judges from OpenAI, Anthropic and Google all see the rise. The tone barely moves: on the judge's 1 to 10 scale of how assertive an answer reads, no model family moved more than 0.09 points between low-stakes and high-stakes questions, with both modes pooled. [61]
This is not a hallucination rate. It counts how often another model pushed back. But it points the same way as the confidence paradox earlier on this page: an answer reads about as sure on the questions where being wrong costs the most, so its tone is no warning.
AI models contradict each other about twice as often on financial questions as on medical ones: 40% against 20% of turns under a blind judge, at the same point in the conversation. Legal questions come second, close enough to finance that the two cannot be told apart: 34.5% against 39.9%. Finance and law, two of the domains where this page documents the costliest hallucinations, are where a second model is most likely to disagree with the first. [61]
In 32 of the 13,563 questions our production judge read (0.2%), no model added, corrected or contradicted anything. [61]
When two fact-check judges from different companies agreed on the outcome, they sided with the correcting model 18 times out of 23. Most disputes could not be settled: of 411 factual disputes traced word for word to both answers, the fact-checker settled 22%. These numbers describe Suprmind's setup and a small sample, not a ranking of which AI is right in general. [61]
When at least two of three AI judges, from OpenAI, Anthropic and Google, had to agree, GPT, Perplexity and Claude answers were judged corrected by another model on 3 to 4% of answers. Gemini and Grok answers: 6.5% and 7.4%. [61]
The academic research established that ensembles outperform individual models. The index shows the detection mechanism working on real questions from real users, not in benchmarks designed for it. The mechanism the research predicts is the mechanism the production data shows.
The honest caveat from the section above still holds: cross-validation raises detection probability, it does not guarantee zero hallucination. Models can still agree on the same wrong answer, and knowing that two models disagreed is not the same as knowing which one was right. Most factual disputes in the index could not be settled at all.
The disagreement is the signal. The verification is still the user's job.
Catches well:
Catches less well:
Multi-model validation is a detection layer, not a guarantee. It raises the probability of catching hallucinations. It doesn't eliminate them. The organizations getting the best results combine multi-model cross-validation with domain-specific verification, human review checkpoints, and tool-enabled grounding. [27]
There is still limited standardized public reporting measuring "five-model cross-validation reduces hallucination by X%" across domains under controlled conditions. The UAF framework's 8% improvement is the strongest single number. Production case studies from multi-model platforms are emerging but not yet published in peer-reviewed venues.
The safest evidence-based position: multi-model orchestration is a risk-reduction architecture that increases detection probability. It is not a guarantee of zero hallucination. No approach achieves that guarantee, as the mathematical proofs in Section 11 demonstrate.
Most hallucination detectors now ship inside LLM evaluation and monitoring platforms. They use a second model, a trained classifier or formal rules to check an answer against a source. Only three have been tested side by side by an outside party. The rest publish their own numbers or none.
| Tool | What It Checks | Outside Test Result | Status |
|---|---|---|---|
| W&B Weave | Hallucination scorer: an LLM judge checks output against source context and explains why | 91% accuracy, 86% caught, 95.6% precision (AIMultiple) | Active. Part of CoreWeave since May 2025 |
| Arize Phoenix | Open-source tracing with Hallucination and Faithfulness evaluators | 90% accuracy, 84% caught, 95.5% precision (AIMultiple) | Active |
| Comet Opik | Hallucination metric: an LLM judge returns a yes or no with reasoning | 72% accuracy, 44% caught, 100% precision (AIMultiple) | Active |
| Galileo Luna (now Splunk, Cisco) | Small evaluation models that grade and guard agent traffic in real time | No outside test found | Cisco completed the purchase May 22, 2026 |
| GPTZero Hallucination Check | Checks citations against web and academic sources | No outside test. Vendor says 99 of 100 flawed citations caught | Active |
| Future AGI | Evaluation, tracing and real-time guardrails for agents | No outside test found | Active |
| Vectara HHEM | Open model that scores whether a summary is supported by its source | Powers Vectara's leaderboard | Active |
| Amazon Bedrock Automated Reasoning checks | Checks answers against formal rules from your policies | No outside test. AWS says up to 99% accuracy at detecting correct responses | Available since August 6, 2025 |
| DeepEval | Open-source test framework with a hallucination metric | No outside test found | Active |
Sources: AIMultiple benchmark, updated June 18, 2026 [46]. Company and vendor pages: CoreWeave [121], Cisco and Splunk [115], GPTZero [116], Future AGI [47], Vectara [118], AWS [119], DeepEval [120]. Pythia is no longer listed: WiseCube, its maker, was bought by John Snow Labs in May 2025, and the product site is offline [117].
In AIMultiple's test of 100 answers (50 correct, 50 hallucinated), W&B Weave and Arize Phoenix were right 91% and 90% of the time overall. Accuracy is not the catch rate. Weave caught 43 of the 50 hallucinations (86%) and Phoenix 42 (84%), so about one in seven got through. Each also flagged 2 of the 50 correct answers. [46]
Comet Opik never flagged a correct answer, but it caught only 22 of the 50 hallucinations (44%). Pick the trade-off that fits the cost of a miss. In legal filings, medical decisions and financial reporting a miss costs more than a false alarm, so automated detection is one check among several, not the last one. The test is small, and AIMultiple lists Weights & Biases among its subscribers. [46]
Vectara has published its hallucination leaderboard on GitHub since November 2023, and the repository keeps every update. We read all 257 versions of the leaderboard file to find the lowest rate at each update. On the original test, the best score fell from 3.0% (GPT-4, November 2023) to 0.6% (Ant Group's Finix-S1-32B, August 2025). Vectara then moved to a longer, harder dataset in November 2025. There the best score started at 3.3%, and it has stood at 1.8% since December 2025. [1]
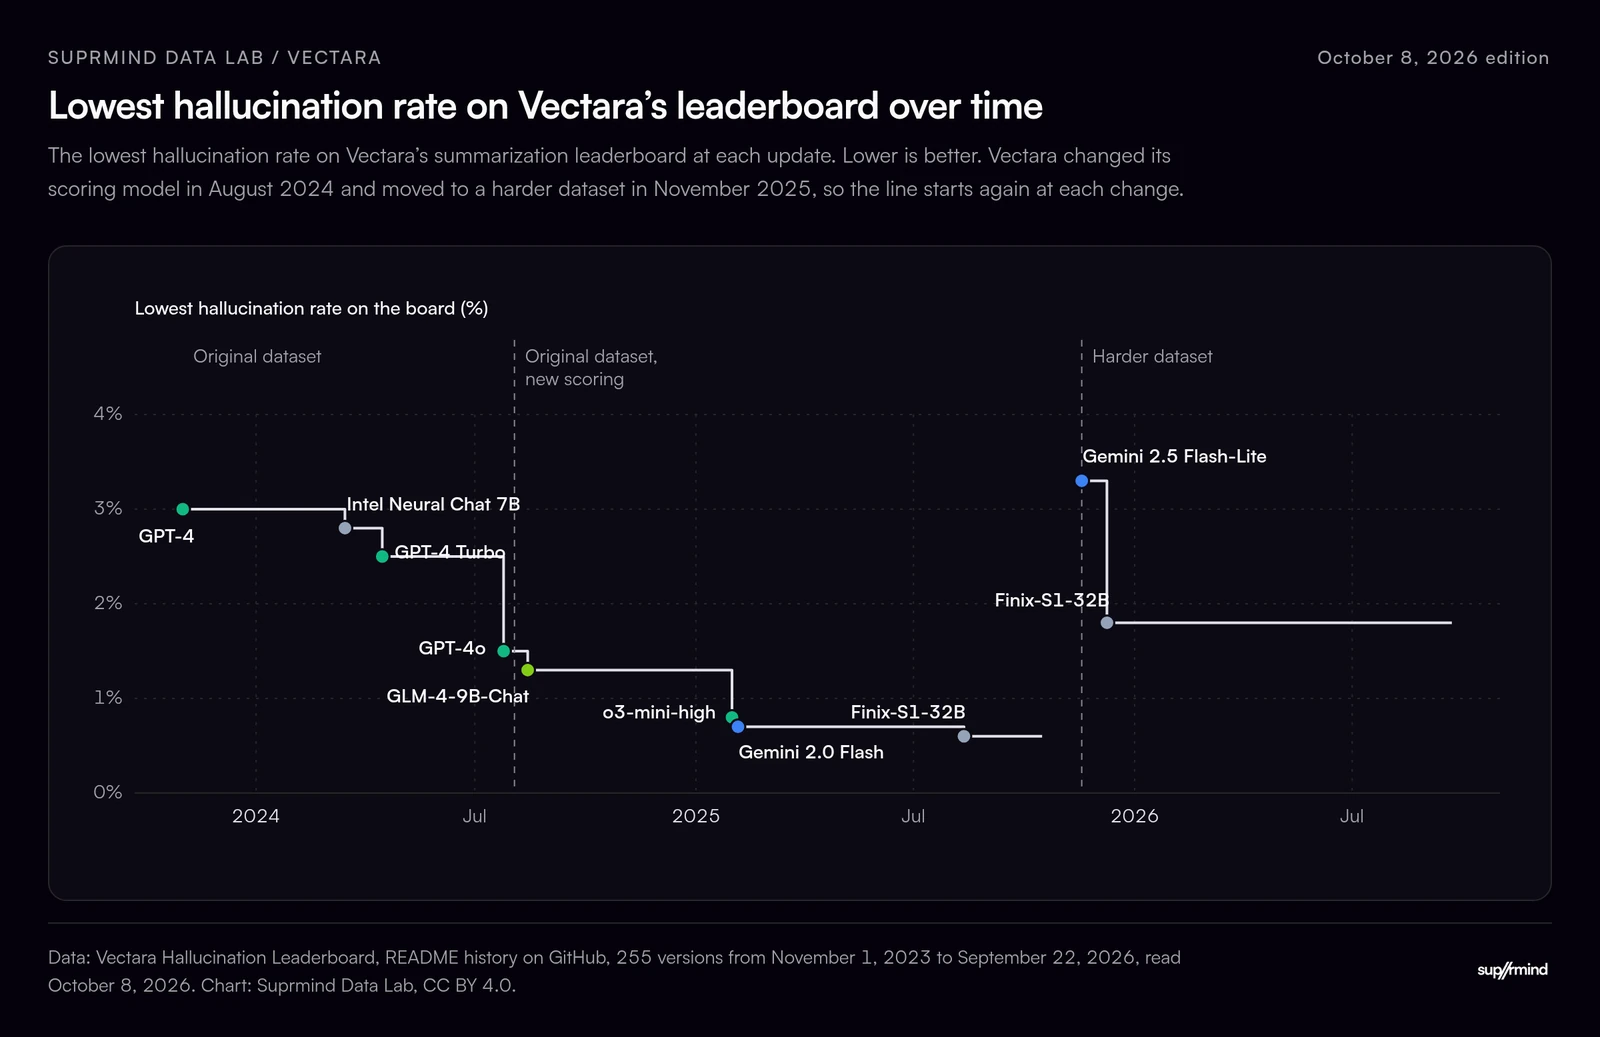
| Leaderboard update | Lowest rate | Model | Test |
|---|---|---|---|
| November 1, 2023 | 3.0% | GPT-4 (OpenAI) | Original dataset, HHEM-1.0 |
| March 15, 2024 | 2.8% | Intel Neural Chat 7B (Intel) | Original dataset, HHEM-1.0 |
| April 15, 2024 | 2.5% | GPT-4 Turbo (OpenAI) | Original dataset, HHEM-1.0 |
| July 25, 2024 | 1.5% | GPT-4o (OpenAI) | Original dataset, HHEM-1.0 |
| August 14, 2024 | 1.3% | GLM-4-9B-Chat (Zhipu AI) | Original dataset, HHEM-2.1 |
| January 31, 2025 | 0.8% | o3-mini-high (OpenAI) | Original dataset, HHEM-2.1 |
| February 5, 2025 | 0.7% | Gemini 2.0 Flash (Google) | Original dataset, HHEM-2.1 |
| August 12, 2025 | 0.6% | Finix-S1-32B (Ant Group) | Original dataset, HHEM-2.1 |
| November 18, 2025 | 3.3% | Gemini 2.5 Flash-Lite (Google) | New dataset, HHEM-2.3 |
| December 9, 2025 | 1.8% | Finix-S1-32B (Ant Group) | New dataset, HHEM-2.3 |
Source: Vectara Hallucination Leaderboard, README history on GitHub, 257 versions from November 1, 2023 to October 22, 2026, read November 7, 2026 [1][100]. Each row is the first update where that model held the lowest rate. Finix-S1-32B still held it on October 22, 2026. In August 2024 Vectara re-scored every model with HHEM-2.1, so rates before and after that point are not directly comparable. An earlier edition of this page showed a four-year series from 2021, from a third-party compilation. Those earlier years could not be traced to a primary source, so they are no longer shown.
On the same test, the best score in August 2025 was a fifth of the November 2023 best. The leaders were not always frontier models: Intel's 7B Neural Chat held the top spot in March 2024, Zhipu AI's 9B GLM-4 in August 2024 and Ant Group's 32B Finix-S1 from August 2025. On short-document summarization, the improvement is real.
These improvements measure the easiest version of the problem: summarizing short documents without adding unsupported facts. When you move to harder, more realistic evaluations, the picture changes:
AA-Omniscience (hard knowledge questions): 52 of the 124 models on Artificial Analysis's v1.1 board (November 7, 2026) give more wrong answers than right ones. 72 have a positive Omniscience Index, and the three most accurate models in our table, Claude Fable 5.1, Claude Opus 5.5 and GPT-6.1 Sol, still give a wrong answer more often than they decline. On the v1 board of October 6, 2026, the split was 141 negative and 61 positive of 202. [2][88]
HalluHard (realistic conversations): Even the best entry on the board, GPT-6 Astra with web search, hallucinates 27.2% of the time, and Claude Opus 4.5 with web search 30.2%. Of its 41 entries, 10 are under 50%, 16 fall between 50% and 70%, and 15 are above 70%. [5]
Vectara new dataset (enterprise-length documents): Rates are higher than on the original dataset for most models, often several times higher: GPT-4.1 goes from 2.0% to 5.6% and GPT-5 (high) from 1.4% to 15.1%. The best score is 1.8% (finix_s1_32b), not 0.6%, and the best frontier-lab score is 3.1% (GPT-5.4 nano). Most frontier models sit between 5% and 14%. [1][100]
Domain-specific tasks: Purpose-built legal AI tools still err on more than 17% of queries (Stanford RegLab, 2025), and clinical tests with planted fake details reach 66% on average without a mitigation prompt. Specialized domains haven't shown the same improvement trajectory as general summarization. [36][105]
Improvement is real. But extrapolating from simple benchmarks to enterprise reliability is a mistake the data doesn't support.
This page draws from the following primary sources:
Benchmarks: Vectara HHEM Leaderboard (both the original ~1,000 document dataset and the refreshed 7,700-article dataset), Artificial Analysis AA-Omniscience, Google DeepMind FACTS Benchmark, OpenAI SimpleQA and PersonQA, Google DeepMind's SimpleQA Verified, HalluHard (EPFL and the ELLIS Institute Tübingen), and the Columbia Journalism Review citation accuracy study.
System cards and technical reports: OpenAI GPT-5 system card, GPT-5.2 deployment update, o3/o4-mini system card, Anthropic model announcements for Claude Opus 4.5/4.6/4.8/5 and Sonnet 4.6/5, xAI's Grok 4.6 model card, Google's Gemini 3.7 Flash announcement, Google DeepMind FACTS methodology paper, and for the November 2026 update Anthropic's Claude Haiku 5.5 system card, OpenAI's GPT-6.1 Terra announcement, Google's Gemini 4 Carbon and Gemini 4 Argon announcements, and the launch posts for Muse Wonder, Muse Spark Open, Kimi K3.1 Pro, Mistral Large 4, Tencent Hy4, MiniMax-M3.1-Flash, DeepSeek V4.1 Flash 1017 and Inkling 2 Small.
Industry studies and incident data: Stanford RegLab/HAI legal AI study, Communications Medicine clinical hallucination study, JAMA Health Forum AI device recall study, Nature Machine Intelligence KaBLE belief-versus-fact study, FDA AI-enabled medical device list, EY Responsible AI Pulse survey, McKinsey State of AI survey, Zapier workslop survey, Business Insider court ruling tracker, Damien Charlotin legal citation hallucination database, and the GPTZero/Fortune NeurIPS 2025 analysis.
Academic research: Xu et al. (2024) on impossibility of hallucination elimination, Karpowicz (2025) on mathematical impossibility across three proof frameworks, Amazon's Uncertainty-Aware Fusion framework (WWW Companion 2025), VeriFY training-time verification (arXiv preprint, February 2026), Chain-of-Verification (Findings of ACL 2024).
April 2026 additions: Stanford HAI 2026 AI Index Report (AA-Omniscience hallucination chart and AI incident database), Vectara HHEM April 20, 2026 snapshot, Artificial Analysis AA-Omniscience April 2026 state (Claude Opus 4.7, GPT-5.5, Grok 4.20), Damien Charlotin database (1,200+ legal cases), OpenAI HealthBench Professional, and the Suprmind Multi-Model Divergence Index April 2026 edition.
June 2026 additions: Artificial Analysis AA-Omniscience figures for Claude Opus 4.8 (released May 28, 2026), Gemini 3.5 Flash (May 19, 2026), Grok 4.3 (April 2026), and DeepSeek V4 Pro and V4 Flash (April 24, 2026), plus Muse Spark (Meta, April 2026) on HealthBench Hard. One caveat applies to Gemini 3.5 Flash: Google did not publish a first-party hallucination figure for it, so the 61% rate cited here is Artificial Analysis independent measurement, not a vendor number. [64][68]
July 2026 additions: Artificial Analysis AA-Omniscience figures for Claude Fable 5 (June 9), GPT-5.6 Sol (July 9), Grok 4.5 (July 8), Kimi K3, Muse Spark 1.1, Command A+, and Qwen3.7 Max. Grok 4.3's standalone AA profile (high and medium), replacing the earlier derived estimate. The Charlotin legal database at 1,769 cases (July 17). The enterprise-adoption figure, corrected from a mis-attributed "85% Gartner" to 88% organizational adoption (McKinsey State of AI 2025, via Stanford HAI 2026 AI Index). Two figures were shown at reduced confidence in that revision: GPT-5.6 Sol appeared with accuracy only, and Claude Sonnet 5's AA triad was flagged provisional. Both were resolved in the August 27 revision below. The FACTS table is the December 2025 Suite launch snapshot. [72][78]
August 8, 2026 revision: Business-impact figures re-sourced to primary studies: EY Responsible AI Pulse (October 2025, n=975 C-suite), McKinsey State of AI (November 2025, n=1,993), Zapier (January 2026, n=1,100), and Cash and Oppenheimer in Memory & Cognition (2025) for the confidence paradox. Removed as untraceable to any primary source: the $67.4B global-loss estimate, a "47% of executives" claim attributed to Deloitte, Forrester per-employee verification costs, a Gartner 318% market-growth figure, and an aggregator-sourced domain rate table. [79][80][81][82]
August 27, 2026 revision: Added Claude Opus 5 (July 24), Grok 4.6 (August 12), Gemini 3.7 Flash (August 13), Muse Spark 1.2 (August 5), Qwen3.8 Max Preview (August 3), GLM-5.3 (August 14) and the DeepSeek V4 Pro 0813 GA build (August 13), each with its AA-Omniscience triad from the August 26-27, 2026 AA-synced snapshot (167 models). Claude Fable 5 re-scored to Index 43 / 65% accuracy / 63.6% hallucination, confirmed against Artificial Analysis's own page. GPT-5.6 Sol, Terra and Luna given the hallucination rates and Index values now on the board. Claude Sonnet 5 updated and its "provisional" flag retired. Every added or updated row was checked for internal consistency (Index equals correct minus incorrect). Rows that pre-date August keep the launch figures this page first cited, with the August re-pull listed in the AA source note. Six pre-2026 rows (Claude Opus 4.7, Opus 4.6, Opus 4.5, Sonnet 4.6, GPT-5.1, GPT-5.2) could not be reconciled to a single configuration on the current board and are unchanged pending a direct re-pull. Vectara original-dataset table corrected against the archived branch: finix_s1_32b leads at 0.6%, and five rows that belonged to the new dataset were moved there. Legal figures corrected to the published papers (17-33% for legal tools, 58-88% for general-purpose chatbots). Charlotin count updated to 1,963. Removed as untraceable to a primary study: the finance-domain figures (15-25% rate, 2.3 errors per quarter, $50K-$2.1M per incident, 20.0% vs 76.7% literature test, VC and robo-advisor anecdotes, $12.7M SEC total) and the "RAG up to 71%" reduction figure. Added BullshitBench v2 and the NeurIPS fabricated-citation taxonomy as new sources. [83][88][94][95][100]
October 6, 2026 revision: Added GPT-6 Astra (September 3), GPT-6 Sol (September 22), GPT-6.1 Sol (September 29), GPT-6 Luna, Claude Fable 5.1 (September 1), Claude Opus 5.5 (September 22), Claude Sonnet 5.5 (September 28), Gemini 4 Argon (announced September 30, not yet publicly available), Gemini 3.8 Flash (September 2), Gemini 3.5 Flash-Lite, Grok 4.7 (September 21), Muse Spark 1.3 (September 2), Qwen3.8 Max 0902 (September 2) and DeepSeek V4.1 Flash. Every AA-Omniscience value that Artificial Analysis still lists was re-read from its own model records on October 4, 2026, and 30 earlier rows were corrected or completed, for example Gemini 3 Pro's hallucination rate from 88% to 91.5% and Claude Opus 4.7's from 36% to 42.3%. Vectara new-dataset scores added from the September 22, 2026 board for GPT-6 Astra, GPT-6 Sol and GPT-5.6 Sol, plus Claude Opus 4.7, Claude Opus 4.5 and Gemini 3 Flash. Grok 4.1 Fast's Vectara figure corrected from 20.2% (Grok 4 Fast's score) to 19.2%. Charlotin legal count updated to 2,149 cases (October 5). Quick findings, model profiles and the FAQ rewritten for the new data. The update note now describes continuous updates instead of a monthly schedule. [2][1][37]
October 7, 2026 revision: The four headline figures at the top of the page now come from the October data: Gemini 4 Argon's 15.1% (not yet publicly available) with Grok 4.7's 29.3% for public models answering at least 45% correctly, GPT-6 Astra's 51.3%, Claude Fable 5.1's 72.6%, and the 141 of 202 models with a negative Index on the October 6 board. They replace the EY $4.4M loss average, Vectara's 0.6% best case and Gemini 3 Pro's 91.5%, which are all still covered further down the page, and the August board count. Both AA-Omniscience tables were rebuilt from Artificial Analysis's October 4 records (at first keeping Claude 4.1 Opus's November 2025 figure, removed later the same day, see the corrections below): the top 30 by accuracy, and a full ranking by hallucination rate with accuracy alongside (57 models then, 56 now). The AA-Omniscience release notes now run newest first, with launch figures and the current record side by side. The "three most accurate models" statements now name Claude Fable 5.1, Claude Opus 5.5 and Claude Fable 5. [2][88] Later the same day, the Vectara new-dataset, HalluHard and SimpleQA Verified figures moved to their current boards and the FACTS section added the 2026 Kaggle board. The Vectara new-dataset table now shows 35 of the 108 models from the September 22, 2026 snapshot, HalluHard figures come from its October board (GPT-6 Astra 27.2%, Claude Opus 4.5 30.2%), and SimpleQA Verified is a new source. In the cross-benchmark table, five cells are now blank because they held another model's score or a score that does not exist: the Vectara (New) cells for o3-mini-high and Gemini 2.0 Flash and the FACTS cells for o3-mini-high, GPT-5.2 and Grok 4.1 Fast. GPT-5's Vectara (New) cell now shows its board figure, 15.1%, instead of "over 10%", and four blank Vectara cells were filled from the boards (Claude 4.1 Opus, Claude Sonnet 4.5, Claude 4.5 Haiku and GPT-5.1). The Vectara section's February 2026 snapshot table and its DeepSeek-R1-0528 row (an original-dataset figure) were removed, and the HalluHard reference now names the benchmark's authors and paper. [1][3][5][101] Later still, the head-to-head tables were rebuilt around the September flagships. In the Claude, GPT, Gemini and Grok tables each cell names the model behind it. Current figures come from Artificial Analysis's October 4 records, Vectara's September 22 board, the FACTS Kaggle board, SimpleQA Verified and HalluHard, with HalluHard compared within the same question set, and older results are labeled with their dates. The Grok table's approximate field averages were replaced with computed positions on each board. The model profiles now give each model's current AA-Omniscience record alongside its launch figures. Corrections: earlier versions of this page gave Claude 4.1 Opus a 0% AA-Omniscience hallucination rate, which no source supports. Artificial Analysis's launch analysis gives it 48%, third lowest at the time behind Claude 4.5 Haiku and level with Claude Sonnet 4.5, and the model is no longer on the current board. Its row has been removed from the AA-Omniscience ranking, which now lists 56 models, and its cross-benchmark cell is blank. Command A+ (14%) now heads the quick finding for the lowest rate, and the FAQ answers were corrected. Grok 4's launch figures are now the paper's 39% accuracy and 64% hallucination. Gemini 3 Flash is no longer called the most accurate model at its launch, because Gemini 3 Pro's 55.9% was higher. The Claude Opus 4.7 to 4.8 gap is 42 days, not 41. Qwen3.8 Max Preview's profile now gives both its July 19 preview date and its August 3 launch, and Gemini 3.5 Flash on May 19, not May 18. Qwen3.7 Max is no longer called the most aggressive abstainer, because Command A+ declines more often. The AA-Omniscience domain table's Business leader is GPT-5.1, not "GPT-5.1.1". GPT-5's 47% (SimpleQA without browsing) and 9.6% (claims with errors in browsing-enabled ChatGPT traffic) are now treated as two different metrics, and the browse table keeps only the three same-metric rows, all from OpenAI's FActScore evaluations. The browse-effect and reduction-technique chart captions now flag the bars that no longer match the text. Claude Opus 4.7's 36% in the reasoning section is now labeled as its launch figure, with the 42.3% current record alongside. Two references were added: Google's and Reuters' reports on Gemini 4 Argon's access and the Gemini 3.5 Pro cancellation, and the AA-Omniscience launch paper. A final check corrected DeepSeek V4 Pro's launch Index to -10 (the -23 was V4 Flash's), Qwen3.7 Max's release date to May 19, and GPT-6 Astra's accuracy lead over Gemini 3.1 Pro to 7.7 points, and the head-to-head tables now show GPT-6 Astra's high setting next to its max figures. [2][103][104]
October 7, 2026, second revision: Business impact, domain and detection tool figures were re-checked against primary sources. The AI Index's 22-94% range is now labeled as AA-Omniscience hallucination rates, and the belief-versus-fact figures are cited to Suzgun et al. (24 models). Clinical figures now use the published Communications Medicine averages (66% to 44%). The FDA device count is now 1,614, with recalls cited to a JAMA Health Forum study of 950 devices. Court counts, penalties and dates now come from the Charlotin database by decision date, and the legal chart caption pairs its May 2025 snapshot with current counts. HealthBench Professional scores now come from OpenAI's paper and its GPT-6 Astra launch table, and Muse Spark's 42.8 is labeled as a HealthBench Hard score. The McKinsey reference now links to the 2025 edition, and the August 2026 edition is added. The detection tools table now separates accuracy from catch rate, lists Galileo as part of Cisco and GPTZero's tool as Hallucination Check, drops Pythia and adds three tools. Removed as untraceable or unconfirmed: Testlio's 82% and 39%, AllAboutAI's 91% and 64%, the 70% generative AI figure, the cumulative Charlotin timeline, the HealthBench Hard scores for Grok 4.2 and Claude Sonnet 4.6, Muse Spark 1.1's 59.3 and the AI Index page count. [37][46][105][106][107][111]
October 8, 2026: The eight static charts from the March 2026 edition are gone. Live charts replace five of them: court decisions by date, web search off and on, the lowest rate on Vectara's leaderboard over time, accuracy against hallucination rate, and a two-model comparison. The leaderboard now also opens on its Vectara tab in the Vectara section. The composite radar chart is removed, and the reduction techniques chart is now an evidence table, because its rows measure different things. The historical trend now comes from Vectara's own GitHub history instead of a third-party compilation. Under the cross-benchmark table, the long notes paragraph is now a short key, one sources line and a dated list of data changes, and each row's note opens from an icon next to the model name. Corrected: VeriFY is a February 2026 preprint by Altinisik et al., not an ICML 2025 paper. The UAF paper is by Dey et al. (WWW Companion 2025), and its 8% gain is over earlier mitigation methods. The Gemini 3.1 Pro figures follow the Artificial Analysis article without the "calibration tuning" label. The o3 and o4-mini browse figures are cited to the GPT-5 system card. [1][8][15][24][25] Later the same day, every AA-Omniscience launch figure on the page was checked against Artificial Analysis's archived evaluation page. Corrected: Gemini 3 Pro launched at 53% accuracy, not 55.9% (a later re-run), and Gemini 3 Flash at 55%, the highest of any model tested at the time, which reverses an October 7 change. Gemini 3.1 Pro launched at Index 30 and 53% accuracy, Claude Opus 4.5 at 43% accuracy, and Claude Opus 5 at a 50% hallucination rate and 54% accuracy, so the page no longer dismisses the 50% figure. Claude Fable 5's higher record comes from Artificial Analysis's August 6, 2026 grader change, not a re-run in a different configuration. The cross-benchmark table's change list no longer calls GPT-5.1's 81% a re-score: it was GPT-5 (high)'s figure. A new chart compares launch figures with current records for 20 models. [2][122][123]
October 20, 2026: The Multi-Model AI Divergence Index figures on this page now come from its Q3 2026 Edition: the four tiles under the headline figures, the finance paragraph, the Production Evidence section and the methodology note. The April 2026 edition's provider comparisons, including the confidence-contradiction rates by provider and the catch ratios, were withdrawn in October 2026 and are no longer quoted here. The practical split for Claude and Gemini now adds that no single model is a safe default where you can't check the work. [61][62]
November 7, 2026 revision: AA-Omniscience figures now come from version 1.1, which Artificial Analysis launched on October 27, 2026 with a new question set and now lists for 124 models. The headline figures, quick findings, both AA-Omniscience tables, the leaderboard and scatter charts, the head-to-head tables, the model profiles and the FAQ use v1.1 records read November 7, 2026. The 37 models in our table that Artificial Analysis has not re-run keep their final v1 records of October 4, shown in grey with a v1 marker and left out of every ranking, and the October v1 ranking is kept as a collapsed table. The October press finding stays as a dated v1 result, and the drift chart stays on v1. Added 13 rows: Gemini 4 Carbon (high and medium, October 28, not yet publicly available), GPT-6.1 Terra (October 26), Claude Haiku 5.5 (October 7), Muse Wonder Full and Muse Wonder (October 12), Muse Spark Open (October 15), Kimi K3.1 Pro (October 23), Mistral Large 4 (October 29), Tencent Hy4 (November 4), MiniMax-M3.1-Flash (October 19), DeepSeek V4.1 Flash 1017 (October 17) and Inkling 2 Small (November 5). Gemini 4 Argon has been public since October 13 and loses its badge. Vectara's October 16 and 22 updates add Gemini 4 Argon (12.1%), Claude Opus 5.5 (9.9%) and DeepSeek V4.1 Flash (4.2%). The FACTS section and column now read the November 5 Kaggle board and rank only models scored on all four slices. SimpleQA Verified figures come from the October 20 board, and Claude Fable 5's BullshitBench figure is now 56%. Court figures come from the Charlotin database of November 5 (2,266 decisions), with the Harvey LAB-AA v1.1 legal benchmark and two October decisions added. Every changed cell in the cross-benchmark table is listed under the table. [2][124][125][1][3][101][37][139]
This page includes data from the Suprmind Multi-Model AI Divergence Index, a recurring publication on how AI models contradict and correct each other on real questions asked on the Suprmind platform. Its Q3 2026 Edition re-checked 17,885 real questions answered between July 30 and September 10, 2026, with model names hidden and answers in random order, and judges from OpenAI, Anthropic and Google read 3,262 of them. [61]
What the index measures: how often AI models contradict each other, correct each other and add what the others missed when they answer the same question.
What the index does not measure: factual accuracy against ground truth. "Judged corrected by another model" is a judge's reading, not proof that an answer was wrong. A small fact-check arm tests who was right in the disputes it can settle, and most disputes cannot be settled.
We treat the index and accuracy benchmarks as complementary, not interchangeable. Vectara, AA-Omniscience, FACTS and the other benchmarks on this page measure how often models are wrong in isolation. The index measures how often models challenge each other on real questions. Both questions matter. They are not the same question.
Question-level data is not published, because it contains user questions. Aggregate tables are available on request. The April 2026 edition's provider comparisons were withdrawn in October 2026, after a re-check found they came mostly from the order in which the judge read the answers. Earlier versions of this page quoted them. [62]
TruthfulQA: partially saturated. Included in model training data, contains some incorrect gold answers, and can be gamed to 79.6% accuracy by a decision tree that never sees the question. Kept out of the tables, but still useful for tracking one model family over time.
HaluEval: solvable by answer length. A classifier that flags answers over 27 characters as hallucinated achieves 93.3% accuracy, undermining the benchmark's validity for model comparison.
Derived numbers: where a leaderboard publishes two of the three AA-Omniscience metrics, we do not compute the third and print it. We show a dash until the source publishes it.
Unverified community benchmarks: Reddit posts, Twitter claims, and blog articles citing benchmark numbers without methodology documentation or reproducibility information were excluded unless they could be cross-referenced against primary sources.
Vendor marketing claims: where a provider claims a specific hallucination rate but independent benchmarks show different numbers, both are presented with the discrepancy noted. This applies particularly to xAI's internal Grok benchmarks versus AA-Omniscience results.
Vectara snapshots are dated. The original ~1,000-document dataset is frozen on an archived branch last updated October 16, 2025. The refreshed 7,700-article dataset runs from November 2025, with the most recent snapshot dated October 22, 2026 (read November 7, 2026). AA-Omniscience launched in November 2025 with 6,000 questions. Artificial Analysis moved it to version 1.1 on October 27, 2026: 3,000 questions in the same six domains and 42 topics, graded by GPT-5.6 Luna, with saturated and public questions removed, new questions added and ambiguous or erroneous ones revised. It reports that models score about 2 points lower on the v1.1 Index on average, a shift that reflects the dataset change, not model regression. The cross-benchmark table and the AA-Omniscience section's tables use its v1.1 model records, read November 7, 2026, with final v1 records of October 4, 2026 for models not yet re-run, and the release notes quote launch figures alongside later records. FACTS was published December 2025. Its Kaggle board was last updated November 5, 2026, averages only the slices each model has been scored on, and scores search with a revised component. HalluHard's board was read on November 7, 2026. Its maintainers changed the judging pipeline on September 17, 2026 and expect every model's rate to move once re-run, so those figures may change. OpenAI system cards are dated per release. Vendor-internal factuality figures (xAI's model cards, OpenAI system cards) are always labeled as such and never placed in the same column as an independent benchmark. [1][124][3][5]
When two benchmarks show different numbers for the same model, this usually reflects different evaluation dates, different dataset versions, or different aspects of factuality being measured. We flag these discrepancies rather than averaging them.
Perplexity Sonar models are not listed on AA-Omniscience or Vectara. Perplexity uses underlying models (including GPT and DeepSeek variants) making hallucination attribution complex. Their SimpleQA and Search Arena results are included where available.
Vectara coverage: as of November 7, 2026, the models released since May 2026 that have a Vectara score are GPT-6 Sol, GPT-6 Astra and GPT-5.6 Sol (added September 22), Gemini 4 Argon (October 16), and Claude Opus 5.5 and DeepSeek V4.1 Flash (October 22). No Grok released since May 2026 has one. Several 2026 models, including Grok 4.7, Qwen3.8 Max, GLM-5.3 and most of the October releases, have AA-Omniscience profiles but no FACTS suite average and no HalluHard score.
AA-Omniscience configurations: Artificial Analysis lists several effort configurations per model, and third-party mirrors do not label them consistently. Every AA-Omniscience value in the cross-benchmark table comes from Artificial Analysis's own model records. A v1.1 record that names no configuration uses the default setting for that model on Artificial Analysis. A final v1 record that names none uses the setting matching the figure this page first published. The hero figures, quick findings, FAQ, model profiles, head-to-head tables and the AA-Omniscience section's tables use the v1.1 records of November 7, 2026, and the board count in the hero is Artificial Analysis's own list of 124 models on v1.1. The release notes give launch figures with later records alongside.
Claude Opus 4.6 and Sonnet 4.6 were released in February 2026. Vectara new-dataset scores exist for both (12.2% and 10.6%). AA-Omniscience figures depend on configuration, see above.
GPT-5.3 has AA-Omniscience data (52.9% accuracy for the Codex variant at xhigh) but limited coverage on other benchmarks as of this writing.
Grok internal versus independent figures disagree on direction for Grok 4.6 (better on AA-Omniscience, slightly worse on xAI's internal factuality evaluation). Both are shown, neither is averaged.
Domain-specific breakdowns for most benchmarks test general knowledge. Industry-specific hallucination data (financial, medical, legal) comes primarily from specialized studies rather than the major leaderboards.
Business cost figures come from surveys rather than verified incident databases. The EY per-organization loss average and the survey-reported hours spent fixing AI output are self-reported and should be treated as indicative of scale rather than precise accounting.
This page is updated continuously, not on a fixed schedule. Every update changes the date at the top of the page and is listed in the dated revision notes above.
As models ship: new model releases and their AA-Omniscience scores, Vectara leaderboard snapshots and system card figures.
As sources publish: FACTS leaderboard changes, new benchmarks, academic findings, court-case counts and regulatory developments (particularly EU AI Act enforcement related to accuracy requirements).
The October 2026 finding: hallucinations are getting worse in new AI models. The median AA-Omniscience hallucination rate for public models from Alibaba (Qwen), Anthropic, DeepSeek, Google DeepMind, OpenAI and xAI rose from 48.4% for the 13 released January to June 2026 to 55.2% for the 17 released July to September, on Artificial Analysis's records of October 4, 2026. Median accuracy rose too, from 47.0% to 54.5%: the newer models know more, and when they don't know, they guess more often. Lab by lab the picture is split. Of 14 successor models released since July, 7 hallucinate more than the model they replaced, 6 hallucinate less and 1 is flat. The fact sheet in the press kit lists every pair. These are AA-Omniscience v1 figures. Artificial Analysis moved the benchmark to v1.1 on October 27, 2026, with a new question set, so the v1.1 figures elsewhere on this page are not comparable with them. [2][124]
You can quote any number or chart on this page with a link to it. Credit Artificial Analysis for AA-Omniscience figures, Vectara for HHEM figures and Damien Charlotin's AI Hallucination Cases database for court figures. Charts are free to use under CC BY 4.0. Every chart has Download, Embed and Cite buttons, and embedded charts update with the page.
Cite it as: Suprmind Data Lab, AI Hallucination Rates & Benchmarks, November 7, 2026 edition, with a link to this page.
A fact sheet with the key numbers and how each one is measured, every chart on this page as a high-resolution PNG in light and dark, the method on one page, logos and a founder quote. The link appears as soon as you submit, and a copy goes to your inbox.
Your press kit is ready. We also sent the link to your inbox.
Open the press kitQuestions, interviews or a custom cut of the data: [email protected]. We handle your details under our privacy policy.
Charts
Here is every chart on this page as an image. They are free to use under CC BY 4.0 with credit to Suprmind Data Lab and a link to this page. Benchmark figures credit their original sources. Open a chart for the interactive version, then use its Download, Embed or Cite button.
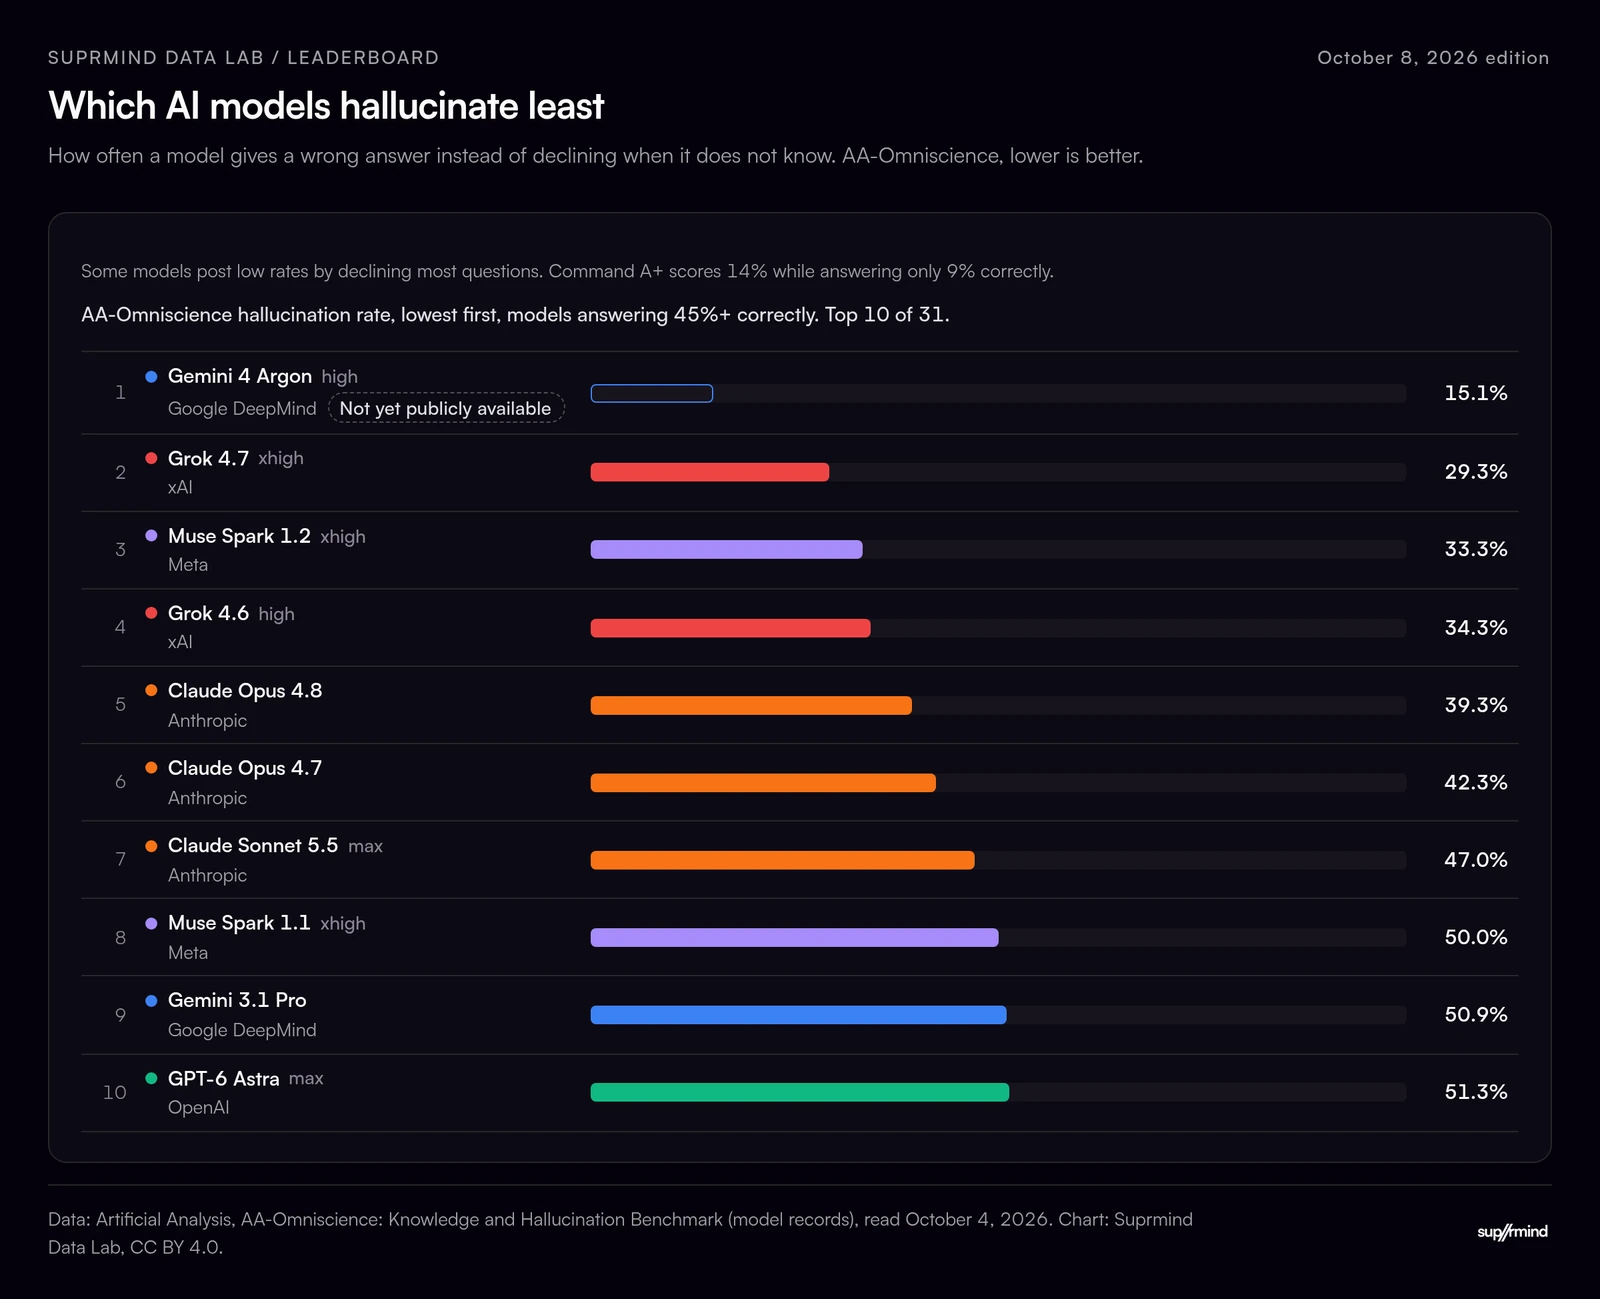 Which AI models hallucinate leastConfident but wrong: AI accuracy vs hallucination rateWhich AI models hallucinate least when summarizingHallucination rate by release dateAI hallucination scores at launch and after re-gradingCompare two AI models on every hallucination benchmarkAI hallucinations in court: decisions by dateHallucination rate with and without web searchLowest hallucination rate on Vectara’s leaderboard over time
An AI hallucination rate measures how often a model generates false or fabricated information presented as fact. The rate varies by benchmark because different tests measure different failure modes. Vectara measures how often a model adds invented facts when summarizing a document. AA-Omniscience measures how often a model gives a confident wrong answer instead of admitting it doesn't know. FACTS measures factuality across four dimensions: grounding, multimodal, parametric knowledge, and search. A model can score 0.7% on Vectara and 88% on AA-Omniscience simultaneously because the tests measure completely different things.
There is no single answer. It depends entirely on the task. On knowledge questions where the model must admit ignorance: Gemini 4 Carbon (medium) has the lowest AA-Omniscience v1.1 hallucination rate in our table, 4.2%, while answering 48.9% of questions correctly, though it is not yet publicly available. Gemini 4 Argon, public since October 13, 2026, is essentially level at 4.3% (48.3% accuracy). Among other labs' models in our table that answer at least 45% correctly, GPT-6.1 Terra is the best calibrated at 34.5% (Artificial Analysis v1.1 records, November 7, 2026). On document summarization: Ant Group's finix_s1_32b leads the Vectara original dataset at 0.6%, with Gemini-2.0-Flash at 0.7%, and the new dataset at 1.8%. On multi-dimensional factuality: GPT-6 Astra leads the models scored on all four slices of the 2026 FACTS board at 78.1 (Gemini 3 Pro's 68.8 led the December 2025 launch table, on a scale that is not directly comparable). On realistic conversational tasks: GPT-6 Astra has the lowest HalluHard rate, 27.2% with web search, ahead of Claude Opus 4.5 at 30.2%. No single model leads across all benchmarks.
Claude's hallucination rate varies significantly by model version and benchmark. On AA-Omniscience v1.1 (Artificial Analysis records, November 7, 2026), Claude Opus 5.5 posts 65.5% accuracy, a 50.3% hallucination rate and an Omniscience Index of 48.1, the highest Index of any public model in our table. Claude Fable 5.1 has the highest accuracy at 68.4% but a 70.0% hallucination rate (Index 46.3). Claude Sonnet 5.5: 51.5% accuracy, 43.3% hallucination, Index 30.5. These three are max runs with the default fallback model. Claude Haiku 5.5 (October 7, 2026): 34.7% accuracy, 34.2% hallucination, Index 12.3. Claude Opus 5: 60.9% accuracy, 59.4% hallucination, Index 37.6. Models not yet re-run on v1.1 keep their final v1 records: Claude Fable 5 65% accuracy, 63.6% hallucination, Index 43. Claude Sonnet 5 40.1%, 39.4%, Index 16.5. Claude Opus 4.8 48.8%, 39.3%, Index 28.8, the best-calibrated Claude flagship on v1. Claude Opus 4.7 48.9%, 42.3%, Index 27.3. Claude 4.1 Opus led AA-Omniscience at its November 2025 launch (36% accuracy, Index 4.8, 48% hallucination) and is no longer on the board (FACTS score 46.5). Claude Opus 4.6: 12.2% on Vectara new dataset, 47.0% accuracy and 62.8% hallucination on AA-Omniscience v1. Claude Opus 4.5: 46.6% accuracy and 61.0% hallucination on v1, FACTS score 51.3 (December 2025 launch table), 30.2% on HalluHard with web search. Claude Sonnet 4.6: 10.6% on Vectara new dataset, 48.4% hallucination on AA-Omniscience v1. On Vectara's new dataset Claude Opus 5.5 reads 9.9%, the first Claude Opus under 10%, and Claude Haiku 4.5 reads 9.8%.
GPT-6 Astra (max, released September 3, 2026): 61.6% accuracy on AA-Omniscience v1.1, a 49.8% hallucination rate and an Omniscience Index of 42.4 (Artificial Analysis records, November 7, 2026), plus 8.7% on Vectara's new dataset. It also leads the models scored on all four slices of the 2026 FACTS board (78.1) and HalluHard with web search (27.2%). Its high setting is better calibrated, at 42.5% hallucination and Index 44.6. GPT-6.1 Terra (October 26, 2026): 47.6% accuracy and 34.5% hallucination, the best calibration of any OpenAI model on v1.1. GPT-6.1 Sol: 61.8% accuracy, 51.9% hallucination, Index 42.0. GPT-6 Sol: 51.1% accuracy, 60.8% hallucination, 6.5% on Vectara new. GPT-6 Luna: 39.6% accuracy, 79.3% hallucination. The GPT-6 generation cut hallucination sharply against GPT-5.6: on v1.1, GPT-5.6 Terra reads 42.3% accuracy and 89.4% hallucination and GPT-5.6 Luna 39.1% and 92.3%. GPT-5.6 Sol, not yet re-run, read 59.4% and 92.2% in its final v1 record. Final v1 records for older models: GPT-5.5 58.0% accuracy, 89.0% hallucination. GPT-5.3 Codex 52.9% accuracy, 89.2% hallucination. GPT-5.2 (xhigh): 10.8% on Vectara new dataset (high setting), 44.3% accuracy and 81.2% hallucination on AA-Omniscience, HalluHard 38.2% with web search. GPT-5: 1.4% on Vectara original, 15.1% on new dataset (high setting), 40.3% accuracy and 82.2% hallucination on AA-Omniscience, FACTS score 61.8. GPT-4.1: 2.0% on Vectara original, 5.6% on new, FACTS score 50.5.
Grok 4.7 (September 21, 2026): 42.7% accuracy and 20.0% hallucination on AA-Omniscience v1.1, Omniscience Index 31.2 (Artificial Analysis records, November 7, 2026). Among public models in our table, only Gemini 4 Argon, Command A+ and Muse Wonder Full hallucinate less, and of those only Argon answers more questions correctly. Older Grok models keep their final v1 records. Grok 4.6 (August 12, 2026): 48.2% accuracy, 34.3% hallucination, Index 30.5, though xAI's own internal factuality evaluation scores it slightly worse than Grok 4.5 (1.7% vs 0.98%). Grok 4.5 (July 8, 2026): 51.6% accuracy and 54.1% hallucination. Grok 4.3 has two configurations: high (34.8% accuracy, 25.8% hallucination, Index 18.0) and medium (16.9% hallucination, the lowest of any Grok on v1, ahead of the older Grok 4.20 Reasoning build at 17.4%). Grok 4: 4.8% on Vectara original, over 10% on new dataset, 40.5% accuracy and 64.5% hallucination on AA-Omniscience, FACTS score 53.6. Grok 4.1 Fast Reasoning: 19.2% on Vectara new dataset, 73.4% hallucination on AA-Omniscience. Grok-3: 2.1% on Vectara original, 5.8% on new, 94% citation hallucination on CJR. The Grok 4.1 Fast Reasoning variant performs notably worse than base Grok 4, suggesting the reasoning mode adds inferences that become hallucinations on factual tasks.
Gemini 4 Carbon (October 28, 2026, not yet publicly available): 58.3% accuracy, 11.4% hallucination and an Omniscience Index of 53.5 on AA-Omniscience v1.1 at high effort, the highest Index on Artificial Analysis's board, and 4.2% hallucination at medium effort (Artificial Analysis records, November 7, 2026). Gemini 4 Argon (public since October 13, 2026): 48.3% accuracy, 4.3% hallucination and Index 46.1, the best-calibrated public model that answers at least 45% of questions correctly, plus 72.4 on the 2026 FACTS board, 75.6% on SimpleQA Verified and 12.1% on Vectara's new dataset. Gemini 3.8 Flash (September 2026): 50.5% accuracy, 55.1% hallucination, Index 23.3. Gemini 3.5 Flash-Lite: 26.5% accuracy, 26.7% hallucination, Index 6.9. Final v1 records for models not yet re-run: Gemini 3.1 Pro 54.9% accuracy, 50.9% hallucination, Index 31.9, with 10.4% on Vectara new dataset. Gemini 3.7 Flash (August 2026): 55.3% accuracy, 64.5% hallucination, Index 26.5. Gemini 3.5 Flash (May 2026): 62.2% hallucination by Artificial Analysis's independent measurement, about 31 points better than Gemini 3 Flash's 93.0%, though Google did not publish a first-party hallucination figure for it. Gemini 3 Pro: 13.6% on Vectara new, 55.8% accuracy but 91.5% hallucination on AA-Omniscience, FACTS score 68.8 (highest in the December 2025 launch table). Gemini 2.0 Flash: 0.7% on Vectara original (lowest of any frontier-lab model). On SimpleQA Verified, a test of short factual answers without tools, Gemini 3.1 Pro Preview leads the board at 77.5%. The 3.1 Pro update was significant: hallucination dropped from 91.5% to 50.9% at almost the same accuracy. Gemini 3 Pro and 3 Flash attempted nearly every question, which lifted accuracy but drove high hallucination when they hit their knowledge limits. Later Gemini models decline more often, Argon and Carbon most of all.
Perplexity Sonar Pro scored 37% citation hallucination on the Columbia Journalism Review benchmark - the lowest of any model tested, but still meaning more than one in three cited sources contained fabricated claims. ChatGPT hit 67% on the same test. Gemini hit 76%. Grok-3 reached 94%. Perplexity's failure mode is uniquely dangerous: the URLs it cites are real, but the information it attributes to those sources is sometimes fabricated. No Vectara or AA-Omniscience benchmark data exists for Perplexity Sonar models.
Different benchmarks measure fundamentally different failure modes. Vectara tests summarization faithfulness. AA-Omniscience tests knowledge calibration. FACTS tests multi-dimensional factuality across grounding, multimodal, parametric, and search tasks. CJR tests citation accuracy. A model like Grok-3 scores 2.1% on Vectara (sticks to source documents well) but 94% on CJR (fabricates nearly every citation). Both numbers are accurate. They measure different skills. The responsible approach: cross-reference at least two benchmarks measuring different things, specify the exact model version and settings, and note whether web search or reasoning mode was enabled.
No. Two independent formal impossibility results show that hallucination cannot be guaranteed away in a general-purpose language model, only reduced. It is not an engineering problem awaiting a fix. On Vectara's original summarization test, the best score fell from 3.0% in November 2023 to 0.6% in August 2025. On harder tasks, such as legal research (where even purpose-built tools err on more than 17% of queries), complex medical cases and knowledge questions that rely on the model's own training data, rates remain high across all models. The research community has shifted from eliminating hallucinations to managing hallucination risk through detection, flagging, containment, and cross-validation. Web search access is the single biggest reducer, cutting hallucination rates 73-86% when enabled.
No single number covers it, and most cost figures come from surveys. EY's October 2025 survey of 975 C-suite leaders puts the average loss from AI-related risks at US$4.4 million per affected company, a figure that covers AI risk broadly, not hallucination alone. In McKinsey's November 2025 survey (n=1,993), 51% of respondents said their organization had seen at least one negative consequence from AI, and nearly one-third reported consequences from AI inaccuracy. Zapier's January 2026 survey of 1,100 U.S. AI users found they spend about 4.5 hours a week revising or redoing AI output. In law, Damien Charlotin's database lists 2,266 court decisions involving AI-hallucinated material (last updated November 5, 2026). The largest U.S. amount ordered in a single case is US$110,204.
Yes, with attribution. Quote any number or chart with a link to this page, and credit Artificial Analysis for AA-Omniscience figures, Vectara for HHEM figures and Damien Charlotin's AI Hallucination Cases database for court figures. Charts are free to use under CC BY 4.0. Every chart has Download, Embed and Cite buttons, and embedded charts update with the page. For the fact sheet and high-resolution charts, use the press kit form or email [email protected].
Research increasingly supports this. Different AI models rarely hallucinate the same false information because they have different training data, different architectures, and different blind spots. A UAF framework study measured 8% accuracy improvement through multi-model ensemble approaches. Cross-model disagreement catches fabrications specifically because the failure modes don't overlap. When three models analyze the same question and two disagree with the third, the disagreement itself is a signal that a claim needs human review. This is the principle behind multi-AI orchestration platforms that route questions to multiple frontier models simultaneously. See how Suprmind uses this approach →
Five frontier models. One conversation. Every answer cross-checked. See why professionals who can't afford to be wrong are switching to multi-model validation.
Select Your Plan -->


