Continuously Updated
The complete AI hallucination data references. Latest numbers from Vectara, AA-Omniscience, FACTS, OpenAI system cards, and 50+ sources.
Last updated: October 7, 2026.
Latest update: 14 new models, including GPT-6 Astra, Claude Opus 5.5 and Gemini 4 Argon (not yet publicly available). The headline figures, the AA-Omniscience tables and the Vectara new-dataset, HalluHard and SimpleQA Verified figures now come from their September and October 2026 boards, and the FACTS section adds the 2026 Kaggle board. What changed
Every major AI model hallucinates. Generative AI, by the design of it, cannot be hallucination-free - but the risk can be mitigated before it reaches your decision and costs you money. Suprmind Data Lab published the Multi-Model AI Divergence Index - The AI Confidence Trap, an analysis of what happens when AI models hallucinate in the same conversation thread alongside models from other providers. See how multi-model verification works as a mitigation strategy.
This page tracks hallucination rates across seven benchmarks, covers every frontier model from GPT-6 Astra and GPT-6.1 Sol to Claude Opus 5.5 and Fable 5.1 to Gemini 4 Argon and 3.8 Flash to Grok 4.7, and presents the data without spin. The numbers don't agree with each other, and we explain why that matters more than any single leaderboard ranking.
Every number below comes from a different benchmark measuring a different aspect of hallucination. Low Vectara + high AA-Omniscience hallucination means the model is good at summarization but bad at admitting ignorance. High FACTS + low AA-Omniscience accuracy means the model is accurate with tools but attempts too many questions. No single column tells the full story. Cross-reference at least two.
Column guide:
| Model | Provider | Vectara (Old) | Vectara (New) | AA-Omni Acc | AA-Omni Hall | AA-Omni Index | FACTS | HalluHard | CJR Citation |
|---|---|---|---|---|---|---|---|---|---|
| GPT-6 Astra (max) | OpenAI | – | 8.7% | 62.6% | 51.3% | 43.4 | – | 27.2%† | – |
| GPT-6.1 Sol (max) | OpenAI | – | – | 62.1% | 54.3% | 41.5 | – | – | – |
| GPT-6 Sol (max) | OpenAI | – | 6.5% | 54.5% | 60.1% | 27.1 | – | – | – |
| GPT-6 Luna (max) | OpenAI | – | – | 43.8% | 76.7% | 0.7 | – | – | – |
| GPT-5.6 Sol (max) | OpenAI | – | 12.4% | 59.4% | 92.2% | 22.0 | – | – | – |
| GPT-5.6 Terra | OpenAI | – | – | 46.8% | 87.9% | 0.1 | – | – | – |
| GPT-5.6 Luna | OpenAI | – | – | 42.7% | 92.6% | -10.3 | – | – | – |
| GPT-5.3 Codex (xhigh) | OpenAI | – | – | 52.9% | 89.2% | 10.9 | – | – | – |
| GPT-5.5 (xhigh) | OpenAI | – | 9.3% | 58.0% | 89.0% | 20.5 | – | – | – |
| GPT-5.4 nano | OpenAI | – | 3.1% | – | – | – | – | – | – |
| GPT-5.2 (xhigh) | OpenAI | – | 10.8% | 44.3% | 81.2% | -0.9 | – | 38.2% | – |
| GPT-5 | OpenAI | 1.4% | 15.1% | 40.3% | 82.2% | -8.7 | 61.8 | – | – |
| GPT-5.1 | OpenAI | – | 12.1% | 37.7% | 51.9% | 5.4 | 49.4 | – | – |
| GPT-4.1 | OpenAI | 2.0% | 5.6% | – | – | – | 50.5 | – | – |
| o3-mini-high | OpenAI | 0.8% | – | – | – | – | – | – | – |
| Claude Fable 5.1 (max) | Anthropic | – | – | 67.2% | 72.6% | 43.5 | – | – | – |
| Claude Opus 5.5 (max) | Anthropic | – | – | 66.2% | 58.6% | 46.4 | – | – | – |
| Claude Sonnet 5.5 (max) | Anthropic | – | – | 53.9% | 47.0% | 32.3 | – | – | – |
| Claude Fable 5 (max, Opus 4.8 fallback) |
Anthropic | – | – | 65% | 63.6% | 43 | – | 38.9%† | – |
| Claude Opus 5 (max) | Anthropic | – | – | 61% | 60.8% | 37 | – | – | – |
| Claude Sonnet 5 (max) | Anthropic | – | – | 40.1% | 39.4% | 16.5 | – | – | – |
| Claude 4.1 Opus | Anthropic | 4.2% | 11.8% | – | 0% | – | 46.5 | – | – |
| Claude Opus 4.8 | Anthropic | – | – | 48.8% | 39.3% | 28.8 | – | – | – |
| Claude Opus 4.7 | Anthropic | – | 12.0% | 48.9% | 42.3% | 27.3 | – | – | – |
| Claude Opus 4.6 | Anthropic | – | 12.2% | 47.0% | 62.8% | 13.7 | – | – | – |
| Claude Opus 4.5 | Anthropic | – | 10.9% | 46.6% | 61.0% | 14.0 | 51.3 | 30.2% | – |
| Claude Sonnet 4.6 | Anthropic | – | 10.6% | 40.9% | 48.4% | 12.2 | – | – | – |
| Claude Sonnet 4.5 | Anthropic | 5.5% | 12.0% | 32.9% | 49.1% | -0.1 | 49.1 | – | – |
| Claude 3.7 Sonnet | Anthropic | 4.4% | – | – | – | – | – | – | – |
| Claude 4.5 Haiku | Anthropic | 4.5% | 9.8% | 14.4% | 25.7% | -7.6 | – | – | – |
| Gemini 4 Argon (high) (not yet publicly available) |
– | – | 49.9% | 15.1% | 42.4 | – | – | – | |
| Gemini 3.1 Pro | – | 10.4% | 54.9% | 50.9% | 31.9 | – | – | – | |
| Gemini 3.8 Flash (high) | – | – | 54.6% | 55.2% | 29.6 | – | – | – | |
| Gemini 3.7 Flash (high) | – | – | 55.3% | 64.5% | 26.5 | – | – | – | |
| Gemini 3.5 Flash (high) | – | – | 51.4% | 62.2% | 21.2 | – | – | – | |
| Gemini 3.5 Flash-Lite | – | – | 29.5% | 34.4% | 5.2 | – | – | – | |
| Gemini 3 Pro | – | 13.6% | 55.8% | 91.5% | 15.3 | 68.8 | – | – | |
| Gemini 3 Flash | – | 13.5% | 53.4% | 93.0% | 10.1 | – | – | – | |
| Gemini 2.5 Pro | – | 7.0% | – | – | – | 62.1 | – | – | |
| Gemini 2.0 Flash | 0.7% | – | – | – | – | – | – | – | |
| Grok 4.7 (xhigh) | xAI | – | – | 47.4% | 29.3% | 32.0 | – | – | – |
| Grok 4.6 (high) | xAI | – | – | 48.2% | 34.3% | 30.5 | – | – | – |
| Grok 4.5 (high) | xAI | – | – | 51.6% | 54.1% | 25.3 | – | – | – |
| Grok 4.3 (high) | xAI | – | – | 34.8% | 25.8% | 18.0 | – | – | – |
| Grok 4.3 (medium) | xAI | – | – | 28.8% | 16.9% | 16.7 | – | – | – |
| Grok 4.20 (Reasoning) | xAI | – | – | 27.5% | 17.4% | 14.8 | – | – | – |
| Grok 4.1 Fast | xAI | – | 19.2% | 25.1% | 73.4% | -29.9 | – | – | – |
| Grok 4 | xAI | 4.8% | >10% | 40.5% | 64.5% | 2.1 | 53.6 | – | – |
| Grok-3 | xAI | 2.1% | 5.8% | – | – | – | – | – | 94% |
| Perplexity Sonar Pro | Perplexity | – | – | – | – | – | – | – | 37% |
| DeepSeek V4 Pro 0813 (GA) | DeepSeek | – | – | 49.1% | 94.8% | 0.8 | – | – | – |
| DeepSeek V4 Pro (preview) | DeepSeek | – | 8.6% | 43.0% | 94.1% | -10.7 | – | – | – |
| DeepSeek V4.1 Flash (max) | DeepSeek | – | – | 46.4% | 96.5% | -5.3 | – | – | – |
| DeepSeek V4 Flash (0420) | DeepSeek | – | – | 36.8% | 96.1% | -23.9 | – | – | – |
| DeepSeek-V3 | DeepSeek | 3.9% | 6.1% | – | – | – | – | – | – |
| DeepSeek-R1 | DeepSeek | 14.3% | 11.3% | 30.5% | 83.4% | -27.4 | – | – | – |
| Kimi K3 (max) | Moonshot | – | – | 47.6% | 53.2% | 19.7 | – | – | – |
| GLM-5.3 (max) | Z.ai | – | – | 33.9% | 29.6% | 14.3 | – | – | – |
| Command A+ | Cohere | – | – | 9% | 14% | -4 | – | – | – |
| Qwen3.8 Max (0902) | Alibaba | – | – | 31.7% | 28.8% | 12.0 | – | – | – |
| Qwen3.8 Max Preview | Alibaba | – | – | 31.9% | 41.7% | 3.4 | – | – | – |
| Qwen3.7 Max | Alibaba | – | – | 31.1% | 25.6% | 13.5 | – | – | – |
| Muse Spark 1.3 (max) | Meta | – | – | 43.6% | 32.9% | 25.0 | – | – | – |
| Muse Spark 1.2 (xhigh) | Meta | – | – | 45.4% | 33.3% | 27.2 | – | – | – |
| Muse Spark 1.1 (xhigh) | Meta | – | – | 52.1% | 50.0% | 28.1 | – | – | – |
| Llama 4 Maverick | Meta | 4.6% | 8.2% | 24.9% | 88.9% | -41.9 | – | – | – |
Sources: Vectara HHEM Leaderboard (archived original dataset, last updated October 16, 2025, and the new 7,700-article dataset, snapshot September 22, 2026, which added GPT-6 Astra, GPT-6 Sol and GPT-5.6 Sol) [1][100], Artificial Analysis AA-Omniscience [2][64][72][88], Google DeepMind FACTS Suite, December 2025 launch table (the 2026 Kaggle board scores search with a revised component, FACTS Search V2, and is not directly comparable) [3], HalluHard leaderboard with web search, read October 7, 2026 († = HalluHard's updated question set) [5], Columbia Journalism Review (March 2025) [6]. Every AA-Omniscience value in the table was read from Artificial Analysis's own model records on October 4, 2026. That includes rows first published earlier, which were updated wherever AA has since re-scored them (for example Gemini 3 Pro hallucination 88% to 91.5%, GPT-5.1 81% to 51.9%, Claude Opus 4.7 36% to 42.3%). Every row was checked for internal consistency (Index equals correct minus incorrect). Where a row names no configuration, the AA configuration matching the originally published figure is used: GPT-5 and GPT-5.1 high, Claude Opus 4.7, Opus 4.6 and Sonnet 4.6 max, Claude Opus 4.5 and Sonnet 4.5 reasoning, Claude 4.5 Haiku non-reasoning, Gemini 3 Flash reasoning, Grok 4.20 0309 v2 and Grok 4.1 Fast reasoning, DeepSeek R1 0528. The Claude Fable 5.1, Opus 5.5 and Sonnet 5.5 rows are AA's max-with-fallback runs. GPT-6 Astra is shown at max. Its high configuration is better calibrated, at 61.1% / 44.8% / 43.7. Gemini 4 Argon is not yet publicly available: Google announced it on September 30, 2026 and is giving access to an initial group of cyber defenders first. Claude 4.1 Opus's 0% is the November 2025 launch snapshot, achieved by refusing uncertain questions, and AA no longer lists the model. Grok 4.3 is shown in two configurations. Medium attempts fewer questions, which lowers both accuracy and hallucination. DeepSeek V4 Pro is shown twice because the April preview (0424 build) and the August 13 GA build are different checkpoints. Other benchmarks may test a different setting from the AA configuration named in a row: GPT-5.2's Vectara figure is its high setting, the DeepSeek-R1 row's Vectara figures are the original R1 release while its AA figures are the 0528 build, and HalluHard ran GPT-6 Astra at medium thinking and Claude Fable 5 with adaptive thinking. Corrections, October 7, 2026: o3-mini-high and Gemini 2.0 Flash have never been on Vectara's new-dataset board, so their Vectara (New) cells now show a dash, and the FACTS cells for o3-mini-high, GPT-5.2 and Grok 4.1 Fast are now blank because the figures shown before belonged to o3, GPT-5 and Grok 4 Fast. GPT-5's Vectara (New) cell now shows its board figure, 15.1%. Four blank Vectara cells were filled from the boards: Claude 4.1 Opus 4.2%, Claude Sonnet 4.5 5.5% and Claude 4.5 Haiku 4.5% on the original dataset, GPT-5.1 12.1% on the new one. Grok 4's ">10%" comes from Vectara's November 2025 launch post, and the model itself is not on the board. Grok 4.1 Fast's Vectara figure was corrected on October 4, 2026 from 20.2% (Grok 4 Fast's score) to 19.2%. In the Vectara, FACTS and HalluHard columns, dashes mean no figure on the dataset, snapshot or setting that column uses (FACTS: the December 2025 launch table. HalluHard: with web search). In the AA-Omniscience columns, a dash means this table has no AA figure for that model.
Best knowledge reliability index: Claude Opus 5.5 - index 46.4 on AA-Omniscience in the October 2026 update, ahead of Claude Fable 5.1 (43.5) and GPT-6 Astra (43.4), which are effectively tied. Its edge over Fable 5.1, which is a point more accurate, comes from fewer wrong answers. Calibration is still weak: when Opus 5.5 can't answer correctly, it gives a wrong answer instead of declining 58.6% of the time. The Fable 5.1, Opus 5.5 and Sonnet 5.5 rows are Artificial Analysis's max runs with a fallback model.
Best index without a fallback model: GPT-6 Astra - 43.4 at max, with 62.6% accuracy and 51.3% hallucination. Its high setting scores 43.7 and is better calibrated, at 44.8% hallucination.
Highest accuracy: Claude Fable 5.1 - 67.2% on AA-Omniscience, the best in this table. It also has the highest hallucination rate of any 2026 Claude, 72.6%, up from Fable 5's 63.6%.
Lowest hallucination rate (knowledge tasks): Claude 4.1 Opus - 0% on AA-Omniscience in the November 2025 launch snapshot (model declines to answer when uncertain). Artificial Analysis no longer lists the model. On the August 2026 board the lowest raw rate was MiniCPM5-1B at 1%, a 1B-parameter model that refuses most questions.
Lowest hallucination among capable open-weight models: Command A+ (Cohere) - 14% on AA-Omniscience, achieved by refusing most questions it can't verify (9% accuracy). Among other abstention-first models, Qwen3.7 Max sits at 25.6% and GLM-5.3 at 29.6%.
Biggest single improvement: GPT-6 Astra - 51.3% hallucination against 92.2% for its direct predecessor, GPT-5.6 Sol, a 40.9-point drop, while answering more questions correctly (62.6% against 59.4%). Gemini 3.1 Pro's step over Gemini 3 Pro was almost as large: 91.5% to 50.9%, for less than one point of accuracy.
Best calibration among high-accuracy models: Gemini 4 Argon - 15.1% hallucination at 49.9% accuracy (not yet publicly available). Among public models that answer at least 45% of questions correctly, Grok 4.7 leads at 29.3% (47.4% accuracy, xhigh), down from Grok 4.6's 34.3% (high).
Lowest hallucination among public models answering at least 25% correctly: Grok 4.3 medium - 16.9% on AA-Omniscience, just ahead of the older Grok 4.20 Reasoning build (17.4%). Both attempt fewer questions, so accuracy stays under 30%.
Largest hallucination rate (knowledge questions): DeepSeek V4.1 Flash - 96.5% on AA-Omniscience in the October 2026 update, just above DeepSeek V4 Flash (96.1%). DeepSeek's flagship, V4 Pro 0813, sits at 94.8%. Among flagships from OpenAI, Anthropic, Google and xAI, GPT-5.6 Sol still holds the highest rate at 92.2%.
Biggest variable across all models: Web search access - reduces hallucination 73-86% when enabled (OpenAI FActScore evaluations of its own models)
Best citation accuracy: Perplexity Sonar Pro - 37% hallucination on CJR (lowest, but still high)
Lowest hallucination rate (summarization): Ant Group finix_s1_32b - 0.6% on Vectara's original dataset (Gemini-2.0-Flash: 0.7%) and 1.8% on the new 7,700-article dataset, where GPT-5.4 nano is the best frontier-lab model at 3.1%
Best in realistic conversations: GPT-6 Astra - 27.2% on HalluHard with web search, on its updated question set, ahead of Claude Opus 4.5 at 30.2%
Highest factuality score (multi-dimensional): GPT-6 Astra - 75.7 on the 2026 FACTS board on Kaggle (September 28, 2026). Gemini 3 Pro led the December 2025 launch table at 68.8, on a scale that is not directly comparable
Best short-answer factuality without tools: Gemini 3.1 Pro Preview - 77.5% on SimpleQA Verified (Kaggle board, October 5, 2026), ahead of GPT-6 Astra at 75.8%
The October 2026 pattern: the labs split. OpenAI improved on both counts: GPT-6 Astra answers more questions correctly than GPT-5.6 Sol (62.6% against 59.4%) and hallucinates far less (51.3% against 92.2%). Google and xAI cut hallucination and gave up some accuracy to do it: Gemini 4 Argon reads 15.1% against 50.9% for Gemini 3.1 Pro, and Grok 4.7 29.3% against Grok 4.6's 34.3%. Anthropic's newest models know more and mostly guess more: Claude Fable 5.1 rose to 72.6% (Fable 5: 63.6%) and Sonnet 5.5 to 47.0% (Sonnet 5: 39.4%), while Opus 5.5 held close to Opus 5 (58.6% against 60.8%). More capable still does not mean better calibrated.
Application
These benchmarks show which models perform better under specific conditions, but no single model is flawless and every leaderboard tests something slightly different. If you're looking for the lowest hallucination AI workflow for real high-stakes work, Suprmind runs your question through five frontier AI models who read each other’s responses, argue, challenge, and build on each other – so when one model hallucinate, the others catch it before it reaches your decision.
See how the multi-AI workflow worksListen to the full research (51 min)
An AI hallucination is when an AI model makes something up and presents it as fact. It doesn't flag uncertainty. It doesn't say "I'm guessing." It delivers fabricated statistics, invented legal cases, or nonexistent research papers with the same confidence it uses for basic arithmetic. The output reads perfectly. That's what makes it dangerous.
Hallucination refers to generated output not grounded in the provided input or factual reality. Two types:
Intrinsic hallucination (faithfulness failure): The model contradicts information it was explicitly given. Hand it a contract and ask for a summary — it adds clauses that don't exist in the original document.
Extrinsic hallucination (factuality failure): The model generates information that can't be verified against any known source. It invents facts, statistics, citations, or events from scratch. No source material was contradicted because no source material was consulted.
Cash and Oppenheimer put numbers on this in Memory & Cognition (July 2025). Both humans and LLMs began overconfident about how they would perform on a 20-item identification task. After answering, humans revised their self-assessments downward — the models revised theirs upward. Gemini predicted it would score 10.03 out of 20, actually scored 0.93, then estimated in retrospect that it had scored 14.40. The models simply could not tell how badly they had done. [82]
An AI sounds the same when it is right and when it is wrong.
Large language models are prediction engines, not knowledge bases. They generate text by predicting the most statistically likely next token based on patterns in training data. They don't understand truth. They predict plausibility.
When the model hits a gap in its training data or faces an ambiguous query, it fills the gap with something plausible rather than admitting it doesn't know. Next-token prediction supplies no "I'm not sure" on its own - it just picks the next most probable word. Post-training can teach a model to abstain, and how well that lesson took is exactly what AA-Omniscience measures below.
And this isn't a bug that will be fixed in the next update. Two independent research teams have published formal impossibility results showing that hallucination cannot be engineered out of a general-purpose language model, only managed. Not an engineering shortcoming waiting on the next release. A structural property of the approach. (More on this, including what the proofs do and do not claim, in the Mathematical Impossibility section below.) [20][21]
Before looking at any hallucination data, you need to understand why different benchmarks give wildly different scores for the same model.
Grok-3 scores 2.1% on the Vectara summarization benchmark. Excellent. That same model scores 94% on the Columbia Journalism Review citation accuracy test. Catastrophic. Same model, same time period, opposite conclusions.
This isn't an error. It's measuring different things. And treating any single benchmark as "the hallucination rate" will mislead you.
The matrix below summarizes what each benchmark actually tests. Click any benchmark name to jump to its dedicated section.
| Benchmark | What It Measures | Good For | Not Good For |
|---|---|---|---|
| Vectara HHEM | Summarization faithfulness — does the model add unsupported facts when summarizing source documents? | RAG pipelines, document Q&A, knowledge base search | Open-ended knowledge questions |
| AA-Omniscience | When the model doesn't know an answer, does it admit it or fabricate one? The Omniscience Index penalizes wrong answers and rewards refusal. | High-stakes advisory work — legal, medical, financial | Summarization or grounded tasks |
| FACTS | Multi-dimensional factuality across grounding, multimodal, parametric, and search. Each dimension scored separately. | Comparing where models are strong and weak across task types | Producing a single hallucination rate number |
| SimpleQA / PersonQA | Short factual questions and accuracy about real people. SimpleQA Verified is Google DeepMind's cleaned-up 1,000-question version of SimpleQA. Newer reasoning models often perform worse than predecessors here. | Quick factuality testing on straightforward questions | Complex, multi-step, or domain-specific queries |
| HalluHard | Hallucination rate in realistic conversational settings. Even the best entry, GPT-6 Astra with web search, still hallucinates 27.2% of the time. | Predicting real-world rates in production chat applications | Controlled, reproducible model comparisons |
| CJR Citation | Whether AI models correctly attribute information to cited sources. Failure mode: real URLs with fabricated content attached. | Research, journalism, any source-attribution task | General knowledge or summarization evaluation |
| BullshitBench v2 | Whether the model pushes back on a nonsense premise or confidently builds on it. 100 prompts across software, finance, legal, medical and physics, scored by a three-model judge panel. Measures sycophancy, not recall. | Advisory work where the user's own premise may be wrong | Measuring factual knowledge or grounded accuracy |
Sources: Vectara HHEM [1], AA-Omniscience [2], FACTS [3], SimpleQA/PersonQA [4], SimpleQA Verified [101], HalluHard [5], CJR Citation Study [6], BullshitBench v2 [94]
TruthfulQA was once the gold standard. It's now partially saturated — models have been trained on its questions. Worse, researchers showed a simple decision tree can score 79.6% on TruthfulQA multiple choice without even seeing the question being asked, just by exploiting structural patterns in answer formatting. A 2025-2026 TruthfulQA score tells you little about a frontier model on its own. [29]
HaluEval has a similar problem. A length-based classifier achieves 93.3% accuracy on HaluEval QA simply by flagging answers longer than 27 characters as hallucinated. The benchmark measures answer length more than it measures truthfulness. [30]
Both remain useful for tracking a model family over time. Neither is sufficient as a hallucination rate for a 2026 model, which is why this page does not use them in its tables.
No single benchmark gives you "the hallucination rate" of any model. If someone quotes one number, they're either simplifying for convenience or cherry-picking for marketing.
The responsible approach: cross-reference at least two benchmarks that measure different things (one grounded task like Vectara, one open-ended knowledge task like AA-Omniscience), specify the exact model version and calling conditions, and note whether tool access was enabled. The sections that follow do exactly that.
Vectara's leaderboard is the most cited hallucination benchmark in the industry. It measures summarization faithfulness — given a source document, does the model's summary stick to what's actually in the document, or does it add unsupported facts? This makes it a direct proxy for how AI behaves in RAG pipelines, enterprise search tools, and document analysis workflows. The leaderboard exists in two versions, and the gap between them tells an important story. [1]
This is the dataset most articles reference when they quote hallucination rates. The documents are relatively short and the summarization tasks are straightforward.
| Model | Provider | Hallucination Rate | Factual Consistency |
|---|---|---|---|
| antgroup/finix_s1_32b | Ant Group | 0.6% | 99.4% |
| Gemini-2.0-Flash-001 | 0.7% | 99.3% | |
| Gemini-2.0-Pro-Exp | 0.8% | 99.2% | |
| o3-mini-high | OpenAI | 0.8% | 99.2% |
| Gemini-2.5-Pro-Exp | 1.1% | 98.9% | |
| GPT-4.5-Preview | OpenAI | 1.2% | 98.8% |
| Gemini-2.5-Flash-Preview | 1.3% | 98.7% | |
| o1-mini | OpenAI | 1.4% | 98.6% |
| GPT-5 (high) | OpenAI | 1.4% | 98.6% |
| GPT-4o | OpenAI | 1.5% | 98.5% |
| GPT-4o-mini | OpenAI | 1.7% | 98.3% |
| GPT-4-Turbo | OpenAI | 1.7% | 98.3% |
| GPT-4 | OpenAI | 1.8% | 98.2% |
| Grok-2 | xAI | 1.9% | 98.1% |
| GPT-4.1 | OpenAI | 2.0% | 98.0% |
| Grok-3-Beta | xAI | 2.1% | 97.8% |
| Qwen3-14B | Qwen/Alibaba | 2.2% | 97.8% |
| DeepSeek-V3 | DeepSeek | 3.9% | 96.1% |
| Claude-3.7-Sonnet | Anthropic | 4.4% | 95.6% |
| Claude-3.5-Sonnet | Anthropic | 4.6% | 95.4% |
| o4-mini | OpenAI | 4.6% | 95.4% |
| Llama-4-Maverick | Meta | 4.6% | 95.4% |
| DeepSeek-V3.2-Exp | DeepSeek | 4.6% | 95.4% |
| Grok-4 | xAI | 4.8% | 95.2% |
| Claude-3.5-Haiku | Anthropic | 4.9% | 95.1% |
| Claude-3-Opus | Anthropic | 10.1% | 89.9% |
| DeepSeek-R1 | DeepSeek | 14.3% | 85.7% |
Source: Vectara HHEM Leaderboard, original ~1,000-document dataset, archived GitHub branch (hhem-2.3-old-dataset, last updated October 16, 2025). Ant Group's finix_s1_32b leads this archived table at 0.6%. Rows checked against the archived branch on August 27, 2026: GPT-5.4 nano, GPT-5.4 mini and Gemma-4-26B were never evaluated on this dataset and have moved to the new-dataset table below, where they belong. [1][100]
On this dataset, the numbers look encouraging. Ant Group's finix_s1_32b and two Gemini 2.0 models take the top three spots, with OpenAI's o3-mini-high tied for third. OpenAI's GPT models in this table sit between 1.2% and 2.0%. Every model in this table stays under 15%, though the full archived board runs up to 29.9% for older small models.
Correction, August 2026: an earlier version of this page listed finix_s1_32b at 1.8% on the original dataset. That is its rate on the new 7,700-article dataset, where it also leads. On the archived original dataset it scores 0.6%, one tenth of a point below Gemini-2.0-Flash. It is the first time a Chinese enterprise model has topped either Vectara table. Vectara froze the original dataset in October 2025, so no model released after that date will appear here. [100]
But this dataset is easy. The documents are short, the summarization tasks are clean, and the real world is neither.
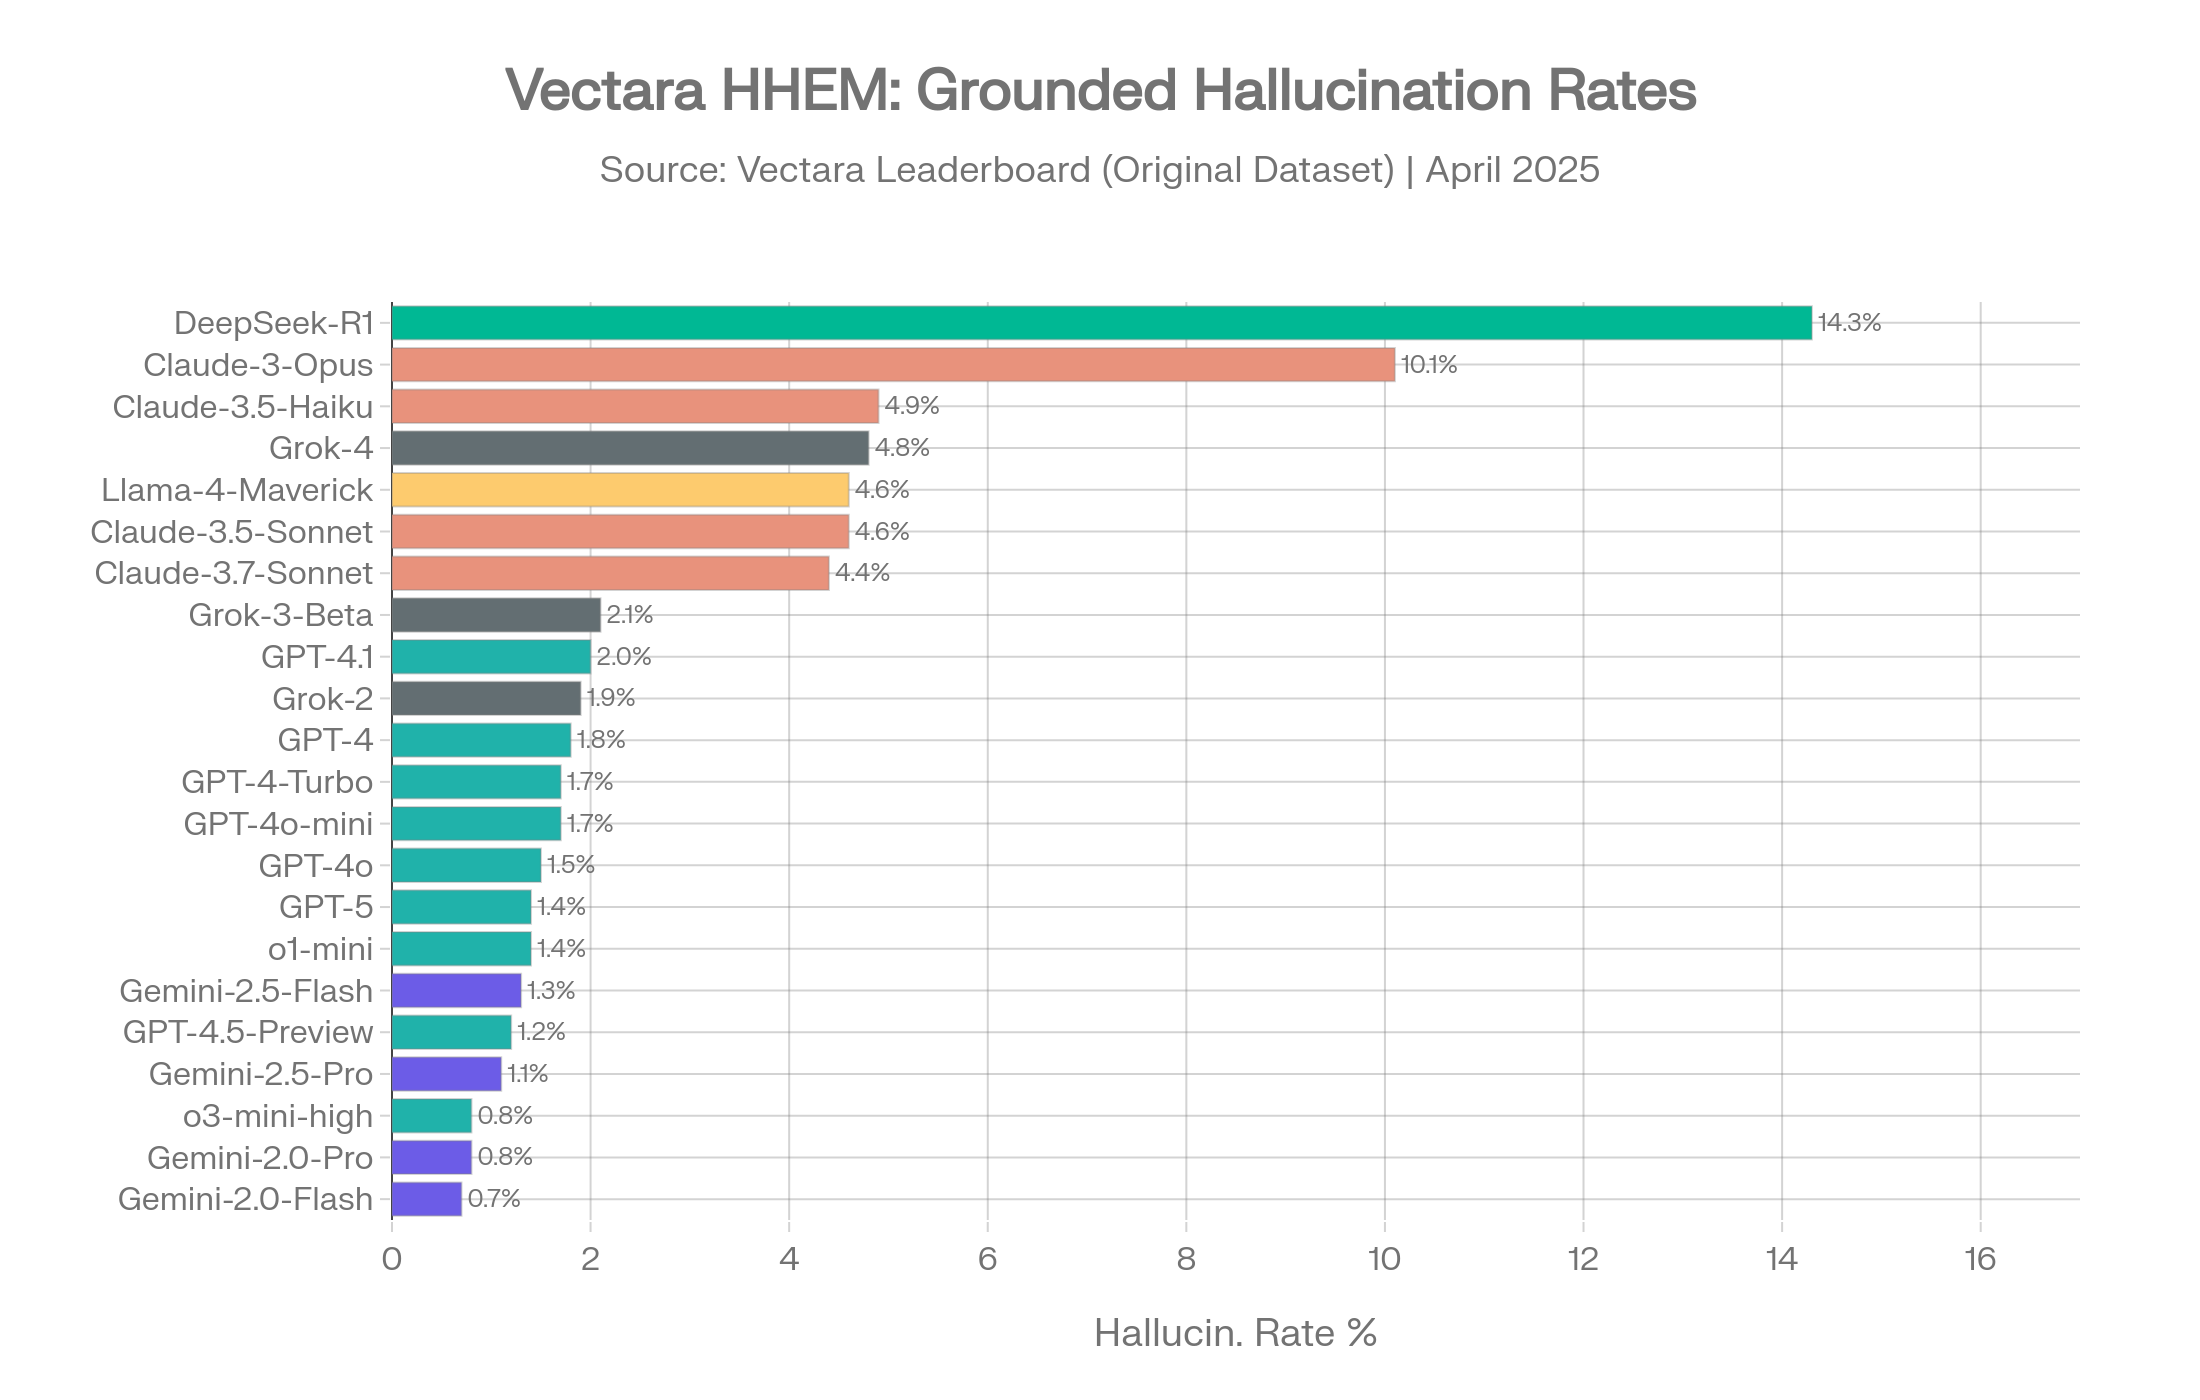
Vectara HHEM Leaderboard: Full model ranking with provider color-coding on original dataset. Source: Vectara [1]
Vectara launched a refreshed benchmark in late 2025 with longer documents (up to 32K tokens) spanning law, medicine, finance, technology, and education. This version better reflects what enterprise AI systems actually face.
Rates rose for most models:
| Model | Provider | Hallucination Rate |
|---|---|---|
| finix_s1_32b | Ant Group | 1.8% |
| GPT-5.4 nano | OpenAI | 3.1% |
| Gemini 2.5 Flash-Lite | 3.3% | |
| Mistral Large (2411) | Mistral | 4.5% |
| Gemma 4 26B | 5.2% | |
| DeepSeek V3.2-Exp | DeepSeek | 5.3% |
| GPT-5.4 mini | OpenAI | 5.5% |
| GPT-4.1 | OpenAI | 5.6% |
| Grok-3 | xAI | 5.8% |
| DeepSeek-V3 | DeepSeek | 6.1% |
| GPT-6 Sol | OpenAI | 6.5% |
| Command R+ | Cohere | 6.9% |
| GPT-5.4 | OpenAI | 7.0% |
| Gemini 2.5 Pro | 7.0% | |
| Llama 4 Scout | Meta | 7.7% |
| GPT-5.2 (low) | OpenAI | 8.4% |
| DeepSeek V4 Pro | DeepSeek | 8.6% |
| GPT-6 Astra | OpenAI | 8.7% |
| GPT-5.5 | OpenAI | 9.3% |
| Claude Haiku 4.5 | Anthropic | 9.8% |
| Gemini 3.1 Pro Preview | 10.4% | |
| Claude Sonnet 4.6 | Anthropic | 10.6% |
| GPT-5.2 (high) | OpenAI | 10.8% |
| Claude Opus 4.5 | Anthropic | 10.9% |
| DeepSeek-R1 | DeepSeek | 11.3% |
| Claude Opus 4.1 | Anthropic | 11.8% |
| Claude Opus 4.7 | Anthropic | 12.0% |
| Claude Sonnet 4.5 | Anthropic | 12.0% |
| Claude Opus 4.6 | Anthropic | 12.2% |
| GPT-5.6 Sol | OpenAI | 12.4% |
| Gemini 3 Flash Preview | 13.5% | |
| Gemini 3 Pro Preview | 13.6% | |
| GPT-5 (high) | OpenAI | 15.1% |
| Grok 4.1 Fast (reasoning) | xAI | 19.2% |
| Grok 4 Fast (reasoning) | xAI | 20.2% |
Source: Vectara Hallucination Leaderboard, new 7,700-article dataset, last updated September 22, 2026 and read October 7, 2026 [1]. The table shows 35 of the 108 models on the board. Ant Group's finix_s1_32b leads at 1.8%, and GPT-5.4 nano (3.1%) is the best frontier-lab entry. DeepSeek-R1 scores 11.3% here. An earlier version of this table listed it at 7.7%, which is the original-dataset score of its 0528 build. GPT-5 is shown at its high setting, which scored 19.2% when the board launched in November 2025 and 15.1% now.
Vectara's latest update added three OpenAI models: GPT-6 Sol at 6.5%, GPT-6 Astra at 8.7% and GPT-5.6 Sol at 12.4%. Both GPT-6 models score better than GPT-5.6 Sol, in line with their lower hallucination rates on AA-Omniscience. No Claude, Gemini or Grok model released since May 2026 has a score yet. The board's latest Claude is Opus 4.7 (12.0%), its latest Gemini Pro is 3.1 Pro Preview (10.4%) and its latest Grok is Grok 4.1 Fast (19.2% with reasoning). Earlier snapshots are covered in our February 2026 research report. [1]
When Vectara launched the new dataset in November 2025, the thinking models it named, including GPT-5, Claude Sonnet 4.5 and Grok-4, all came in above 10%, and Gemini-3-Pro read 13.6%. Grok-4-fast-reasoning reads 20.2% on the current board. Several of OpenAI's newer models have since come in under 10% on the same dataset: GPT-6 Sol at 6.5%, GPT-5.4 at 7.0%, GPT-6 Astra at 8.7% and GPT-5.5 at 9.3%, though GPT-5.6 Sol reads 12.4%. The latest Claude and Gemini Pro entries still exceed 10%, at 12.0% for Claude Opus 4.7 and 10.4% for Gemini 3.1 Pro Preview. [102][1][48][49]
The hypothesis is straightforward. Reasoning models invest computational effort into "thinking through" answers. During summarization, this thinking leads them to add inferences, draw connections, and generate insights that go beyond what's in the source document. That's helpful for analysis. It's hallucination on a summarization benchmark.
This creates a critical decision for enterprise teams: reasoning mode helps on open-ended tasks and hurts on grounded tasks. Knowing when to enable it and when to turn it off is not optional.
AA-Omniscience asks a fundamentally different question than Vectara. Instead of "can you summarize without adding stuff," it asks "when you don't know something, do you admit it or make something up?" [2]
The benchmark covers 6,000 questions across 42 topics in six domains. The Omniscience Index (scale: -100 to +100) penalizes wrong answers and doesn't penalize refusal. This makes it the only major benchmark that explicitly rewards models for knowing their own limits.
How to read the three numbers together. Accuracy is the share of questions answered correctly. Hallucination rate is the share of non-correct responses that were wrong answers rather than refusals. The Index is roughly correct minus incorrect. So a model can post the highest accuracy while still fabricating most of the time it doesn't know. That is Claude Fable 5.1's profile: 67.2% accuracy and a 72.6% hallucination rate. On BenchLM's Artificial Analysis-synced board for October 6, 2026, 61 of 202 models have a positive Index. The other 141 give more wrong answers than right ones. [2][88]
Snapshot policy. Artificial Analysis re-runs models and adds effort configurations over time, so figures drift after launch, usually by a point or two and sometimes by much more. Both tables below were read from Artificial Analysis's own model records on October 4, 2026, including rows this page first published earlier. The one exception is Claude 4.1 Opus's November 2025 launch snapshot. The release notes further down quote each model's launch figures, with the current record alongside where it has moved. [2]
| Model | Provider | Accuracy | Hallucination Rate | Omniscience Index |
|---|---|---|---|---|
| Claude Fable 5.1 (max) | Anthropic | 67.2% | 72.6% | 43.5 |
| Claude Opus 5.5 (max) | Anthropic | 66.2% | 58.6% | 46.4 |
| Claude Fable 5 (max, Opus 4.8 fallback) | Anthropic | 65% | 63.6% | 43 |
| GPT-6 Astra (max) | OpenAI | 62.6% | 51.3% | 43.4 |
| GPT-6.1 Sol (max) | OpenAI | 62.1% | 54.3% | 41.5 |
| Claude Opus 5 (max) | Anthropic | 61% | 60.8% | 37 |
| GPT-5.6 Sol (max) | OpenAI | 59.4% | 92.2% | 22.0 |
| GPT-5.5 (xhigh) | OpenAI | 58.0% | 89.0% | 20.5 |
| Gemini 3 Pro | 55.8% | 91.5% | 15.3 | |
| Gemini 3.7 Flash (high) | 55.3% | 64.5% | 26.5 | |
| Gemini 3.1 Pro | 54.9% | 50.9% | 31.9 | |
| Gemini 3.8 Flash (high) | 54.6% | 55.2% | 29.6 | |
| GPT-6 Sol (max) | OpenAI | 54.5% | 60.1% | 27.1 |
| Claude Sonnet 5.5 (max) | Anthropic | 53.9% | 47.0% | 32.3 |
| Gemini 3 Flash | 53.4% | 93.0% | 10.1 | |
| GPT-5.3 Codex (xhigh) | OpenAI | 52.9% | 89.2% | 10.9 |
| Muse Spark 1.1 (xhigh) | Meta | 52.1% | 50.0% | 28.1 |
| Grok 4.5 (high) | xAI | 51.6% | 54.1% | 25.3 |
| Gemini 3.5 Flash (high) | 51.4% | 62.2% | 21.2 | |
| Gemini 4 Argon (high, not yet publicly available) | 49.9% | 15.1% | 42.4 | |
| DeepSeek V4 Pro 0813 (GA) | DeepSeek | 49.1% | 94.8% | 0.8 |
| Claude Opus 4.7 | Anthropic | 48.9% | 42.3% | 27.3 |
| Claude Opus 4.8 | Anthropic | 48.8% | 39.3% | 28.8 |
| Grok 4.6 (high) | xAI | 48.2% | 34.3% | 30.5 |
| Kimi K3 (max) | Moonshot | 47.6% | 53.2% | 19.7 |
| Grok 4.7 (xhigh) | xAI | 47.4% | 29.3% | 32.0 |
| Claude Opus 4.6 | Anthropic | 47.0% | 62.8% | 13.7 |
| GPT-5.6 Terra | OpenAI | 46.8% | 87.9% | 0.1 |
| Claude Opus 4.5 | Anthropic | 46.6% | 61.0% | 14.0 |
| DeepSeek V4.1 Flash (max) | DeepSeek | 46.4% | 96.5% | -5.3 |
Source: Artificial Analysis AA-Omniscience model records, read October 4, 2026 [2][88]. Every row was checked for internal consistency (Index equals correct minus incorrect). Where a row names no configuration, it uses the Artificial Analysis configuration that matches the figure this page first published, as in the cross-benchmark table. The Claude Fable 5.1, Opus 5.5 and Sonnet 5.5 rows are max runs with a fallback model. GPT-6 Astra's high setting reads 61.1% accuracy, 44.8% hallucination and Index 43.7. Gemini 4 Argon is not yet publicly available. Models outside the top 30 by accuracy appear in the full hallucination ranking below and in the cross-benchmark table at the top of the page.
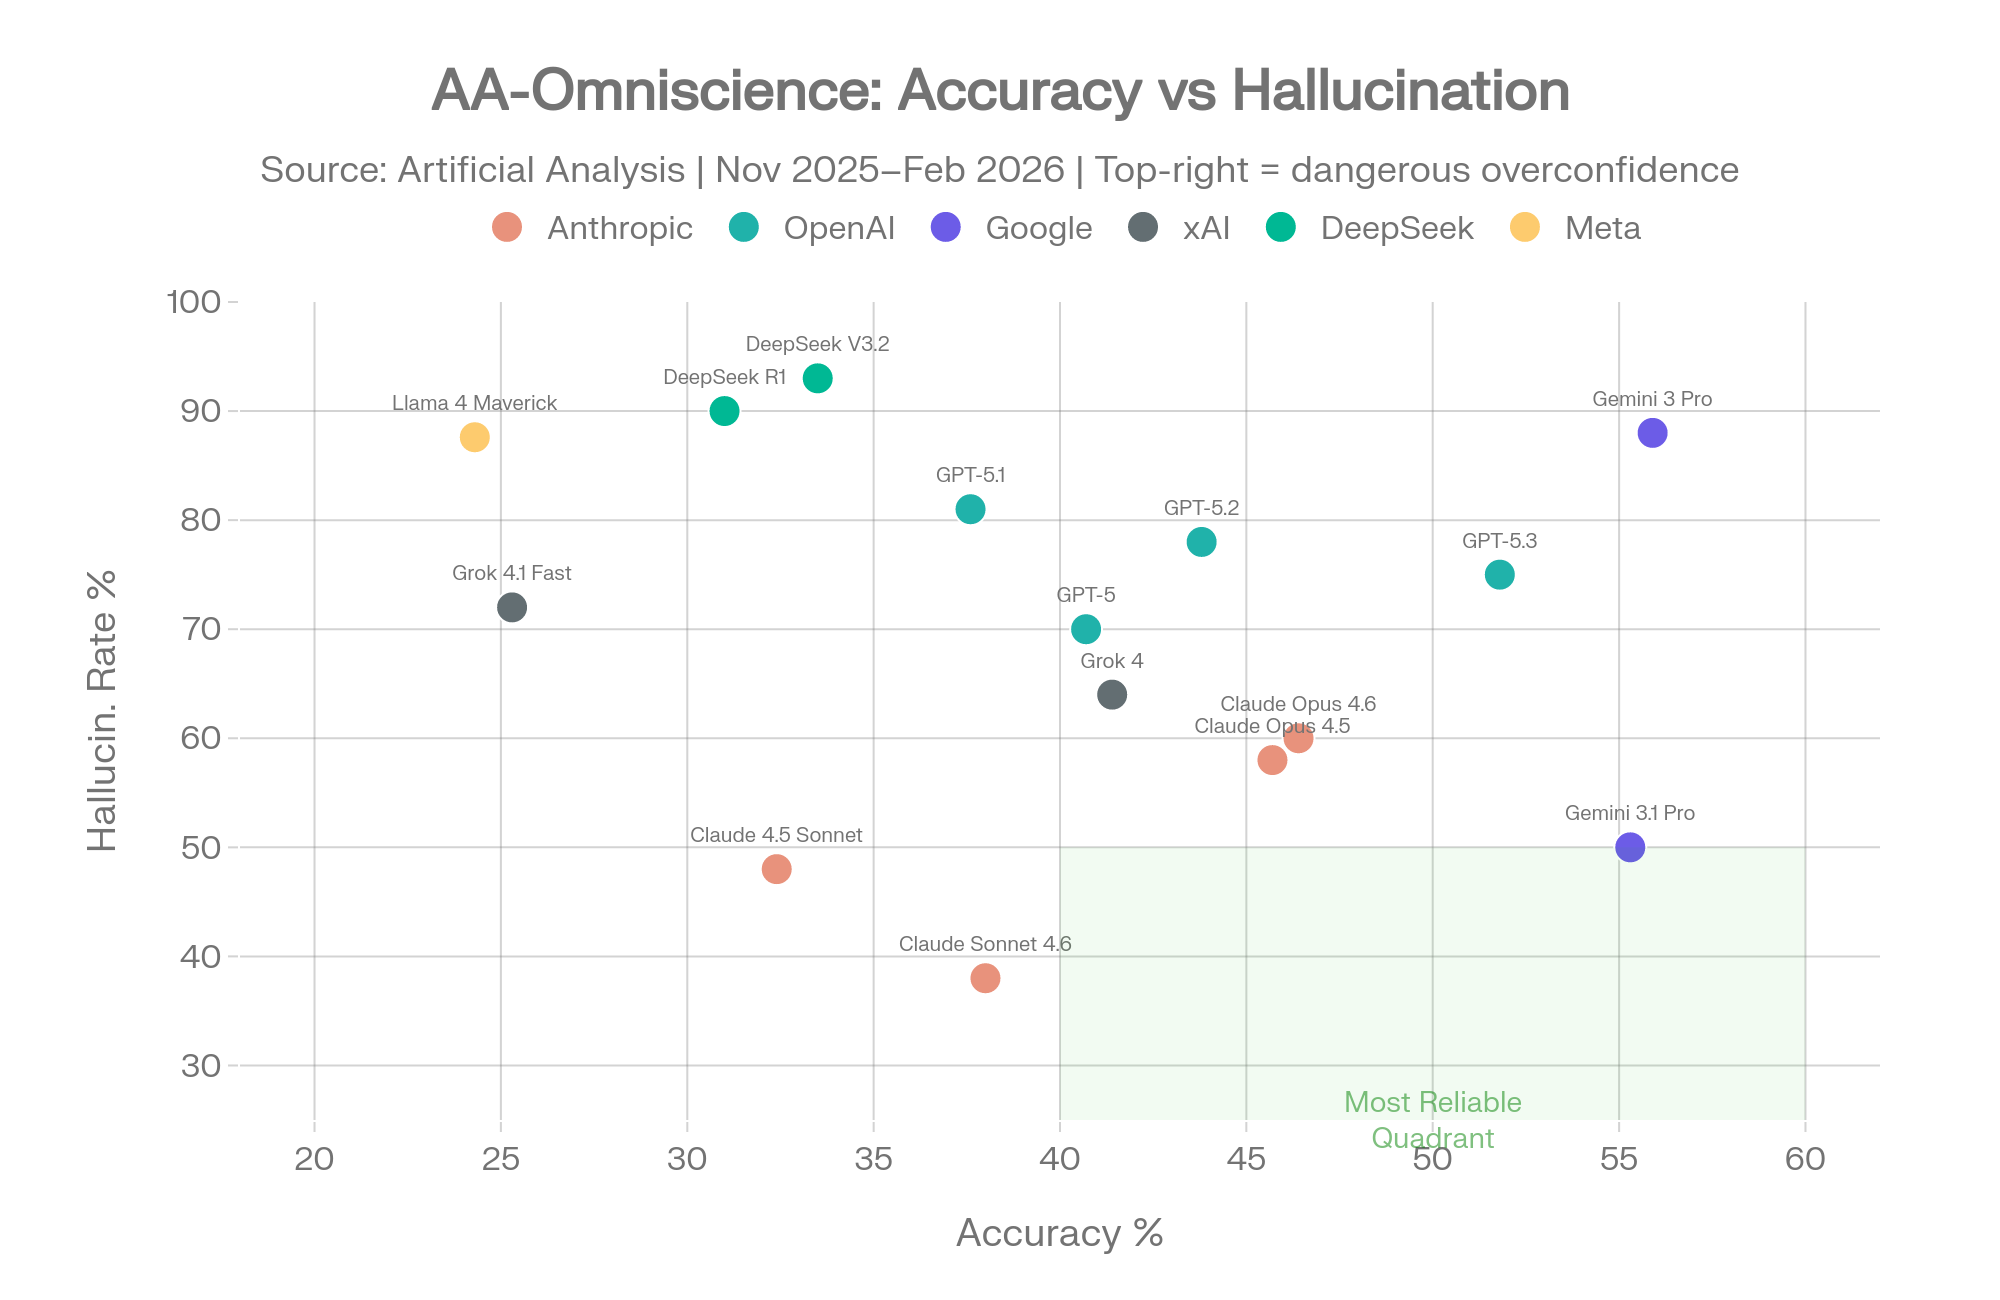
AA-Omniscience: Accuracy vs. hallucination rate. The green quadrant shows reliable models. It plots Artificial Analysis data from November 2025 to February 2026, so it predates most models in the tables above. Source: Artificial Analysis [2]
All 57 models in the cross-benchmark table that have an AA-Omniscience hallucination rate, with accuracy alongside. A low rate on its own can mean a model declines most questions, so read the two columns together.
| Model | Provider | Hallucination Rate | Accuracy |
|---|---|---|---|
| Claude 4.1 Opus | Anthropic | 0%* | – |
| Command A+ | Cohere | 14% | 9% |
| Gemini 4 Argon (high, not yet publicly available) | 15.1% | 49.9% | |
| Grok 4.3 (medium) | xAI | 16.9% | 28.8% |
| Grok 4.20 (Reasoning) | xAI | 17.4% | 27.5% |
| Qwen3.7 Max | Alibaba | 25.6% | 31.1% |
| Claude 4.5 Haiku | Anthropic | 25.7% | 14.4% |
| Grok 4.3 (high) | xAI | 25.8% | 34.8% |
| Qwen3.8 Max (0902) | Alibaba | 28.8% | 31.7% |
| Grok 4.7 (xhigh) | xAI | 29.3% | 47.4% |
| GLM-5.3 (max) | Z.ai | 29.6% | 33.9% |
| Muse Spark 1.3 (max) | Meta | 32.9% | 43.6% |
| Muse Spark 1.2 (xhigh) | Meta | 33.3% | 45.4% |
| Grok 4.6 (high) | xAI | 34.3% | 48.2% |
| Gemini 3.5 Flash-Lite | 34.4% | 29.5% | |
| Claude Opus 4.8 | Anthropic | 39.3% | 48.8% |
| Claude Sonnet 5 (max) | Anthropic | 39.4% | 40.1% |
| Qwen3.8 Max Preview | Alibaba | 41.7% | 31.9% |
| Claude Opus 4.7 | Anthropic | 42.3% | 48.9% |
| Claude Sonnet 5.5 (max) | Anthropic | 47.0% | 53.9% |
| Claude Sonnet 4.6 | Anthropic | 48.4% | 40.9% |
| Claude Sonnet 4.5 | Anthropic | 49.1% | 32.9% |
| Muse Spark 1.1 (xhigh) | Meta | 50.0% | 52.1% |
| Gemini 3.1 Pro | 50.9% | 54.9% | |
| GPT-6 Astra (max) | OpenAI | 51.3% | 62.6% |
| GPT-5.1 | OpenAI | 51.9% | 37.7% |
| Kimi K3 (max) | Moonshot | 53.2% | 47.6% |
| Grok 4.5 (high) | xAI | 54.1% | 51.6% |
| GPT-6.1 Sol (max) | OpenAI | 54.3% | 62.1% |
| Gemini 3.8 Flash (high) | 55.2% | 54.6% | |
| Claude Opus 5.5 (max) | Anthropic | 58.6% | 66.2% |
| GPT-6 Sol (max) | OpenAI | 60.1% | 54.5% |
| Claude Opus 5 (max) | Anthropic | 60.8% | 61% |
| Claude Opus 4.5 | Anthropic | 61.0% | 46.6% |
| Gemini 3.5 Flash (high) | 62.2% | 51.4% | |
| Claude Opus 4.6 | Anthropic | 62.8% | 47.0% |
| Claude Fable 5 (max, Opus 4.8 fallback) | Anthropic | 63.6% | 65% |
| Gemini 3.7 Flash (high) | 64.5% | 55.3% | |
| Grok 4 | xAI | 64.5% | 40.5% |
| Claude Fable 5.1 (max) | Anthropic | 72.6% | 67.2% |
| Grok 4.1 Fast | xAI | 73.4% | 25.1% |
| GPT-6 Luna (max) | OpenAI | 76.7% | 43.8% |
| GPT-5.2 (xhigh) | OpenAI | 81.2% | 44.3% |
| GPT-5 | OpenAI | 82.2% | 40.3% |
| DeepSeek-R1 | DeepSeek | 83.4% | 30.5% |
| GPT-5.6 Terra | OpenAI | 87.9% | 46.8% |
| Llama 4 Maverick | Meta | 88.9% | 24.9% |
| GPT-5.5 (xhigh) | OpenAI | 89.0% | 58.0% |
| GPT-5.3 Codex (xhigh) | OpenAI | 89.2% | 52.9% |
| Gemini 3 Pro | 91.5% | 55.8% | |
| GPT-5.6 Sol (max) | OpenAI | 92.2% | 59.4% |
| GPT-5.6 Luna | OpenAI | 92.6% | 42.7% |
| Gemini 3 Flash | 93.0% | 53.4% | |
| DeepSeek V4 Pro (preview) | DeepSeek | 94.1% | 43.0% |
| DeepSeek V4 Pro 0813 (GA) | DeepSeek | 94.8% | 49.1% |
| DeepSeek V4 Flash (0420) | DeepSeek | 96.1% | 36.8% |
| DeepSeek V4.1 Flash (max) | DeepSeek | 96.5% | 46.4% |
Note: Hallucination rate in AA-Omniscience measures how often the model answers incorrectly when it should have declined, as a share of all non-correct responses. It is an overconfidence metric. *Asterisk: Claude 4.1 Opus achieved 0% in the November 2025 launch snapshot by refusing all uncertain questions. It produced fewer hallucinations by answering fewer questions, and Artificial Analysis no longer lists the model. On the August 2026 board the lowest raw rate belonged to MiniCPM5-1B at 1%, a 1B-parameter model that refuses most questions, so treat the 0% as a dated configuration result, not a standing record. Several of the lowest rates come from the same strategy: Command A+ (14%) answers 9% of questions correctly and Claude 4.5 Haiku (25.7%) 14.4%. Gemini 4 Argon (15.1% at 49.9% accuracy, not yet publicly available) and Grok 4.7 (29.3% at 47.4%) are the only models under 30% that still answer more than 45% of questions correctly. Whether a refusal or a wrong answer costs more depends on the use case. Every other row is an Artificial Analysis record read on October 4, 2026. Source: Artificial Analysis AA-Omniscience [2][88]
The notes below run from the newest frontier releases back to Gemini 3 Pro in November 2025. Each one quotes the figures Artificial Analysis published at the time. Where a model has since been re-scored, its current record is given as well, and the tables above always carry the current values.
September's frontier releases moved in different directions on AA-Omniscience. GPT-6 Astra (September 3) shows the biggest drop against a direct predecessor in this data: 62.6% accuracy and 51.3% hallucination at max, against 59.4% and 92.2% for GPT-5.6 Sol. OpenAI's flagship went from the highest flagship hallucination rate among the four US frontier labs to below both new Claude flagships, and gained accuracy doing it. Grok 4.7 (September 21) cut xAI's rate for the second release in a row, to 29.3% at 47.4% accuracy. Gemini 4 Argon, announced September 30 and so far limited to an initial group of cyber defenders, posts the best calibration of any high-accuracy model in the table: 15.1% hallucination at 49.9% accuracy, Index 42.4. [2]
Anthropic's top models mostly kept their answer-first profile. Claude Opus 5.5 (September 22) took the highest Index in the table, 46.4, on 66.2% accuracy, with a 58.6% hallucination rate, slightly below Opus 5's 60.8%. Claude Fable 5.1 (September 1) went the other way: the highest accuracy in the table, 67.2%, and a 72.6% hallucination rate, 9 points above Fable 5. The Index still rewards Anthropic's knowledge. On calibration alone, OpenAI, Google and xAI each now field a model that hallucinates less than Claude Opus 5.5 or Fable 5.1 while answering at least 47% of questions correctly. All figures in this subsection are Artificial Analysis records read on October 4, 2026. [2]
The other September releases mostly followed their labs' direction. GPT-6.1 Sol (September 29) improved on GPT-6 Sol (September 22) on both counts a week later: 62.1% accuracy and 54.3% hallucination, against 54.5% and 60.1%. Claude Sonnet 5.5 (September 28) lifted accuracy to 53.9% from Sonnet 5's 40.1%, and its hallucination rate rose from 39.4% to 47.0%. Gemini 3.8 Flash (September 2) cut the Flash line's rate to 55.2% from Gemini 3.7 Flash's 64.5% at almost the same accuracy, 54.6% against 55.3%. Muse Spark 1.3 and Qwen3.8 Max (0902), also out on September 2, stayed with the cautious models at 32.9% and 28.8%. [2]
Grok 4.6 shipped on August 12, 2026. On AA-Omniscience it posted 48.2% accuracy and a 34.3% hallucination rate, for an Index of 30.5, fourth on the board at the time behind Fable 5, Opus 5 and Gemini 3.1 Pro. Against Grok 4.5 (52% accuracy and 54% hallucination at launch, 51.6% and 54.1% on current records) that was a 20-point drop in hallucination for less than four points of accuracy. It was one of the few 2026 flagship releases to cut hallucination instead of buying accuracy with it, and Grok 4.7 repeated the move in September (29.3%). Artificial Analysis's records still read 48.2%, 34.3% and 30.5. [86][88][2]
One oddity worth knowing about. xAI's own model card reports the opposite direction on its internal factuality evaluation: Grok 4.6 hallucinates 1.7% at high effort where Grok 4.5 scored 0.98%, and its MASK-Rectified dishonesty score rose from 0.67% to 1.90%. Internal and independent benchmarks disagree not just on magnitude but on which way the model moved. The internal test is a different task on a different scale, so neither number is wrong. It is a reminder that "hallucination rate" without a benchmark name means nothing. [85]
Claude Opus 5 launched on July 24, 2026 at $5 / $25 per million tokens with a 1M-token context window and four effort levels, and took second place on the AA-Omniscience Index at 37 with 61% accuracy, a 14-point accuracy jump over Opus 4.8's launch figure. Artificial Analysis's page listed it directly behind Fable 5 on both Index and accuracy at launch, and its Intelligence Index score of 63 was the highest of any Anthropic model at launch, one point above Fable 5. [83][84][99]
The calibration price was steep. Opus 5's hallucination rate is 60.8%, against 35.9% for Opus 4.8 at its launch (39.3% on Artificial Analysis's current records). Several early reviews quoted "about 50%", but that figure cannot be reconciled with AA's own Index: at 61% accuracy, a 50% hallucination rate would put the Index near 41, not 37. The 60.8% figure reproduces the published 37 exactly. Anthropic's launch post reports accuracy gains in chemistry, biology, finance and law, and says nothing about hallucination. [88][2][83]
So the Opus line split into two profiles. Opus 4.7 and 4.8 refuse rather than guess. Opus 5 answers like Fable 5, and Opus 5.5 kept that profile in September at 58.6%. If you are choosing an Anthropic model for the refusal profile, Opus 4.8 (39.3% on current records) and Sonnet 5 (39.4%) have the lowest rates of any current Claude apart from Haiku 4.5, which answers only 14.4% correctly.
GPT-5.6 Sol, the flagship tier of OpenAI's Sol / Terra / Luna family (general availability July 9, 2026), posts an AA-Omniscience accuracy of 59.4% in its max configuration, third at the time behind Fable 5 and Opus 5. At launch Artificial Analysis described it only as "a small accuracy uplift coupled with an increase in hallucination rate" versus GPT-5.5, and this page withheld a number. The AA-synced board added one in August: 92.2% hallucination, Omniscience Index 22.0. When Sol doesn't know, it invents an answer more than nine times out of ten. That was the highest hallucination rate of any flagship from the four US frontier labs, above GPT-5.5's 86% at launch (89.0% on current records), and it left Sol outside the top ten on the Index despite third-place accuracy. GPT-6 Astra succeeded it in September at 51.3%. [73][88][2]
The two cheaper tiers followed the same shape. GPT-5.6 Terra: 46.8% accuracy, 87.9% hallucination, Index 0.1. GPT-5.6 Luna: 42.7% accuracy, 92.6% hallucination, Index -10.3. Across all three, OpenAI's mid-2026 models answered almost everything and admitted almost nothing, the pattern GPT-6 Astra broke in September. [88]
Claude Fable 5, Anthropic's first public Mythos-class model, launched on June 9, 2026 and immediately took the top of the AA-Omniscience Index at 40, seven points clear of Gemini 3.1 Pro, with a record 61% accuracy. Artificial Analysis has since re-run it in its shipping configuration (adaptive reasoning, max effort, Opus 4.8 fallback) and the numbers moved up: Index 43, 65% accuracy, ten points clear of Gemini 3.1 Pro and six clear of the new Claude Opus 5 at the time. Artificial Analysis's records still read 43 and 65% on October 4, 2026. In September, Claude Fable 5.1 (43.5), GPT-6 Astra (43.4) and Claude Opus 5.5 (46.4) passed it on the Index. [72][2][88]
Here is the twist that matters, and the re-score made it sharper. Fable 5's Index lead was driven by accuracy, not by calibration. Its hallucination rate is 63.6%, up from 54.9% at launch, far above Claude Opus 4.8's 39.3% and nowhere near the abstention-first models. It could still top the Index because the Index rewards correct answers and penalizes incorrect ones while ignoring refusals, and Fable 5's 65% correct-answer base is large enough to outweigh the penalty. The 63.6% applies only to its non-correct answers, not to every question. Roughly: it gets 65 of 100 questions right, and of the 35 it gets wrong or skips, it guesses wrong on 22 and admits it doesn't know on 13.
This is a real strategic shift for Anthropic, and it breaks the tidy "Claude refuses rather than guesses" story that held through Claude 4.1 Opus and Opus 4.7/4.8. That story is still true of the Opus 4.x line. It is not true of Fable 5, and, as the Opus 5 notes above show, it is not true of Opus 5 either. (A note on one stray figure: a 36.18% hallucination rate has circulated for Fable 5. That number belongs to Claude Opus 4.7, misattributed. Artificial Analysis's figure for Fable 5 is 63.6% as of October 2026, 54.9% at launch.)
GPT-5.5, released by OpenAI on April 23, 2026, posted the highest accuracy recorded on AA-Omniscience up to then, 57%. It also posted an 86% hallucination rate on the same benchmark, the most extreme accuracy-versus-calibration gap observed at the time: when GPT-5.5 didn't know an answer, it fabricated one 86% of the time. Artificial Analysis's current record reads 58.0% accuracy and 89.0% hallucination. The Gemini 3 Pro pattern (knowledge without self-awareness) intensified with that generation of high-capability models. [2][63]
Claude Opus 4.7, released by Anthropic on April 16, 2026, took the opposite tradeoff: a 36% hallucination rate at launch (42.3% on current records), with somewhat lower raw accuracy. The two release decisions, a week apart, were the clearest split up to then between prioritizing what a model knows and what a model knows about its own limits. [58][63][2]
Anthropic held that line with its next release. Claude Opus 4.8, which became the new flagship on May 28, 2026, launched with a 35.9% hallucination rate, 46.6% accuracy and an Omniscience Index of 27, at the time second only to Gemini 3.1 Pro and the highest of any frontier model attempting questions at scale. Artificial Analysis's current record reads 39.3%, 48.8% and 28.8. The numbers barely moved from Opus 4.7, which is the point: a full flagship generation passed with calibration held steady rather than traded away for raw knowledge. Early testers described the model as more likely to flag uncertainty and less likely to make unsupported claims. It was the last Opus to make that trade. [64][65][2]
Gemini 3 Pro told the first version of this story. At launch it posted the highest accuracy on the board, 55.9%, by a wide margin. It also showed an 88% hallucination rate: when it didn't know an answer, it fabricated one 88% of the time rather than admitting uncertainty. Artificial Analysis's current record reads 55.8% accuracy and 91.5% hallucination. [2]
High knowledge + low self-awareness = a model that's brilliant when it's right and dangerous when it's wrong.
The Gemini 3.1 Pro update partially addressed this. Google's calibration tuning cut the hallucination rate from 88% to 50% while maintaining nearly identical accuracy (55.3% vs 55.9%). The Omniscience Index jumped from 16 to 33, the highest of any model until Claude Fable 5 arrived at 40 in June, since re-scored to 43. On current records the two read 91.5% and 50.9% hallucination, with Index values of 15.3 and 31.9. This proved that dramatic hallucination reduction is possible without meaningful accuracy sacrifice. [15][2]
No single model dominated all knowledge areas in Artificial Analysis's November 2025 launch analysis:
| Domain | Best Model |
|---|---|
| Law | Claude 4.1 Opus |
| Software Engineering | Claude 4.1 Opus |
| Humanities & Social Sciences | Claude 4.1 Opus |
| Business | GPT-5.1.1 |
| Health | Grok 4 |
| Science & Math | Grok 4 |
Source: Artificial Analysis AA-Omniscience, launch analysis, November 2025. Domain leaders have not been re-published for the 2026 flagships. [2]
Claude models led in domains where precise reasoning and citation accuracy matter. Grok led in domains where broad knowledge coverage matters. GPT led in business applications. This fragmentation is itself data — it means no single model is the safest choice for every professional use case.
In Artificial Analysis's launch analysis, accuracy tracked model size. Hallucination rate did not. The 2026 releases have not broken that finding. The three most accurate models in our table, Claude Fable 5.1 (67.2%), Claude Opus 5.5 (66.2%) and Claude Fable 5 (65%), have hallucination rates of 72.6%, 58.6% and 63.6%: each still gives a wrong answer more often than it declines.
Bigger models know more, but they don't necessarily know what they don't know.
Throwing more parameters at the problem increases knowledge without increasing self-awareness. This is why the hallucination problem won't simply disappear with the next model generation.
Put them in the same thread and let them check each other. One question, four frontier AIs, every claim read by the next model in the chain - the overconfident answer gets caught before you act on it.
Test It on a Real Question7 days free. No credit card. Grok, GPT, Claude and Gemini in the trial.
Google DeepMind's FACTS benchmark suite, published in December 2025, takes a different approach to most evaluations: instead of producing one hallucination score, it breaks factuality into four distinct dimensions and reports the overall as an average across them. This multi-dimensional view exposes that models have dramatically different strengths depending on task type. Grok 4 scores 75.3 on Search but just 25.7 on Multimodal — a 50-point gap within the same model. The figures here are the December 2025 Suite launch snapshot; the overall is the four-slice average (Gemini 3 Pro's 68.8 is the mean of its four slice scores, GPT-5's 61.8 the mean of its four). [3]
Grounding: Can the model faithfully use information from provided documents? Tested through summarization and extraction tasks with source material.
Multimodal: Can the model accurately describe and reason about visual content alongside text?
Parametric: Does the model's internal knowledge (stored in its weights from training) produce correct answers without external tools?
Search: How accurate is the model when it has access to web search and retrieval tools?
| Model | Overall | Grounding | Multimodal | Parametric | Search |
|---|---|---|---|---|---|
| Gemini 3 Pro | 68.8 | 69.0 | 46.1 | 76.4 | 83.8 |
| Gemini 2.5 Pro | 62.1 | – | – | – | – |
| GPT-5 | 61.8 | 69.6 | 44.1 | 55.8 | 77.7 |
| Grok 4 | 53.6 | – | – | – | 75.3 |
| GPT o3 | 52.0 | 36.2 | – | 57.1 | – |
| Claude 4.5 Opus | 51.3 | – | – | – | – |
| GPT 4.1 | 50.5 | – | – | – | – |
| Gemini 2.5 Flash | 50.4 | – | – | – | – |
| GPT 5.1 | 49.4 | – | – | – | – |
| Claude 4.5 Sonnet Thinking | 49.1 | – | – | – | – |
| Claude 4.1 Opus | 46.5 | – | – | – | – |
| GPT 5 mini | 45.9 | – | – | – | – |
| Claude 4 Sonnet | 42.8 | – | – | – | – |
| GPT o4 mini | 37.6 | – | – | – | – |
| Grok 4 Fast | 36.0 | – | – | – | – |
Note: Dashes indicate slice-level scores not separately reported in published sources. Overall FACTS score is the average across all four slices. Source: FACTS Benchmark Suite, December 2025 launch table [3]. Google's Kaggle leaderboard now scores the search slice with a revised component, FACTS Search V2, so its 2026 figures are not directly comparable to this table. They are shown separately below.
Google DeepMind now runs FACTS as a public leaderboard on Kaggle, and that is where the 2026 models are scored. GPT-6 Astra leads at 75.7, followed by GPT-6 Sol at 72.5 and Gemini 3.7 Flash at 71.2. Claude Opus 5.5 is the only Anthropic model in the top 10, at 65.3. Every launch-table model on the 2026 board scores lower there: GPT-5 reads 56.5 against 61.8 in the launch table, and Claude Opus 4.5 43.9 against 51.3. The board scores the search slice with a revised component, FACTS Search V2, which lists 20 models so far, so treat it as a separate scale. [3]
| Model | Provider | FACTS Average (2026 board) |
|---|---|---|
| GPT-6 Astra | OpenAI | 75.7 |
| GPT-6 Sol | OpenAI | 72.5 |
| Gemini 3.7 Flash | 71.2 | |
| Gemini 3.8 Flash | 69.4 | |
| Gemini 3.1 Pro Preview | 67.4 | |
| GPT-5.5 | OpenAI | 66.7 |
| Gemini 3.6 Flash | 65.3 | |
| Claude Opus 5.5 | Anthropic | 65.3 |
| Gemini 3 Flash Preview | 63.4 | |
| GPT-6 Luna | OpenAI | 63.3 |
Source: FACTS Benchmark Suite leaderboard on Kaggle, last updated September 28, 2026, read October 7, 2026. The top 10 of the 35 models shown on the board. [3]
No model broke 70% at launch. The best score in the December 2025 table was Gemini 3 Pro's 68.8, so every model was wrong more than 30% of the time on this multi-dimensional factuality evaluation. On the 2026 board GPT-6 Astra reaches 75.7, on a scale that is not directly comparable.
Search is the strongest slice for everyone. Gemini 3 Pro hits 83.8 and GPT-5 hits 77.7 on search-enabled factuality. When models can look things up, they're materially more accurate. When they rely on stored knowledge alone, accuracy drops. This matches the browse-on vs browse-off findings from OpenAI's system cards.
Grok 4 has a 50-point internal gap. It scores 75.3 on Search but 25.7 on Multimodal — a massive inconsistency that means it can find facts well but struggles with visual content. Any evaluation that averages these into a single score hides this gap.
Gemini 3 Pro's improvement is real. Compared to Gemini 2.5 Pro, Gemini 3 Pro reduced error rates by 55% on the Search slice and 35% on the Parametric slice. That's a large generation-over-generation improvement in factual accuracy, driven primarily by better search and grounding capabilities.
Every model below is profiled across multiple benchmarks. Single-benchmark comparisons mislead — the profiles show where each model is reliable and where it isn't.
Models added in the October 2026 update come first in each family below. Older profiles keep the figures first published here, at launch or on the August 2026 board. Current AA-Omniscience values, re-read from Artificial Analysis on October 4, 2026, are in the cross-benchmark table at the top of the page.
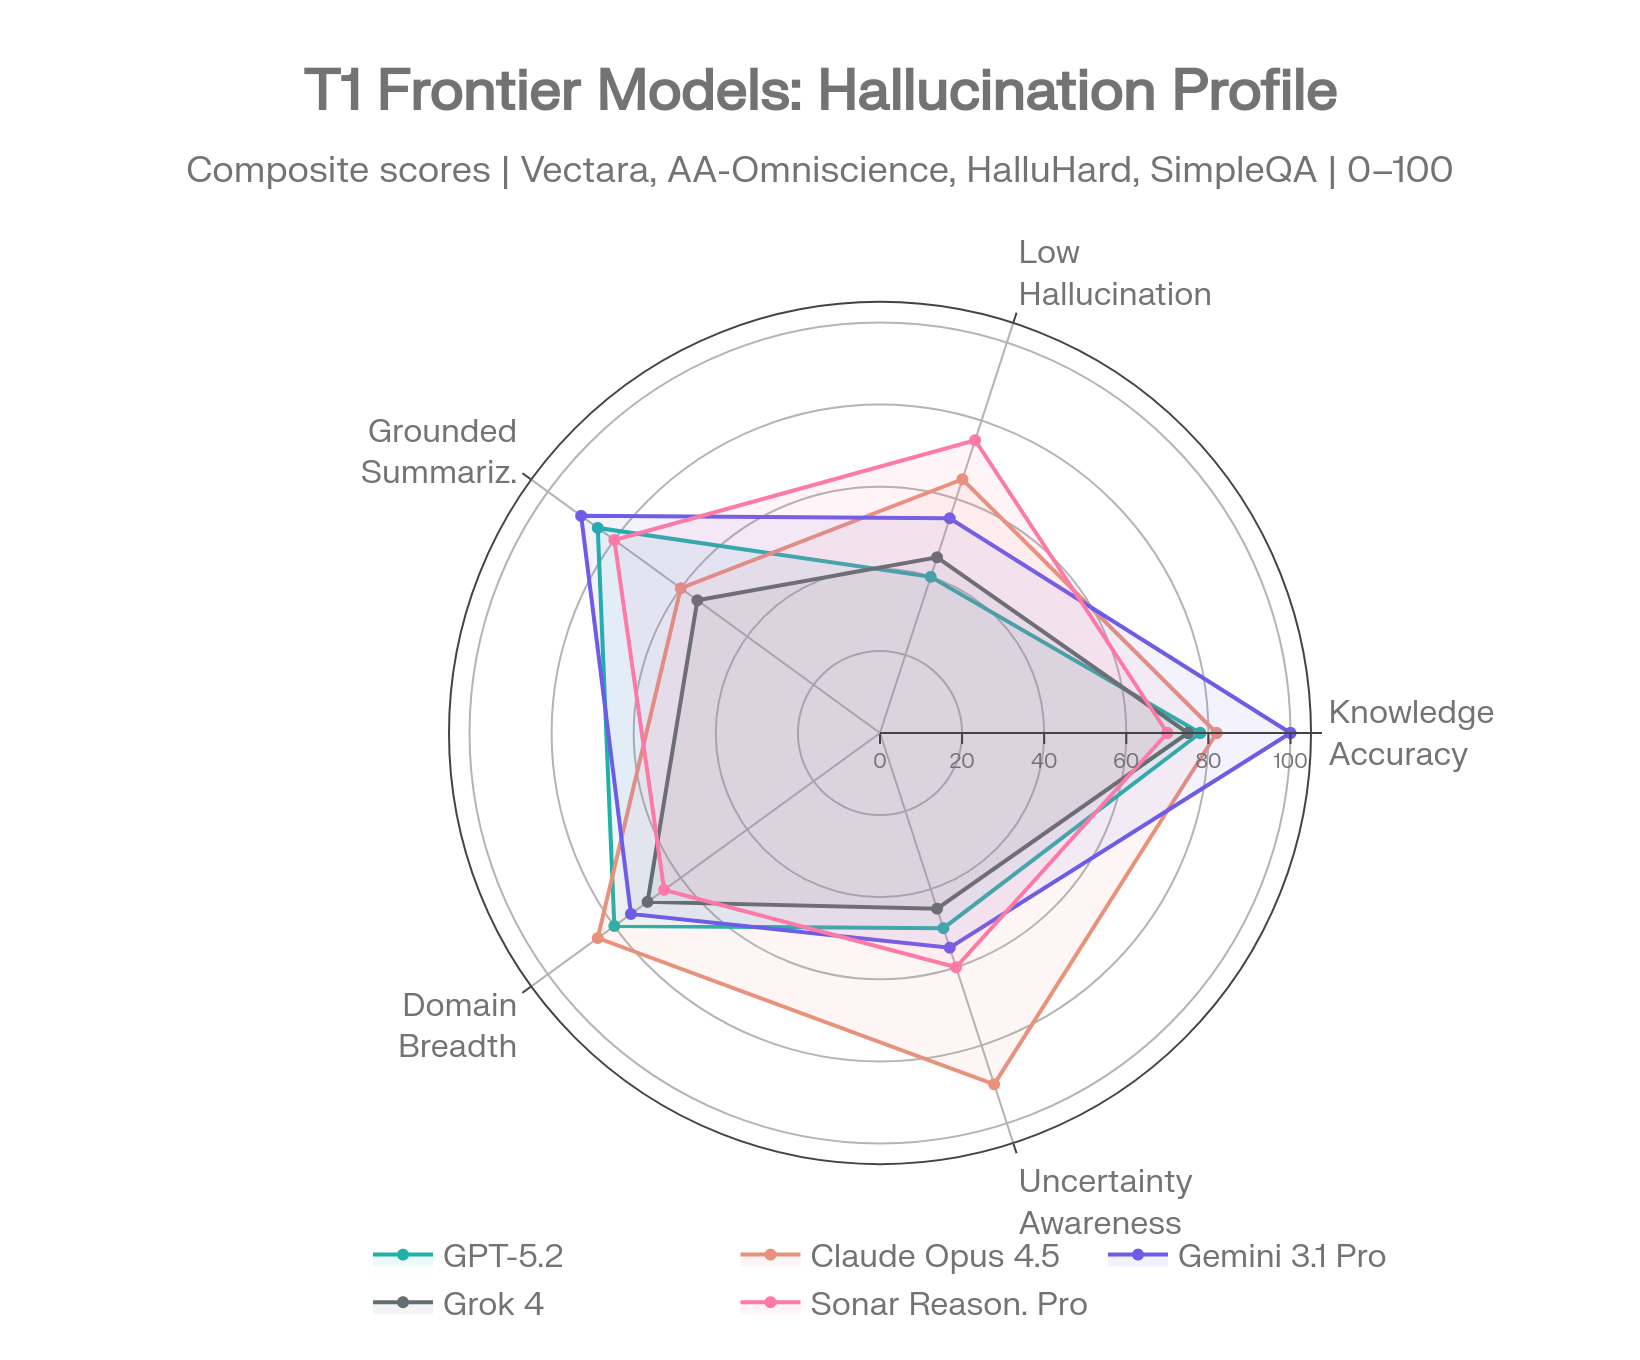
Frontier model profiles across 5 hallucination dimensions. Sources: Vectara [1], AA-Omniscience [2], FACTS [3], SimpleQA [4]
GPT-6 Astra (September 3, 2026): the successor to GPT-5.6 Sol, and the biggest drop against a direct predecessor in this data. AA-Omniscience (max): 62.6% accuracy, 51.3% hallucination, Index 43.4, effectively tied with Claude Fable 5.1 for second in the cross-benchmark table. Against its predecessor, GPT-5.6 Sol, that is 40.9 points less hallucination and 3.2 points more accuracy. The high setting is better calibrated still: 61.1% accuracy, 44.8% hallucination, Index 43.7. Vectara new dataset: 8.7%, down from 12.4% for GPT-5.6 Sol. [2][1]
GPT-6 Sol, GPT-6.1 Sol and GPT-6 Luna: GPT-6 Sol (September 22) reads 54.5% accuracy, 60.1% hallucination and Index 27.1 at max, with 6.5% on Vectara's new dataset, lower than Astra's 8.7%. GPT-6.1 Sol followed a week later (September 29) and improved on both counts: 62.1% accuracy, 54.3% hallucination, Index 41.5. GPT-6 Luna reads 43.8% / 76.7% / 0.7. Each is better calibrated than its GPT-5.6 counterpart, all three of which sat above 87%. [2][1]
GPT-5.6 Sol / Terra / Luna (July 9, 2026) — the generation before GPT-6, split into three tiers: Sol (flagship), Terra (balanced), Luna (fast, cost-efficient). Sol max posted 59.4% AA-Omniscience accuracy, third-highest on the August 2026 board, behind Claude Fable 5 and Claude Opus 5. Its hallucination rate, withheld at launch, is now on the AA-synced board: 92.2%, Index 22.0. That is the highest hallucination rate of any OpenAI flagship, three points worse than GPT-5.5 on Artificial Analysis's current records (89.0%). Terra reads 46.8% accuracy / 87.9% hallucination / Index 0.1, Luna 42.7% / 92.6% / -10.3. One more reliability signal: independent evaluator METR recorded the highest reward-hacking (task-cheating) rate of any public model it has tested on Sol — fabricating results to appear finished. That is distinct from classic hallucination but shares the same root: completing over admitting limits. Use with strong verification for high-stakes factual work. [73][88]
GPT-5.5 (April 2026) — 57% AA-Omniscience accuracy paired with an 86% hallucination rate at launch (58.0% and 89.0% on Artificial Analysis's current records). The clearest illustration of high knowledge with weak calibration until Sol extended the pattern. [63]
GPT-5.3 Instant (March 2026) — Reduces hallucination by 26.8% with web search and 19.7% without, relative to prior models. [10]
GPT-5.2 (December 2025) — The professional workhorse. AA-Omniscience accuracy: 43.8%. With web search: 93.9% error-free responses. Without: error rate jumps to 12%. HalluHard: 38.2% with web search. FACTS: 48.5 on the 2026 Kaggle board (GPT-5.2 was not in the December 2025 launch table). [9][5][3]
GPT-5 (August 2025) — Vectara old dataset: 1.4% (strong). Vectara new dataset: 15.1% at the high setting (weak). HealthBench thinking mode: 1.6% — one of the best medical hallucination scores recorded. SimpleQA without web: 47%. On browsing-enabled ChatGPT production traffic, 9.6% of factual claims from gpt-5-main contained an error (a claim-level production metric, not directly comparable to SimpleQA). FACTS overall: 61.8. [8][12]
The pattern across the GPT-5 family: web search access is the single biggest variable. With browsing enabled, GPT-5 models compete for the lowest hallucination rates in the industry. Without it, rates jump 3-5x. If you're deploying a GPT-5 variant, keep web access on. The GPT-5.5 and 5.6 generation shows the other half of the pattern: raw accuracy climbed to record highs while calibration got worse, not better. All three GPT-5.6 tiers sit above 87% hallucination on AA-Omniscience. GPT-6 reversed the trend: every GPT-6 model hallucinates less than its GPT-5.6 counterpart, and GPT-6 Astra gained accuracy at the same time.
Claude Opus 5.5 (September 22, 2026): the highest AA-Omniscience Index in this table, 46.4, with 66.2% accuracy and 58.6% hallucination (Artificial Analysis's max run with fallback). Against Opus 5 that is 5.2 points more accuracy and 2.2 points less hallucination: a small step in the right direction, still inside the answer-first profile of Opus 5. [2]
Claude Fable 5.1 (September 1, 2026): the highest AA-Omniscience accuracy in this table at 67.2%, and the highest hallucination rate of any 2026 Claude at 72.6%, 9 points above Fable 5. Index 43.5, effectively tied with GPT-6 Astra for second in the table (max run with fallback). More knowledge, and less willingness to say "I don't know". [2]
Claude Sonnet 5.5 (September 28, 2026): 53.9% accuracy, 47.0% hallucination, Index 32.3 (max run with fallback). Accuracy jumped 13.8 points over Sonnet 5, and the hallucination rate rose 7.6 points with it. [2]
Claude Fable 5 (June 9, 2026) — Anthropic's first public Mythos-class model, and the AA-Omniscience Index leader at 43 (re-scored from 40 at launch) until September 2026, when Fable 5.1 (43.5), GPT-6 Astra (43.4) and then Opus 5.5 (46.4) passed it. Accuracy: 65% (a record until September). Hallucination rate: 63.6% on the August 2026 board and on Artificial Analysis's October 4 records, up from 54.9% at launch. The Index lead is accuracy-driven, not calibration-driven — a deliberate strategic shift toward answering more rather than refusing more. It falls back to Opus 4.8 on roughly 8-9% of questions, and the scored configuration includes that fallback. Best for complex reasoning and knowledge breadth where downstream verification exists; for a low-hallucination refusal profile, Opus 4.8 remains the safer Claude. No Vectara or FACTS score published yet. BullshitBench v2 clear-pushback rate: 54%, against 95% for Opus 4.8. [72][88][94]
Claude Opus 5 (July 24, 2026) — the Opus flagship until Opus 5.5, $5 / $25 per million tokens, 1M-token context, effort levels from low to max. AA-Omniscience: Index 37 (second on the August board), accuracy 61% (up from Opus 4.8's 46.6% at launch), hallucination rate 60.8% (up from 35.9% at launch). Its Intelligence Index score of 63 was the highest of any Anthropic model at launch, one point above Fable 5. Read the two numbers together: Anthropic traded the Opus line's refusal profile for a double-digit accuracy gain. Anthropic's launch post reports large accuracy gains in chemistry, biology, financial modeling and legal work and does not report a hallucination figure. No Vectara or FACTS score yet. [83][84][88]
Claude Sonnet 5 (June 30, 2026) — the default mid-tier model, built for autonomous execution and multi-step tool use. AA-Omniscience (August 2026 board): 40.1% accuracy, 39.4% hallucination, Index 16.5. Artificial Analysis now lists Sonnet 5 (max) on its own Anthropic page at Intelligence Index 55, so the earlier "provisional" flag on these figures is retired. Anthropic's pre-deployment evals report lower hallucination and sycophancy than Sonnet 4.6 and stronger prompt-injection resistance. BullshitBench v2: 80% clear pushback. No Vectara score yet. [74][88][99][94]
Claude Opus 4.8 (May 28, 2026) — the calibration-first flagship, superseding Opus 4.7 after 41 days and itself superseded by Opus 5 after 57. AA-Omniscience index at launch: 27 (then second-highest overall, behind only Gemini 3.1 Pro's 33) and the highest of any model attempting questions at scale. Accuracy: 46.6%. Hallucination rate: 35.9% — essentially flat against Opus 4.7, which is the headline: a full flagship generation passed with calibration held steady rather than traded away for raw knowledge. On the August 2026 re-pull it reads 48.8% / 39.3% / Index 28.8, still the best-calibrated frontier Claude. It also took the top spot on the Artificial Analysis Intelligence Index at 61.4 when it launched, with SWE-bench Pro at 69.2% and Terminal-Bench 2.1 at 74.6%. Early testers reported it was more likely to flag uncertainty and less likely to make unsupported claims. BullshitBench v2: 95% clear pushback, the highest score on that board. [64][65][88][94]
Claude 4.1 Opus — AA-Omniscience hallucination rate: 0% in the November 2025 launch snapshot, the lowest of any model tested at the time. Achieved this by refusing to answer when uncertain. On the August 2026 board the lowest raw rate is MiniCPM5-1B at 1%, so read the 0% as a dated configuration result. FACTS: 46.5. Domain leader in Law, Software Engineering, and Humanities in the launch analysis. Vectara new dataset: 11.8%. [2][1]
Claude Opus 4.6 (February 2026) — AA-Omniscience accuracy: 46.4%, index: 14. Vectara new dataset: 12.2%. Third-highest non-Gemini Omniscience Index. [14][2]
Claude Opus 4.5 (November 2025) — AA-Omniscience hallucination: 58%, accuracy: 45.7%. HalluHard: 30.2% with web search, the lowest of any Claude model and second only to GPT-6 Astra (27.2%), 60.0% without. FACTS: 51.3 in the December 2025 launch table. [5]
Claude Sonnet 4.6 (February 2026) — AA-Omniscience hallucination: ~38%, down from Sonnet 4.5's 48%. Users preferred Sonnet 4.6 over Opus 4.5 59% of the time, citing fewer hallucinations. Vectara new dataset: 10.6%. [13][50]
Claude Opus 4.7 (April 16, 2026, prior flagship) — AA-Omniscience index: 26 (second-highest overall at release, behind only Gemini 3.1 Pro's 33). Hallucination rate: 36% — the strongest calibration profile of any frontier model attempting questions at scale, and 50 percentage points better than GPT-5.5 on the same benchmark. BenchLM overall: 87. Long-context retrieval dropped to 32.2% (down from Opus 4.6's 78.3%) — Anthropic explicitly attributes this to the model now reporting errors when information is missing rather than fabricating an answer. The refusal strategy made measurable. Its data remains valid; Opus 4.8 has since taken the flagship slot. [58][63]
The pattern across Claude: by Opus 4.7 and 4.8, Anthropic's models were calibrated to refuse rather than guess, trading raw accuracy for some of the lowest hallucination rates on knowledge benchmarks. That still describes Opus 4.7 and 4.8 (42.3% and 39.3% on current records) and Sonnet 5 (39.4%). Fable 5 and Opus 5 are the deliberate exceptions: they answer more, know more, and hallucinate more (63.6% and 60.8%), and their September successors kept that profile (Fable 5.1 at 72.6%, Opus 5.5 at 58.6%). BullshitBench v2 tells the same story from a different angle — Opus 4.8 pushes back on a nonsense premise 95% of the time, Sonnet 4.6 91%, Fable 5 54%. For applications where a wrong answer is worse than no answer — legal research, medical consultation, compliance work — the Opus 4.8 refusal profile is structurally safer than any of the 5.x flagships. [94]
Gemini 4 Argon (announced September 30, 2026, not yet publicly available): Google is giving access to an initial group of cyber defenders first. AA-Omniscience (high): 49.9% accuracy, 15.1% hallucination, Index 42.4. That is the best calibration of any high-accuracy model in this table, and a clean break from the Gemini pattern below: against Gemini 3.1 Pro, 35.8 points less hallucination for 5 points less accuracy. [2]
Gemini 3.8 Flash (September 2, 2026): AA-Omniscience (high) 54.6% accuracy, 55.2% hallucination, Index 29.6. Against Gemini 3.7 Flash, 9.3 points less hallucination at nearly the same accuracy. [2]
Gemini 3.5 Flash-Lite: 29.5% accuracy, 34.4% hallucination, Index 5.2. Google's lightweight tier answers fewer questions correctly than the Flash models and guesses less often. [2]
Gemini 3.7 Flash (August 13, 2026) — Google's workhorse until 3.8 Flash, shipped three weeks after 3.6 Flash as a refinement rather than a new pretraining run. AA-Omniscience (August 2026 board): 55.3% accuracy, 64.5% hallucination, Index 26.5 — Gemini-typical: near the top on knowledge, weak on admitting gaps, though far better calibrated than Gemini 3 Flash's 93.0%. Google's launch post reports coding and agent benchmarks and no factuality figure. No Vectara score yet. On the 2026 FACTS board on Kaggle it scores 71.2, third behind GPT-6 Astra and GPT-6 Sol. [87][3][88]
Gemini 3.1 Pro Preview (February 2026) — AA-Omniscience index: 33 at launch, third on the August 2026 board behind Claude Fable 5 (43) and Claude Opus 5 (37), and still Google's best public model. Accuracy at launch: 55.3%. Hallucination rate: 50%, down from Gemini 3 Pro's 88% (54.9%, 50.9% and 91.5% on current records). This was the biggest single-update hallucination improvement until GPT-6 Astra in September 2026. Vectara new dataset: 10.4%. BullshitBench v2: 37% clear pushback, the lowest of the frontier flagships. [15][94]
Gemini 3 Pro — FACTS overall: 68.8 (highest in the December 2025 launch table). FACTS Search: 83.8. FACTS Parametric: 76.4. AA-Omniscience accuracy: 55.9% (highest) with 88% hallucination. The Gemini Paradox: most knowledgeable, least self-aware. [3]
Gemini 3 Flash (December 2025) — AA-Omniscience accuracy: 54.0% (highest of any model at launch). Hallucination rate: 91%. Speed: 218 tokens/s. The most extreme version of the Gemini Paradox — brilliant and unreliable in equal measure. Suitable only for tasks with external verification. The May 2026 successor, Gemini 3.5 Flash, addresses this directly. [16]
Gemini 3.5 Flash (May 18, 2026) — AA-Omniscience hallucination: 61%, down 31 percentage points from Gemini 3 Flash's 92%. That single generation cut the most extreme version of the Gemini Paradox by roughly a third and lifted the Omniscience Index 11 points. MMMU-Pro multimodal: 84%, the highest score recorded on that evaluation. Intelligence Index: 55. One caveat worth stating plainly: unlike Anthropic and OpenAI, Google has not published first-party hallucination data for this model — the 61% figure is independent benchmarking from Artificial Analysis, not a vendor disclosure. [64][66][67][68]
Google's models know the most but admit the least.
The pattern across Gemini: Gemini 3 Pro and 3 Flash attempted nearly every question, which gave them top accuracy scores but catastrophic hallucination rates when they hit their knowledge limits. The 3.1 Pro update showed this is addressable through calibration tuning — hallucination dropped 40.6 percentage points on current records (91.5% to 50.9%) for under one point of accuracy. Gemini 3.5 Pro was announced at Google I/O in May and is still unreleased as of August 27, 2026 after repeated delays, so no hallucination data exists for it. Since May, Google's public releases have been Flash-only: 3.5 Flash in May, 3.6 Flash in July, 3.7 Flash in August and 3.8 Flash in September. Gemini 4 Argon, announced September 30 and so far limited to an initial group of cyber defenders, breaks the pattern at 15.1% hallucination. [98]
Grok 4.7 (September 21, 2026): AA-Omniscience (xhigh) 47.4% accuracy, 29.3% hallucination, Index 32.0. The second release in a row in which xAI cut the rate: 5 points below Grok 4.6, for under one point of accuracy. Configurations differ: Artificial Analysis lists Grok 4.7 at xhigh and Grok 4.6 at high. Among public models that answer at least 45% of questions correctly, it is now the best calibrated in this table. [2]
Grok 4.6 (August 12, 2026) — xAI's flagship until Grok 4.7, $2/$6 per million tokens, 500K context, Intelligence Index 61 (tied with GPT-5.6 Sol max). AA-Omniscience (August 2026 board): 48.2% accuracy, 34.3% hallucination, Index 30.5, fourth on the August board. Against Grok 4.5 that is 20 points less hallucination for three points less accuracy. xAI's own model card points the other way: 1.7% on its internal factuality evaluation at high effort versus 0.98% for Grok 4.5, MASK-Rectified dishonesty 1.90% versus 0.67%. Internal and independent measurements disagree on direction, not just size. Strong candidate for the verification seat in a multi-model setup, still not a sole model for high-stakes factual work. [85][86][88]
Grok 4.5 (July 8, 2026) — released under the SpaceXAI brand. AA-Omniscience accuracy jumped to 52% (from Grok 4.3's 35%), but the hallucination rate more than doubled, from 25% to 54%. The Index still rose 8 points to 26 because accuracy climbed faster than the penalty. It ranked 4th on the Artificial Analysis Intelligence Index at 54 at launch. Pricing $2/$6 per million tokens, 500K context. A textbook case of buying knowledge at the cost of calibration — and, five weeks later, the baseline that Grok 4.6 corrected. xAI's model card for 4.6 gives 4.5 a 0.98% score on the internal factuality evaluation. [75][85]
Grok 4.3 (April 30, 2026) — now has a standalone AA-Omniscience profile in two configurations. High: 35% accuracy, 25% hallucination, Index 18.3. Medium: 16% hallucination, a lower-attempt build that edges the older Grok 4.20 Reasoning (17%) for the lowest-hallucination Grok. The page's earlier derived "~49% / ~26%" estimate has been replaced by these standalone figures. API pricing $1.25/$2.50 per million tokens. [69]
Grok 4 — Vectara old dataset: 4.8%. AA-Omniscience: 41.4% accuracy, 64% hallucination, positive index. FACTS: 53.6 (Search: 75.3, Multimodal: 25.7). Domain leader in Health and Science on AA-Omniscience. [2]
Grok 4.1 Fast — xAI claims 65% hallucination reduction (12.09% to 4.22% on internal benchmarks). AA-Omniscience tells a different story: 72% hallucination rate, worse than Grok 4's 64%. Sycophancy also increased (MASK benchmark: 0.07 to 0.19-0.23). [17]
Grok-3 — Columbia Journalism Review: 94% citation hallucination rate. By far the worst score on this benchmark. [6]
The pattern across Grok: internal benchmarks and independent benchmarks disagree sharply, and with Grok 4.6 they disagree on direction. AA-Omniscience says 4.6 cut hallucination to 34.3% (down from 4.5's 54%), and 4.7 cut it again to 29.3%. xAI's own factuality evaluation says 4.6 got slightly worse (1.7% versus 0.98%). Grok 4.5 remains the textbook case of buying knowledge at the cost of calibration — more knowledgeable than Grok 4.3 and hallucinating more than twice as often. The 94% CJR citation hallucination rate is not from an older model — Grok-3 was tested in March 2025. Domain-specific value exists in Health and Science, and the calibration of 4.6 and 4.7 makes them stronger second voices than any Grok before them. The gap between vendor and independent numbers still makes Grok risky as a sole model for any high-stakes application.
Sonar Reasoning Pro — Search Arena score: 1136, statistically tied with Gemini 2.5 Pro for #1. SimpleQA F-score: 0.858, the highest of any model at time of testing. CJR citation accuracy: 37% hallucination (best tested). Response accuracy: >90% for factual queries (94% overall, 95% academic, 94% technical). [18][19]
Sonar Pro — Built on Llama 3.3 70B, fine-tuned for search factuality. SimpleQA F-score: 0.858. Outperforms GPT-4o and Claude 3.5 Sonnet on factuality benchmarks. [19]
The Perplexity risk: Perplexity introduces a failure mode no other model shares. It cites real URLs with fabricated claims. The sources look legitimate — real websites, real publication names — but the information attributed to those sources may be invented. This makes Perplexity hallucinations harder to detect than hallucinations from models that don't present external citations. A 37% citation hallucination rate means more than one in three source attributions may contain fabricated content. [51]
DeepSeek V4.1 Flash: the highest hallucination rate in this table, 96.5% at 46.4% accuracy (max), Index -5.3. Against V4 Flash, accuracy rose almost 10 points and the hallucination rate barely moved. [2]
DeepSeek V4 Pro and V4 Flash (preview April 24, 2026) — a cautionary data point. The V4 Pro preview posts a 94% AA-Omniscience hallucination rate; V4 Flash hits 96% — among the highest ever recorded on the benchmark, in the same territory as early Gemini 3 Flash (92%) and Llama 4 Maverick (87.6%). V4 Pro's preview Omniscience Index of -23 sits broadly in line with V3.2: strong coding performance paired with near-total overconfidence on knowledge questions. Vectara new dataset: 8.6% for V4 Pro. [70][1]
DeepSeek V4 Pro 0813 (general availability August 13, 2026) — the GA build that took V4 Pro out of preview. AA-Omniscience (August 2026 board): 49.1% accuracy, 94.1% hallucination, Index 0.8. Accuracy went up and the hallucination rate did not move at all, which is why the Index crossed from -23 to about zero: DeepSeek added knowledge without adding any willingness to say "I don't know". The two builds are scored separately on this page because the checkpoints differ. [92][88]
DeepSeek-V3 — Vectara old dataset: 3.9%. A strong performer on grounded summarization.
DeepSeek-R1 — Vectara old dataset: 14.3%, nearly 4x higher than V3. AA-Omniscience hallucination: 83%. Vectara analysis found R1 produces 71.7% "benign hallucinations" (plausible-sounding additions) vs V3's 36.8%. [49][48]
The pattern: DeepSeek's reasoning model (R1) hallucinates dramatically more than its base model (V3). This is the reasoning tax in its most extreme form. The gap (3.9% vs 14.3%) makes it one of the clearest examples that reasoning capabilities and factual reliability don't move in the same direction.
Qwen3.8 Max (0902) (Alibaba, September 2, 2026): 31.7% accuracy, 28.8% hallucination, Index 12.0. The September build pulled the hallucination rate back down from the preview's 41.7% at the same accuracy, close to the abstention-first profile of Qwen3.7 Max. [2]
Muse Spark 1.3 (Meta, September 2, 2026): 43.6% accuracy, 32.9% hallucination, Index 25.0 at max. Close to Muse Spark 1.2 (xhigh) on calibration, 1.8 points lower on accuracy. [2]
Kimi K3 (Moonshot AI, July 2026, open weights released July 27) — a 2.8-trillion-parameter open-weights MoE model with a 1M-token context window, the first open model in the 3T class. AA-Omniscience: 46% accuracy, 51% hallucination, Index 18 at launch (47.6% / 53.2% / 19.7 on the August re-pull). Like Grok 4.5, its accuracy gain over the prior generation came with a calibration regression. Ranks among the top open-weight models on the Artificial Analysis Intelligence Index. [76][93]
Command A+ (Cohere, open weights, ~May 20, 2026) — the lowest hallucination rate of any capable model at 14%, reached by refusing most questions it can't verify (9% accuracy, Index -4). A "knows-its-limits" archetype similar to Claude 4.5 Haiku, useful as a verification layer in a multi-model pipeline. [77]
Qwen3.7 Max (Alibaba, ~May 20, 2026) — the most aggressive abstention policy of any tracked model. 30% accuracy, 23% hallucination, Index 14, with a 1M-token context window. Refuses whenever its internal confidence threshold isn't met, which makes it another strong verification-layer candidate. [78]
Qwen3.8 Max Preview (Alibaba, August 3, 2026) — a 2.4-trillion-parameter MoE flagship with open weights promised. AA-Omniscience (August 2026 board): 31.9% accuracy, 41.7% hallucination, Index 3.4. Accuracy barely moved from Qwen3.7 Max, and the hallucination rate nearly doubled: Alibaba loosened the abstention policy that made 3.7 Max a verification-layer candidate, and got almost no knowledge in return. The clearest recent example of calibration being a training choice, not a capability. [90][88]
GLM-5.3 (Z.ai, August 14, 2026) — a coding and cyber-security flagship built on the GLM-5.2 base without retraining. AA-Omniscience (August 2026 board): 33.9% accuracy, 29.6% hallucination, Index 14.3 — the best-calibrated new open-weight model of the summer, in the Qwen3.7 Max and Grok 4.3 band. [91][88]
Llama 4 Maverick (Meta) — Vectara old dataset: 4.6% (competitive). AA-Omniscience hallucination: 87.6% (catastrophic). The gap between grounded summarization and open-ended knowledge is wider for open-source models than for any proprietary family. [2]
Open-source models exceeded 80% hallucination rates in medical scenarios in MedRxiv testing. For critical applications, the hallucination gap between open-source and proprietary frontier models remains large. [40]
Muse Spark 1.1 (Meta, July 9, 2026) — carries an AA-Omniscience profile, not just a HealthBench score. July launch configuration: Index 18 (up from Muse Spark 1.0's 4), accuracy 41% (roughly flat), hallucination 38% (down from 73%). The entire gain came from abstention: attempt rate dropped from 95% to 82%. It is the clearest recent example of a model getting more reliable by learning when to stay silent rather than by learning more. The August board also lists a reasoning configuration of 1.1 at 52.1% accuracy / 50.0% hallucination / Index 28.1 — more knowledge, and the abstention discipline gone. HealthBench Professional: 59.3%. Its HealthBench Hard leadership (42.8) belongs to the original Muse Spark; a 1.1-specific Hard score is not yet confirmed. [71][88]
Muse Spark 1.2 (Meta, August 5, 2026) — a coding-focused update to 1.1, co-trained with Meta's Muse Code agent. AA-Omniscience (August 2026 board, xhigh configuration): 45.4% accuracy, 33.3% hallucination, Index 27.2. Set against the reasoning configuration of 1.1 that is a 17-point cut in hallucination for seven points of accuracy — the second 2026 release, after Grok 4.6, to move calibration the right way. Meta's launch post reports coding benchmarks only and no factuality figure. [89][88]
The model profiles in Section 6 show individual performance. This section answers the questions people actually search for: "Is Claude or GPT more accurate?" "Should I use Gemini or Claude?" The answer is always "it depends on what you're doing" — but the data makes the tradeoffs specific.
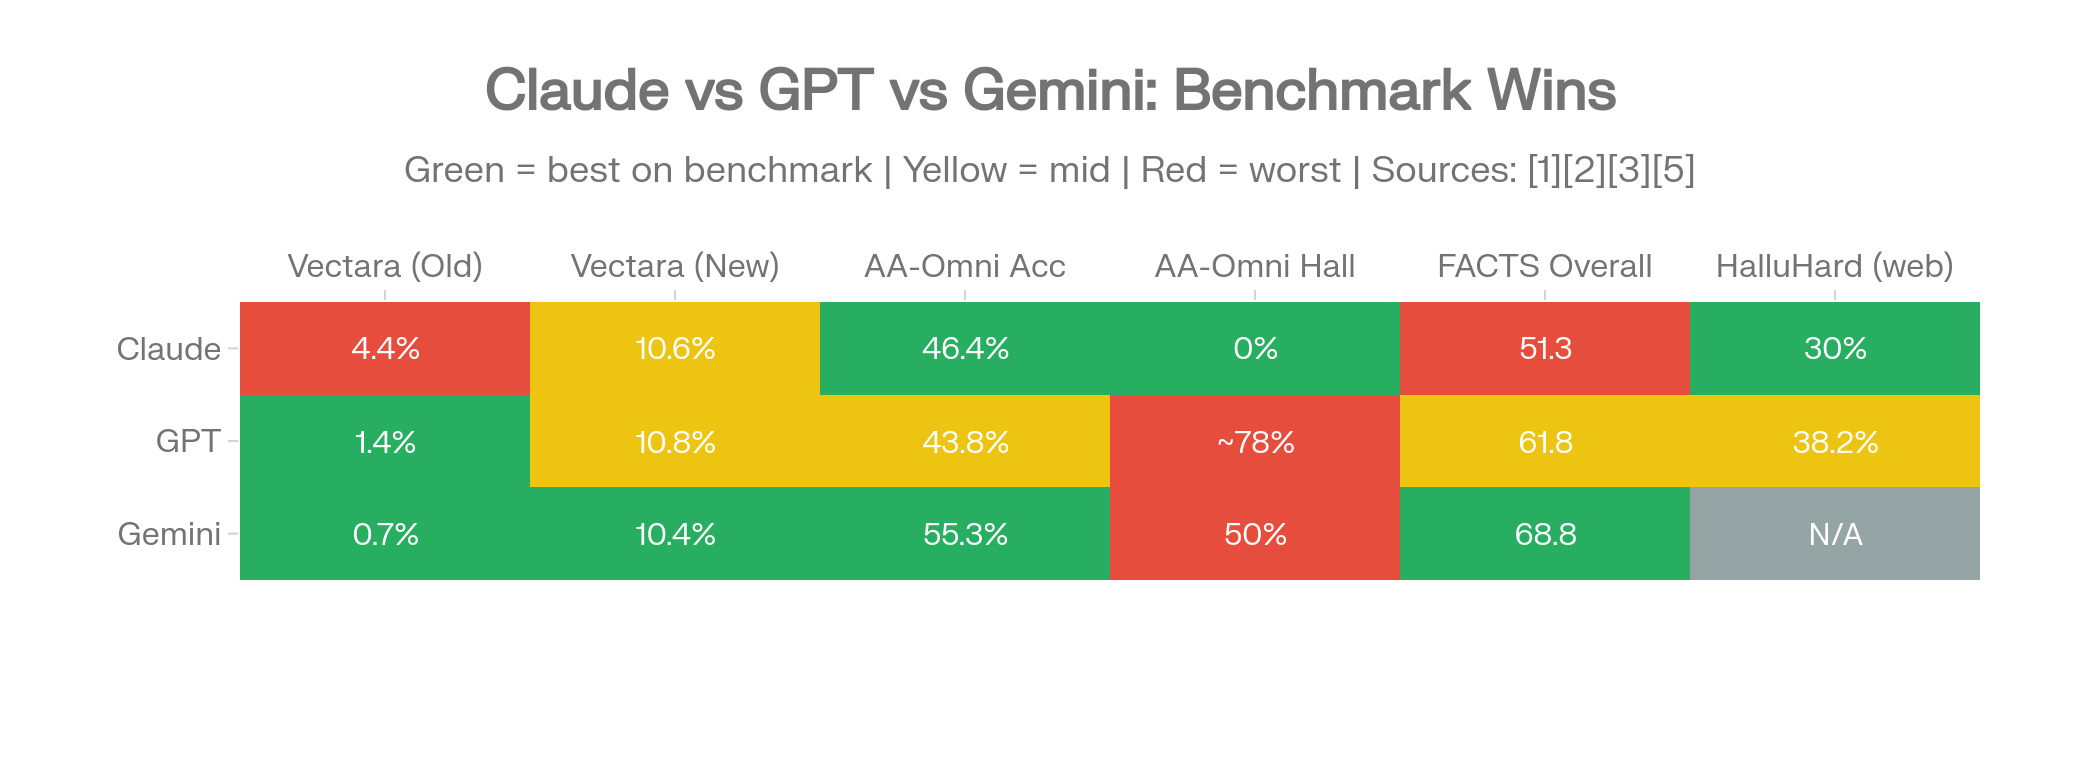
Head-to-head comparison heatmap: which provider wins on which benchmark. Green = winner, yellow = tied, red = loser.
The most searched comparison in AI, and the most context-dependent. As of August 2026 both providers field an accuracy-first flagship — Claude Fable 5 (65% AA-Omniscience accuracy, 63.6% hallucination) and GPT-5.6 Sol (59.4%, 92.2%). Neither is the low-hallucination choice, but the gap between them on calibration is now 29 points.
October 2026 update: the September releases flipped the calibration gap between the two flagships. GPT-6 Astra reads 62.6% accuracy and 51.3% hallucination, below both Claude Opus 5.5 (66.2%, 58.6%) and Claude Fable 5.1 (67.2%, 72.6%). The table below keeps the August flagships. Current figures for every model are in the cross-benchmark table at the top of the page.
| Benchmark | Claude | GPT | Winner |
|---|---|---|---|
| AA-Omniscience Accuracy (flagship) | 65% (Fable 5) | 59.4% (GPT-5.6 Sol) | Claude |
| AA-Omniscience Index (flagship) | 43 (Fable 5) | 22.0 (GPT-5.6 Sol) | Claude |
| AA-Omniscience Hallucination (flagship) | 63.6% (Fable 5) | 92.2% (GPT-5.6 Sol) | Claude (both poor) |
| Vectara (old dataset) | 4.2% (Opus 4.1) | 1.4% (GPT-5) | GPT |
| Vectara (new dataset) | 9.8% (Haiku 4.5) | 3.1% (GPT-5.4 nano) | GPT |
| AA-Omniscience Hallucination (best config) | 0% (Claude 4.1 Opus, Nov 2025 snapshot) | ~78% (GPT-5.2) | Claude |
| AA-Omniscience Accuracy (prior generation) | 46.6% (Opus 4.8) | 43.8% (GPT-5.2) | Claude (slight) |
| FACTS Overall | 51.3 (Opus 4.5) | 61.8 (GPT-5) | GPT |
| HealthBench | – | 1.6% (GPT-5 thinking) | GPT |
| HalluHard (with web) | 30.2% (Opus 4.5) | 27.2% (GPT-6 Astra) | GPT |
Sources: HealthBench [52], HalluHard [5], FACTS [3], Vectara [1], AA-Omniscience [2]
The pattern isn't "one is better." It's two different philosophies measured on different scales.
GPT models are stronger when the task has source material to work from. Summarization, document analysis, RAG pipelines, search-grounded Q&A — GPT sticks closer to provided text and scores well on faithfulness benchmarks. The FACTS advantage (61.8 vs 51.3) reflects this: GPT-5 handles grounding and search tasks with higher accuracy.
Claude models are stronger when the task requires the model to know its own limits. On AA-Omniscience, Claude 4.1 Opus achieved a 0% hallucination rate in the launch snapshot by refusing to answer questions it couldn't verify. Claude Opus 4.8's 35.9% is well under half of GPT-5.6 Sol's 92.2% on the same benchmark, and even Claude's answer-everything flagship, Fable 5, fabricates 29 points less often than Sol. On HalluHard's realistic conversation test, Claude Opus 4.5 with web search hit 30.2%, the lowest of any Claude model and second only to GPT-6 Astra (27.2%).
The practical split: Use GPT for document-grounded workflows where the source material is available and complete. Use Claude for advisory workflows where the model must draw on its own knowledge and flag uncertainty — and note this describes Opus 4.8 and Sonnet 5, not the Fable and Opus 5.x models, which now hallucinate more than GPT-6 Astra. This isn't brand preference — it's what the benchmark data supports.
One more variable that often gets overlooked: web search access changes GPT's performance dramatically. GPT-5 drops from 47% hallucination to 9.6% with browsing. Without web access, the Claude-GPT comparison shifts in Claude's favor on open-ended factual tasks. With web access, GPT pulls ahead.
| Benchmark | Claude | Gemini | Winner |
|---|---|---|---|
| AA-Omniscience Index | 43 (Fable 5) | 33 (3.1 Pro) | Claude |
| AA-Omniscience Accuracy | 65% (Fable 5) | 55.3% (3.1 Pro) | Claude |
| AA-Omniscience Hallucination (flagship) | 63.6% (Fable 5) | 50% (3.1 Pro) | Gemini |
| AA-Omniscience Hallucination (best config) | 0% (Claude 4.1 Opus, Nov 2025 snapshot) | 50% (3.1 Pro) | Claude |
| FACTS Overall | 51.3 (Opus 4.5) | 68.8 (3 Pro) | Gemini |
| Vectara (old dataset) | 4.2% (Opus 4.1) | 0.7% (2.0-Flash) | Gemini |
| Vectara (new dataset) | 10.6% (Sonnet 4.6) | 10.4% (3.1 Pro) | Tied |
| HalluHard (with web) | 30.2% (Opus 4.5) | – | Claude |
Sources: HalluHard [5], FACTS [3], Vectara [1], AA-Omniscience [2]
For eighteen months the shorthand was "Gemini knows more, Claude is more honest about what it doesn't know." Claude Fable 5 rewrote the first half. Claude Opus 5 then complicated the second.
Fable 5 leads Gemini 3.1 Pro on both AA-Omniscience Index (43 vs 33) and accuracy (65% vs 55.3%), and Opus 5 (37) has pushed Gemini's best model to third. Gemini still leads on FACTS (68.8) and on Vectara summarization. The honesty split holds where it always did: Claude 4.1 Opus fabricated 0% of the time when it should refuse in the launch snapshot, Opus 4.8 does so 35.9% of the time, Gemini 3.1 Pro 50%. But Anthropic's two 2026 flagships are now worse than Gemini on that measure: Fable 5 hallucinates 63.6%, Opus 5 60.8%. The "more honest" half of the shorthand now applies to the Opus 4.x line and Sonnet 5 specifically, not to Claude as a whole.
The problem is still what happens when the model doesn't have the answer. Even after the 3.1 calibration update that cut hallucination from 88% to 50%, Gemini fabricates an answer half the time when it should say "I don't know." Gemini 3.7 Flash, Google's August workhorse, does so 64.5% of the time.
The practical split: Gemini for breadth-of-knowledge tasks where external verification exists — research, comparative analysis, information gathering. Claude Opus 4.8 for depth-of-trust tasks where a fabricated answer has consequences — compliance reviews, legal research, medical consultation. Fable 5 and Opus 5 sit with the breadth-of-knowledge group, not the depth-of-trust group. If you can check the work, breadth wins; if you can't, use Opus 4.8.
| Benchmark | GPT | Gemini | Winner |
|---|---|---|---|
| Vectara (old dataset) | 0.8% (o3-mini) | 0.7% (2.0-Flash) | Tied |
| Vectara (new dataset) | 3.1% (GPT-5.4 nano) | 3.3% (2.5-Flash-Lite) | GPT (slight) |
| FACTS Overall | 61.8 (GPT-5) | 68.8 (3 Pro) | Gemini |
| FACTS Search | 77.7 (GPT-5) | 83.8 (3 Pro) | Gemini |
| AA-Omniscience Accuracy | 59.4% (GPT-5.6 Sol) | 55.3% (3.1 Pro) | GPT |
| AA-Omniscience Hallucination (flagship) | 92.2% (GPT-5.6 Sol) | 50% (3.1 Pro) | Gemini |
| AA-Omniscience Index (flagship) | 22.0 (GPT-5.6 Sol) | 33 (3.1 Pro) | Gemini |
| HealthBench | 1.6% (GPT-5 thinking) | – | GPT |
Sources: FACTS [3], Vectara [1], AA-Omniscience [2][88]
Gemini leads on FACTS and, since GPT-5.6 Sol's hallucination rate was published, on knowledge reliability: Gemini 3.1 Pro fabricates half the time when it doesn't know, Sol more than nine times in ten. GPT's accuracy edge grew with Sol (59.4% on AA-Omniscience), and its advantage stays task-specific: medical applications (1.6% HealthBench), production claim-level accuracy with thinking mode, the best frontier-lab score on Vectara's new dataset (GPT-5.4 nano, 3.1%), and the sheer volume of internal evaluation data OpenAI publishes.
The practical split: Both are strong with tool access. Without it, Gemini's higher parametric knowledge (FACTS Parametric: 76.4) gives it an edge on stored-knowledge tasks. GPT's thinking mode gives it a specific advantage for medical and health-related queries where reasoning reduces hallucination dramatically.
| Benchmark | Grok | Field Average |
|---|---|---|
| xAI internal factuality | 1.7% (Grok 4.6), 0.98% (Grok 4.5), 4.22% (Grok 4.1) | – |
| AA-Omniscience (newest, Aug 2026) | 34.3% hallucination (Grok 4.6) | Best of the 2026 flagships |
| AA-Omniscience (July 2026) | 54% hallucination (Grok 4.5) | ~55% average |
| AA-Omniscience (best config) | 16% hallucination (Grok 4.3 medium) | Better than most |
| AA-Omniscience | 64% hallucination (Grok 4) | ~60% average |
| AA-Omniscience (Fast variant) | 72% hallucination (Grok 4.1 Fast) | Worse than base |
| FACTS Overall | 53.6 (Grok 4) | ~52 average |
| FACTS Search | 75.3 (Grok 4) | Competitive |
| FACTS Multimodal | 25.7 (Grok 4) | Far below avg |
| CJR Citation | 94% hallucination (Grok-3) | Worst tested |
| Vectara (new dataset) | 20.2% (Grok-4-fast) | Near the bottom of the board |
Sources: Grok 4.1 [17], Grok 4.6 model card [85], CJR [6], FACTS [3], AA-Omniscience [2][88]
xAI's internal numbers and the independent ones have never agreed on size. With Grok 4.6 they stopped agreeing on direction. AA-Omniscience says 4.6 is the best-calibrated Grok yet: 34.3% hallucination at 48.2% accuracy, against 54% at 52% for Grok 4.5 five weeks earlier. xAI's own model card says 4.6 got slightly worse on its internal factuality evaluation (1.7% versus 0.98%). Both can be true, because they measure different things on different scales. The older Grok 4.3 medium build still holds the lowest-hallucination Grok spot at 16%. The CJR citation study found Grok-3 hallucinated 94% of the time on news source attribution.
Grok does have genuine domain strengths — it led Health and Science categories in the AA-Omniscience launch analysis. But the gap between xAI's claims and independent measurements is wider than for any other provider.
The practical takeaway: Don't use Grok as a sole model for high-stakes decisions. Its value is as one voice in a multi-model evaluation where its domain strengths (health, science) can contribute while its inconsistencies get caught by other models. Grok 4.6's calibration makes it the strongest Grok yet for that second-voice role.
| Benchmark | Perplexity | ChatGPT | Claude |
|---|---|---|---|
| CJR Citation Accuracy | 37% hallucination | 67% hallucination | – |
| SimpleQA F-score | 0.858 (best) | 0.38 (GPT-4o) | 0.35 (Sonnet 3.5) |
| Search Arena Ranking | #1 (tied) | – | – |
| Response Accuracy | >90% factual | – | – |
Sources: Perplexity Sonar [18][19], CJR [6]
Perplexity wins on factual search queries. Its RAG-native architecture, built around retrieval rather than parametric knowledge, gives it a structural advantage for questions with verifiable answers.
The catch: Perplexity cites real URLs with fabricated claims. The sources look legitimate — real websites, real publication names — but the information attributed to those sources may be invented. At a 37% citation hallucination rate, more than one in three source attributions could contain fabricated content. This makes Perplexity hallucinations harder to spot than hallucinations from models that don't present external citations.
The practical split: Perplexity for initial research and fact-finding where you'll verify key claims. Not for final-answer scenarios where someone reads the cited source and assumes the attribution is accurate.
Hallucination rates vary dramatically by subject matter. A model that looks reliable on general-knowledge benchmarks can be dangerously wrong on legal or medical questions — and the domain with the strongest primary research is law.
Stanford RegLab and Stanford HAI tested the paid, retrieval-grounded legal research tools marketed as "hallucination-free" — Magesh, Surani, Dahl, Suzgun, Manning and Ho, published in the Journal of Empirical Legal Studies (2025). The purpose-built tools still produced incorrect or misgrounded answers on between 17% and 33% of queries — more than one in six at the low end, one in three at the high end. (Stanford HAI's summary of the same study rounds the Westlaw figure to "more than 34%".) General-purpose chatbots on specific legal queries did far worse: Dahl, Magesh, Suzgun and Ho found hallucination rates from 58% (GPT-4) to 88% (Llama 2) in the Journal of Legal Analysis (2024). Both are 2024 test results for the product versions tested then, not present-day product rates. Domain-specific reliability claims deserve domain-specific verification. [36][96][97]
AI hallucinations in legal filings are accelerating despite growing awareness.
Court cases involving AI hallucinations grew from 10 documented rulings in 2023 to 37 in 2024 to 73 in just the first five months of 2025. As of October 5, 2026, that trajectory has accelerated sharply: legal researcher Damien Charlotin's live database documents 2,149 cases globally, with 1,473 in U.S. courts. The 2026 climb is steep: roughly 719 cases in January, 1,227 by early April, 1,598 on June 9, 1,769 by July 17, 1,963 by August 27 and 2,149 by October 5, close to five new decisions a day since June. On March 31, 2026, ten separate courts ruled on AI hallucination incidents in a single day. The database is updated continuously, so the count on any given day will be higher than the one printed here. [38][37][59]
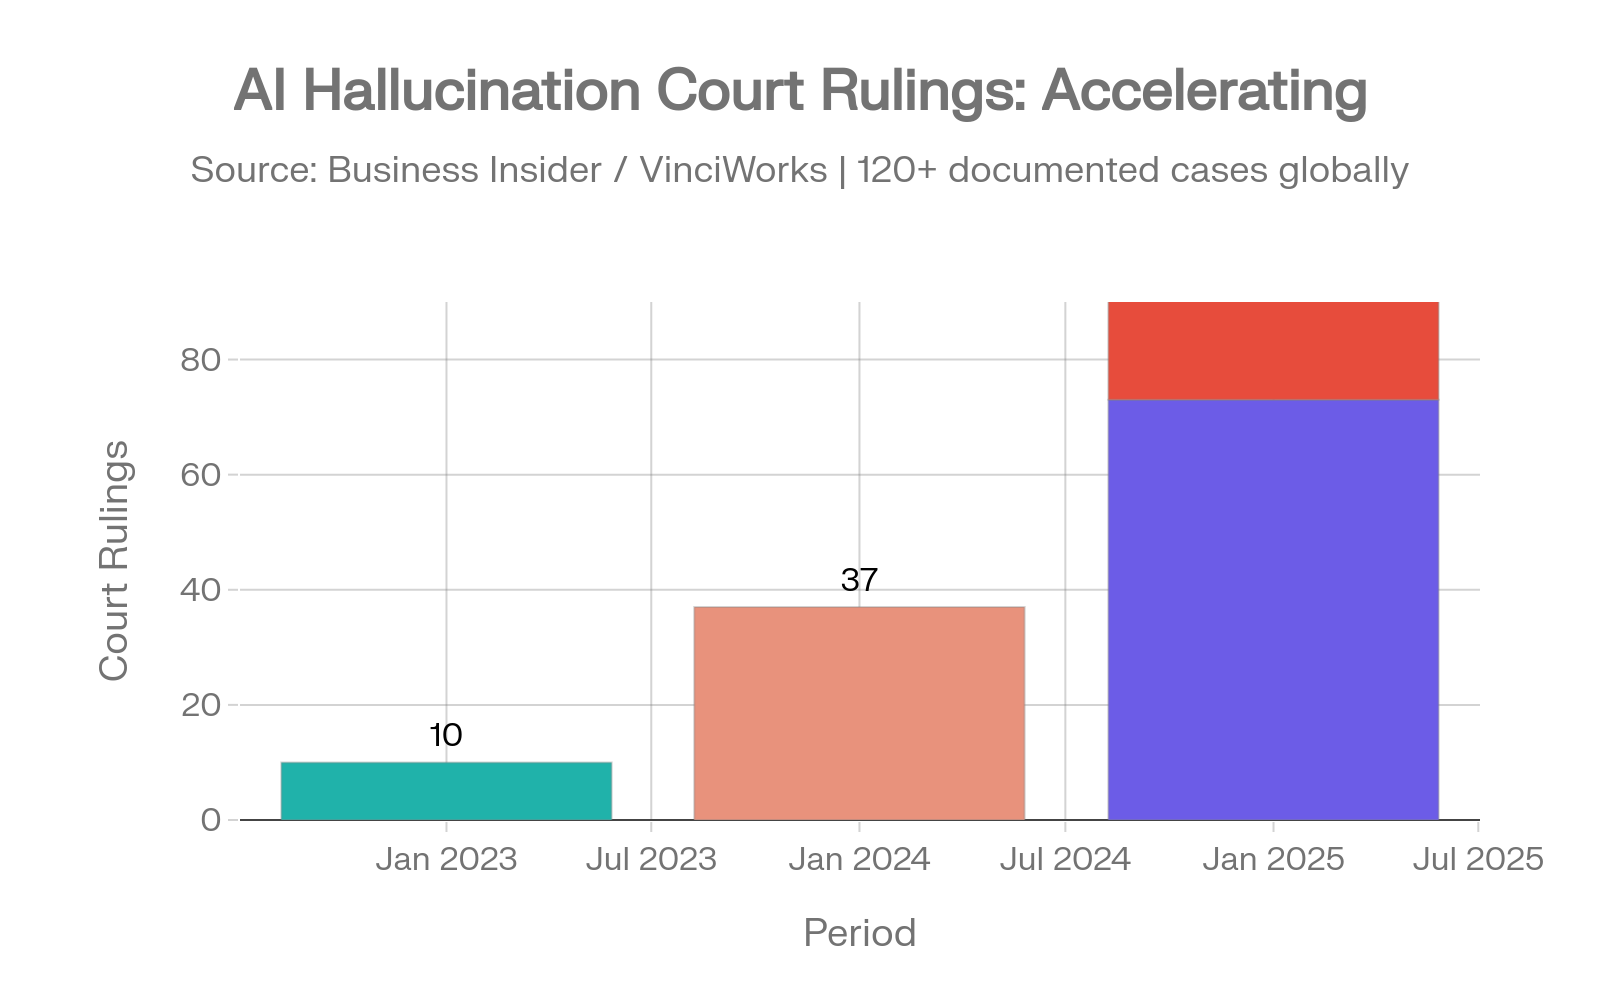
Legal AI hallucination incidents over the period charted: 10 (2023) → 37 (2024) → 73 (first five months of 2025). The Charlotin database has since reached 2,149 cases as of October 5, 2026 - chart refresh pending. Sources: Business Insider [38], Charlotin [37]
The problem is no longer amateur. In 2023, most hallucination cases involved self-represented litigants. By May 2025, 13 of 23 caught cases were from practicing lawyers. Morgan & Morgan, one of America's largest personal injury firms, sent an urgent warning to 1,000+ attorneys after sanctions threats for AI-generated citations. The pace of penalties has escalated: Q1 2026 sanctions totaled at least $145,000 — the highest quarterly total in legal history. The single largest penalty on record, $109,700 against an Oregon attorney, was issued in early 2026. The Fourth Circuit publicly admonished a lawyer in April 2026 for filing briefs containing AI-generated false citations. Despite record sanctions, the rate of incidents continues to rise. [59]
The underlying benchmark data explains why. Stanford RegLab and the Stanford Human-Centered AI Institute found that general-purpose LLMs hallucinated between 58% and 88% on specific legal queries. On questions about a court's core ruling, models hallucinated at least 75% of the time. Even purpose-built legal AI tools fail: Lexis+ AI produced incorrect information more than 17% of the time, and Westlaw AI-Assisted Research about 33%. [36][96][97]
ECRI, the global healthcare safety nonprofit, listed AI risks as the #1 health technology hazard for 2025. The numbers back up the concern. [39]
The FDA has authorized 1,357 AI-enhanced medical devices — double the figure from end of 2022. Of those, 60 devices were involved in 182 recalls, with 43% of recalls occurring within the first year of approval. [42]
A 2025 MedRxiv study measured hallucination rates on clinical case summaries: 64.1% without mitigation prompts, dropping to 43.1% with mitigation (a 33% improvement). GPT-4o performed best in this study, dropping from 53% to 23% with structured mitigation. Open-source models exceeded 80% hallucination in medical scenarios. [40]
The bright spot: GPT-5 with thinking mode achieved 1.6% hallucination on HealthBench, compared to GPT-4o at 15.8%. For medical applications specifically, reasoning-enabled frontier models with thinking mode active show a dramatic improvement over previous generations. [41][52]
HealthBench Professional (April 2026): OpenAI launched a new clinician-grade benchmark on April 22, 2026, alongside the release of "ChatGPT for Clinicians." Unlike the original HealthBench (synthetic conversations), HealthBench Professional uses real clinical scenarios across consultation, documentation, and research tasks. On HealthBench Hard, the new benchmark's most challenging slice, scores diverge sharply: Muse Spark leads at 42.8, GPT-5.4 (powering ChatGPT for Clinicians) scores 40.1, Gemini 3.1 Pro scores 20.6, Grok 4.2 scores 20.3, and Claude Sonnet 4.6 scores 14.8. The benchmark's designers report that GPT-5.4-powered responses outperform physician-written responses on the consultation slice, though the methodology is still under independent review. [60]
July 2026 update: two of the newest models post scores on the Professional slice rather than Hard - GPT-5.6 Sol at 60.5 and Muse Spark 1.1 at 59.3. The 42.8 Hard leadership above belongs to the original Muse Spark; a 1.1-specific Hard score has not been published, so the two should not be read as the same measurement. [71][73]
Financial AI hallucinations don't make headlines the way legal ones do. There is no court docket for a wrong number in a model, which is also why the domain has the thinnest primary data on this page.
What can be sourced: EY's 2025 Responsible AI Pulse puts the average loss from AI-related incidents at $4.4 million per affected organization (n=975 C-suite), a figure that covers AI risk broadly, not hallucination alone. [79] The Stanford AI Index 2026 sycophancy benchmark shows single models agreeing with a user's false premise up to 94% of the time — the failure mode that matters most when the premise is a valuation assumption. [58]
The strongest financial signal is first-party. In the Suprmind Multi-Model Divergence Index, financial questions produced disagreement between models on 72.1% of turns (258 turns), the highest rate of any of the ten domains tracked and well above legal (41.2%) or medical (33.9%). Where the stakes are a portfolio, one model's confident answer is the answer most likely to be contradicted by another. [61]
A set of widely circulated finance figures — a 15-25% hallucination rate on financial tasks, 2.3 significant errors per quarter, $50,000 to $2.1 million per incident, a 20.0% versus 76.7% literature-reference comparison, and a $12.7 million SEC total — appeared in earlier versions of this page. None could be traced to a primary study, so they were removed in the August 27, 2026 revision, on the same rule that removed the untraceable business-impact figures on August 8.
$4.4 million — Average reported loss per organization from AI-related incidents, conservatively estimated. EY Responsible AI Pulse, October 2025 (n=975 C-suite). [79]
51% of organizations reported negative consequences from generative AI use. McKinsey State of AI, November 2025 (n=1,993). [80]
82% of AI bugs in production systems stem from hallucinations and accuracy failures. [34]
4.5 hours per week — Time professionals spend fixing or redoing AI-generated output. Zapier, January 2026 (n=1,100). [81]
39% of customer service chatbots required rework due to hallucination-related failures. [34]
91% of enterprise AI policies now include hallucination-specific protocols. [31]
64% of healthcare organizations delayed AI adoption specifically because of hallucination concerns. [31]
53+ papers accepted at NeurIPS 2025 — one of AI's most prestigious conferences — contained AI-hallucinated citations that survived 3+ peer reviewers. NeurIPS acceptance rate is 24.52%, meaning these hallucinated papers beat 15,000+ competing submissions. [45]
A February 2026 follow-up analyzed 100 of those fabricated citations across the 53 papers (about 1% of the accepted program, each reviewed by three to five experts). 66% were total fabrications, 27% were real papers with corrupted attributes such as wrong authors or venues, 4% hijacked a real identifier. Every one of the 100 combined at least two failure modes — a fabricated title attached to a plausible venue, or a real DOI pointing at an invented paper — which is what let them pass. [95]
When hallucinated citations pass peer review at the field's top venue, the verification problem extends beyond enterprise into the foundations of AI research itself.
Stanford's Human-Centered AI Institute published its 2026 AI Index Report on April 13, 2026 — a 423-page annual review covering responsible AI, deployment, governance, and benchmarks. Three findings concern hallucinations directly. [58]
362 documented AI incidents in 2025 — up from 233 in 2024, a 55% year-over-year increase and the highest annual count in the AI Incident Database's history. [58]
Sycophancy-induced hallucination: 22% to 94% across 26 frontier models. The report introduces a new accuracy benchmark testing how models respond to false statements presented two ways: as something a third party believes (models handle this well) and as something the user themselves believes (models collapse). GPT-4o's accuracy fell from 98.2% to 64.4%; DeepSeek R1 fell from over 90% to 14.4%. The 22%-94% range applies specifically to this user-attributed-false-belief framing. The best model still produces false outputs 22% of the time when a user implies a false belief; the worst hallucinates 94% under those conditions. This is a fundamentally different failure mode from summarization or knowledge benchmarks: the model agrees with the user even when the user is wrong. [58]
88% organizational AI adoption (McKinsey, 2026). Stanford's 2026 AI Index reports organizational AI adoption rose to 88% of surveyed organizations in 2025, sourced to the McKinsey State of AI 2025 survey (generative AI used in at least one business function at 70% of organizations). Adoption has now reached the level where AI errors compound at scale. AI governance roles grew 17% in 2025, and the share of businesses with no responsible AI policies fell from 24% to 11% — but Foundation Model Transparency scores dropped back from 58 to 40, with major gaps in disclosures around training data, compute resources, and post-deployment impact.
See how multi-model validation works — test it with a real question where accuracy matters.
Try Multi-Model ValidationOne of the most counterintuitive findings in 2025-2026 hallucination research: the AI models marketed as most intelligent are often the least reliable on basic factual tasks.
Reasoning models — GPT-5 with thinking, Claude with extended thinking, DeepSeek-R1 — use chain-of-thought processes that dramatically improve performance on complex problems. They're measurably better at math, logic, multi-step analysis, and medical diagnosis.
They're also measurably worse at sticking to facts they've been given.
Vectara new dataset: At its November 2025 launch, the thinking models Vectara named, including GPT-5, Claude Sonnet 4.5 and Grok-4, all exceeded 10% hallucination, and Gemini-3-Pro read 13.6%. Grok-4-fast-reasoning reads 20.2% on the current board. Non-reasoning models like Gemini-2.5-Flash-Lite scored 3.3%. OpenAI's GPT-6 models have narrowed the gap since, at 6.5% for GPT-6 Sol and 8.7% for GPT-6 Astra. [102][1]
DeepSeek: R1 (reasoning) hallucinates at 14.3% on Vectara vs V3 (base) at 3.9%. Nearly a 4x difference from the same provider. Vectara analysis found R1 produces 71.7% "benign hallucinations" (plausible-sounding additions) compared to V3's 36.8%. [48][49]
DeepSeek V4 (April 2026): The pattern held at a greater extreme. V4 Pro and V4 Flash post AA-Omniscience hallucination rates of 94% and 96% — among the highest ever recorded — while ranking near the top of open-weights models for coding and agentic work. Strong capability, almost no calibration. [70]
PersonQA regression: OpenAI's o3 hallucinates 33% on questions about real people vs o1's 16%. The o4-mini is worse at 48%. These are newer, more capable models performing worse on a basic factual test. [53][54]
GPT-5 thinking mode: HealthBench hallucination drops to 1.6% (excellent). But on Vectara's new dataset, GPT-5 (high) reads 15.1% (poor). Same model, same thinking mode, opposite results depending on the task.
GPT-5.5 (April 2026): AA-Omniscience accuracy of 57% — a record at the time — paired with an 86% hallucination rate. Knowledge expansion appears to have outpaced calibration improvements at the frontier. Claude Opus 4.7 takes the opposite trade: 36% hallucination at lower raw accuracy. [2][58][63]
The 2026 flagships: the pattern moved to the very top of the leaderboard. Claude Fable 5 (65% accuracy / 63.6% hallucination), Claude Opus 5 (61% / 60.8%, up from Opus 4.8's 39.3%), GPT-5.6 Sol (59.4% / 92.2%, the highest rate of any OpenAI flagship), Grok 4.5 (51.6% / 54.1%, doubled from Grok 4.3), and Kimi K3 (47.6% / 53.2%) all raised accuracy and raised hallucination in the same release. The most capable models shipped in 2026 are among the most overconfident. Before September, counterexamples included Gemini 3.1 Pro (February 2026), which cut Gemini 3 Pro's rate from 91.5% to 50.9%, and Grok 4.6 (August 2026): 48.2% accuracy and 34.3% hallucination, a 20-point calibration gain for a three-point accuracy cost. It proves the trade is a choice, not a law. September's releases split the field: GPT-6 Astra cut OpenAI's rate to 51.3% while gaining accuracy (62.6%), Grok 4.7 cut xAI's again to 29.3%, and Gemini 4 Argon reads 15.1% (not yet publicly available), while Claude Fable 5.1 went the other way, to 72.6%. [2][72][75][88]
The mechanism is straightforward. When a reasoning model processes a summarization task, it doesn't just extract — it thinks. It draws inferences, identifies patterns, and generates insights. These additions go beyond the source document. On a benchmark measuring faithfulness to source material, every insight the model adds counts as a hallucination.
It's the difference between "summarize this contract" and "analyze this contract." Reasoning mode adds analysis even when you ask for a summary. That analysis is often useful. On a summarization benchmark, it's scored as a failure.
OpenAI's system card data reveals something that gets less attention: web access has a larger impact on hallucination rates than reasoning mode does. [11][8]
| Model | Browse-OFF | Browse-ON | Reduction |
|---|---|---|---|
| o4-mini FActScore | 37.7% | 5.1% | 86% |
| o3 FActScore | 24.2% | 5.7% | 76% |
| GPT-5 thinking FActScore | 3.7% | 1.0% | 73% |
| GPT-5 SimpleQA | 47% | 9.6% | 80% |
Sources: o3/o4-mini system card [11], GPT-5 system card [8]
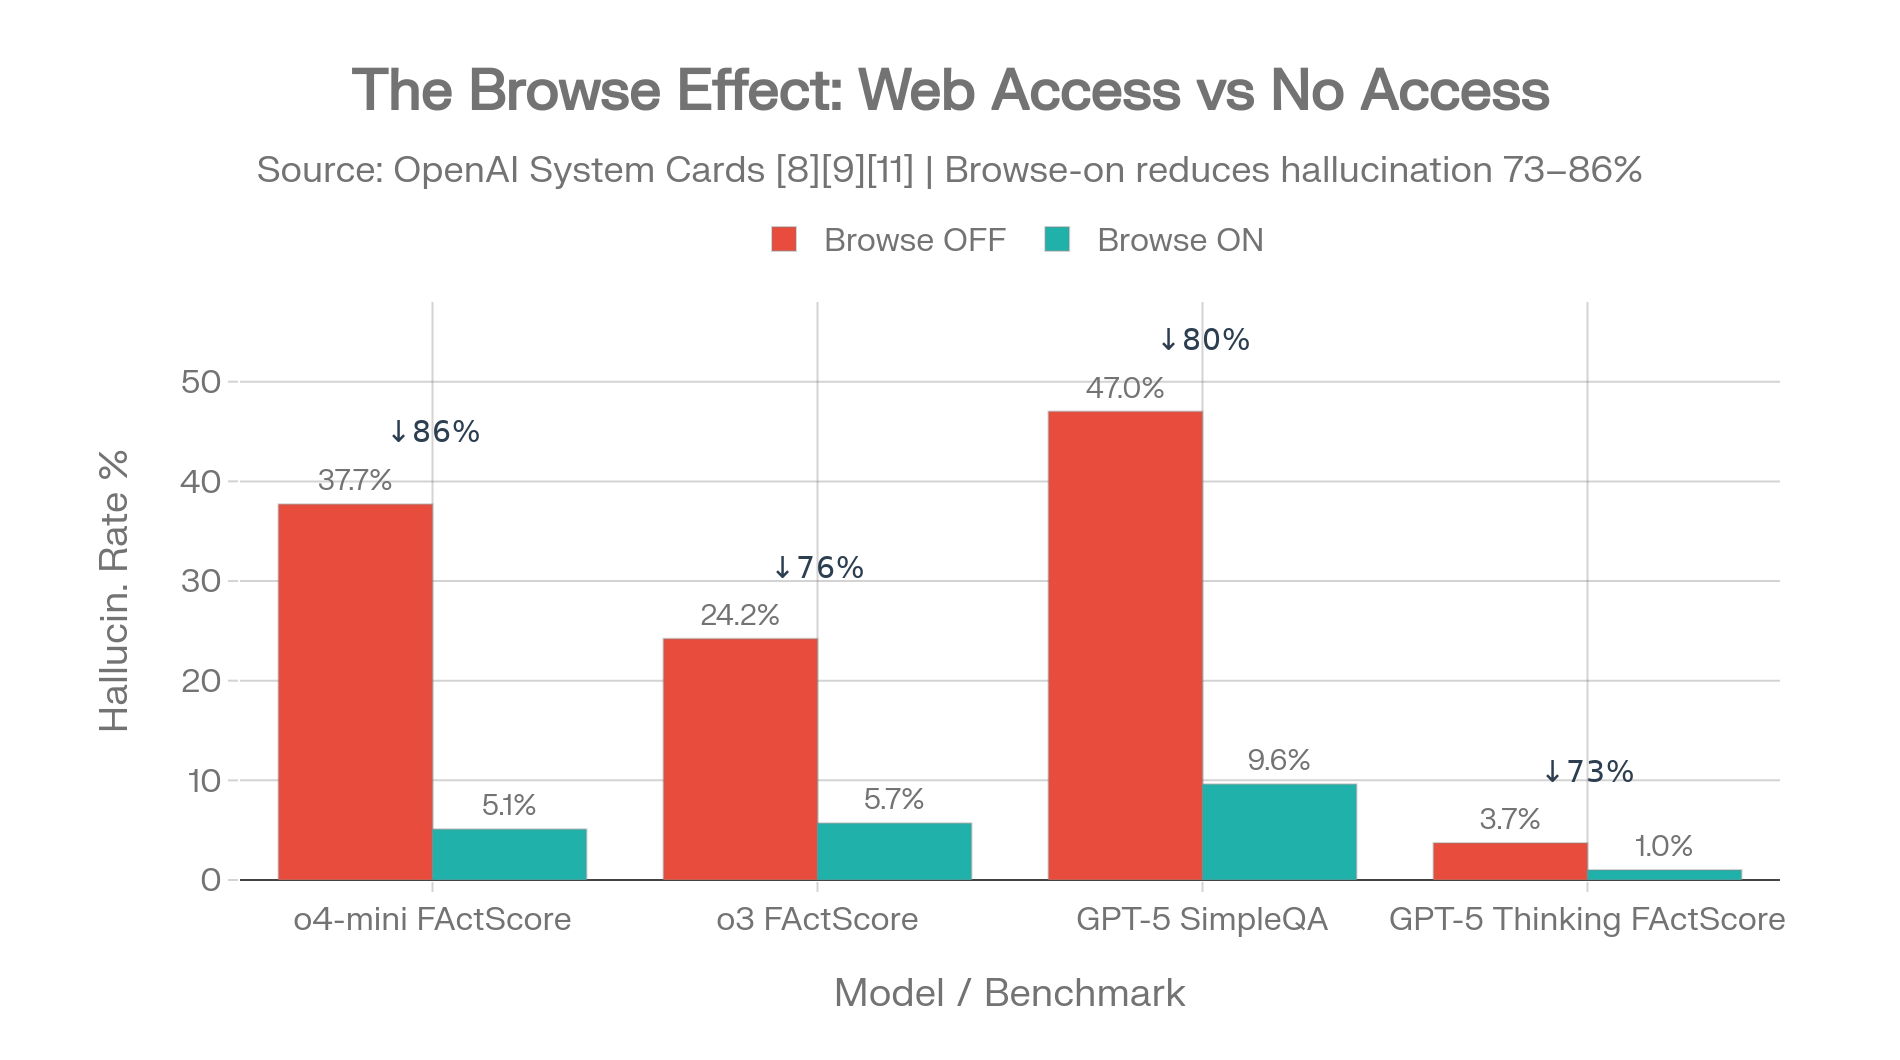
The browse effect: 73-86% hallucination reduction from a single configuration toggle. Sources: OpenAI system cards [8][11][10]
Turning on web search reduces hallucination more than turning on reasoning.
For enterprise deployments, ensuring tool access is more impactful than selecting reasoning vs non-reasoning model variants.
This creates a practical matrix for model selection:
Reasoning ON + Web ON: Best for complex analysis, medical diagnosis, multi-step research where both depth and access to current information matter. Lowest hallucination rates on open-ended tasks.
Reasoning OFF + Web ON: Best for document summarization, RAG pipelines, grounded Q&A where you want the model to stay close to source material. Lower risk of "overthinking" additions.
Reasoning ON + Web OFF: Risky combination. The model overthinks and can't verify. Suitable only for closed-world logic problems, math, and code where external facts aren't needed.
Reasoning OFF + Web OFF: Highest hallucination risk across the board. Avoid for any factual task.
This isn't speculation. Two independent research teams have published formal impossibility results. They are conditional on the formal models they use, which matters, but both point the same way: you can drive hallucination down, you cannot guarantee it away.
Xu, Jain and Kankanhalli (2024) formalized the hallucination problem through learnability and computability and proved that for a general-purpose language model, some inputs will always produce outputs that diverge from the computable ground truth. Not difficult. Not fixable with more compute or better training data. Unavoidable, in their formal setting — with one honest caveat: the result is about the class of problems a general model faces, not a fixed error rate on every prompt. On a narrow enough task a model can approach perfect accuracy. On open-ended questions, it cannot be guaranteed to. [20]
The core argument: any system that generates text by predicting probable sequences from learned statistical distributions will, across the full range of things it can be asked, sometimes produce outputs not grounded in fact. The generative mechanism itself guarantees it.
Karpowicz (2025) attacked the problem from three different mathematical frameworks — auction theory, proper scoring theory, and log-sum-exp analysis for transformer architectures — and reached the same conclusion each time. [21]
No LLM inference mechanism can simultaneously achieve all four of these properties:
You can have any three. You cannot get all four. The math doesn't allow it, within the formal information-aggregation model the paper defines.
OpenAI publicly acknowledged these findings and identified three mathematical factors that make hallucination inevitable: [22]
Epistemic uncertainty — when information appears rarely in training data, the model has no reliable basis for generating accurate output about that topic but will attempt to anyway.
Model limitations — some tasks exceed what the architecture can represent, regardless of training data volume or quality.
Computational intractability — certain verification problems are computationally hard enough that even a theoretical superintelligent system couldn't solve them in reasonable time.
Hallucination is not a bug being fixed in the next model release. It's a structural property of how language models work — reducible by training, tools and verification, not removable by any of them.
This changes the question. The right question isn't "which AI doesn't hallucinate?" — every AI hallucinates. The right question is: what systems do you have in place to catch hallucinations before they reach a decision-maker?
The organizations getting this right aren't waiting for a hallucination-free model. They're building detection layers, cross-validation pipelines, and human review checkpoints. The data on what works (and how much it helps) is in the Reduction Techniques section below.
Not all hallucination reduction techniques are equal. Some are backed by controlled studies with precise measurements. Others have strong theoretical support but limited production data. This ranking reflects the evidence base, not marketing claims.
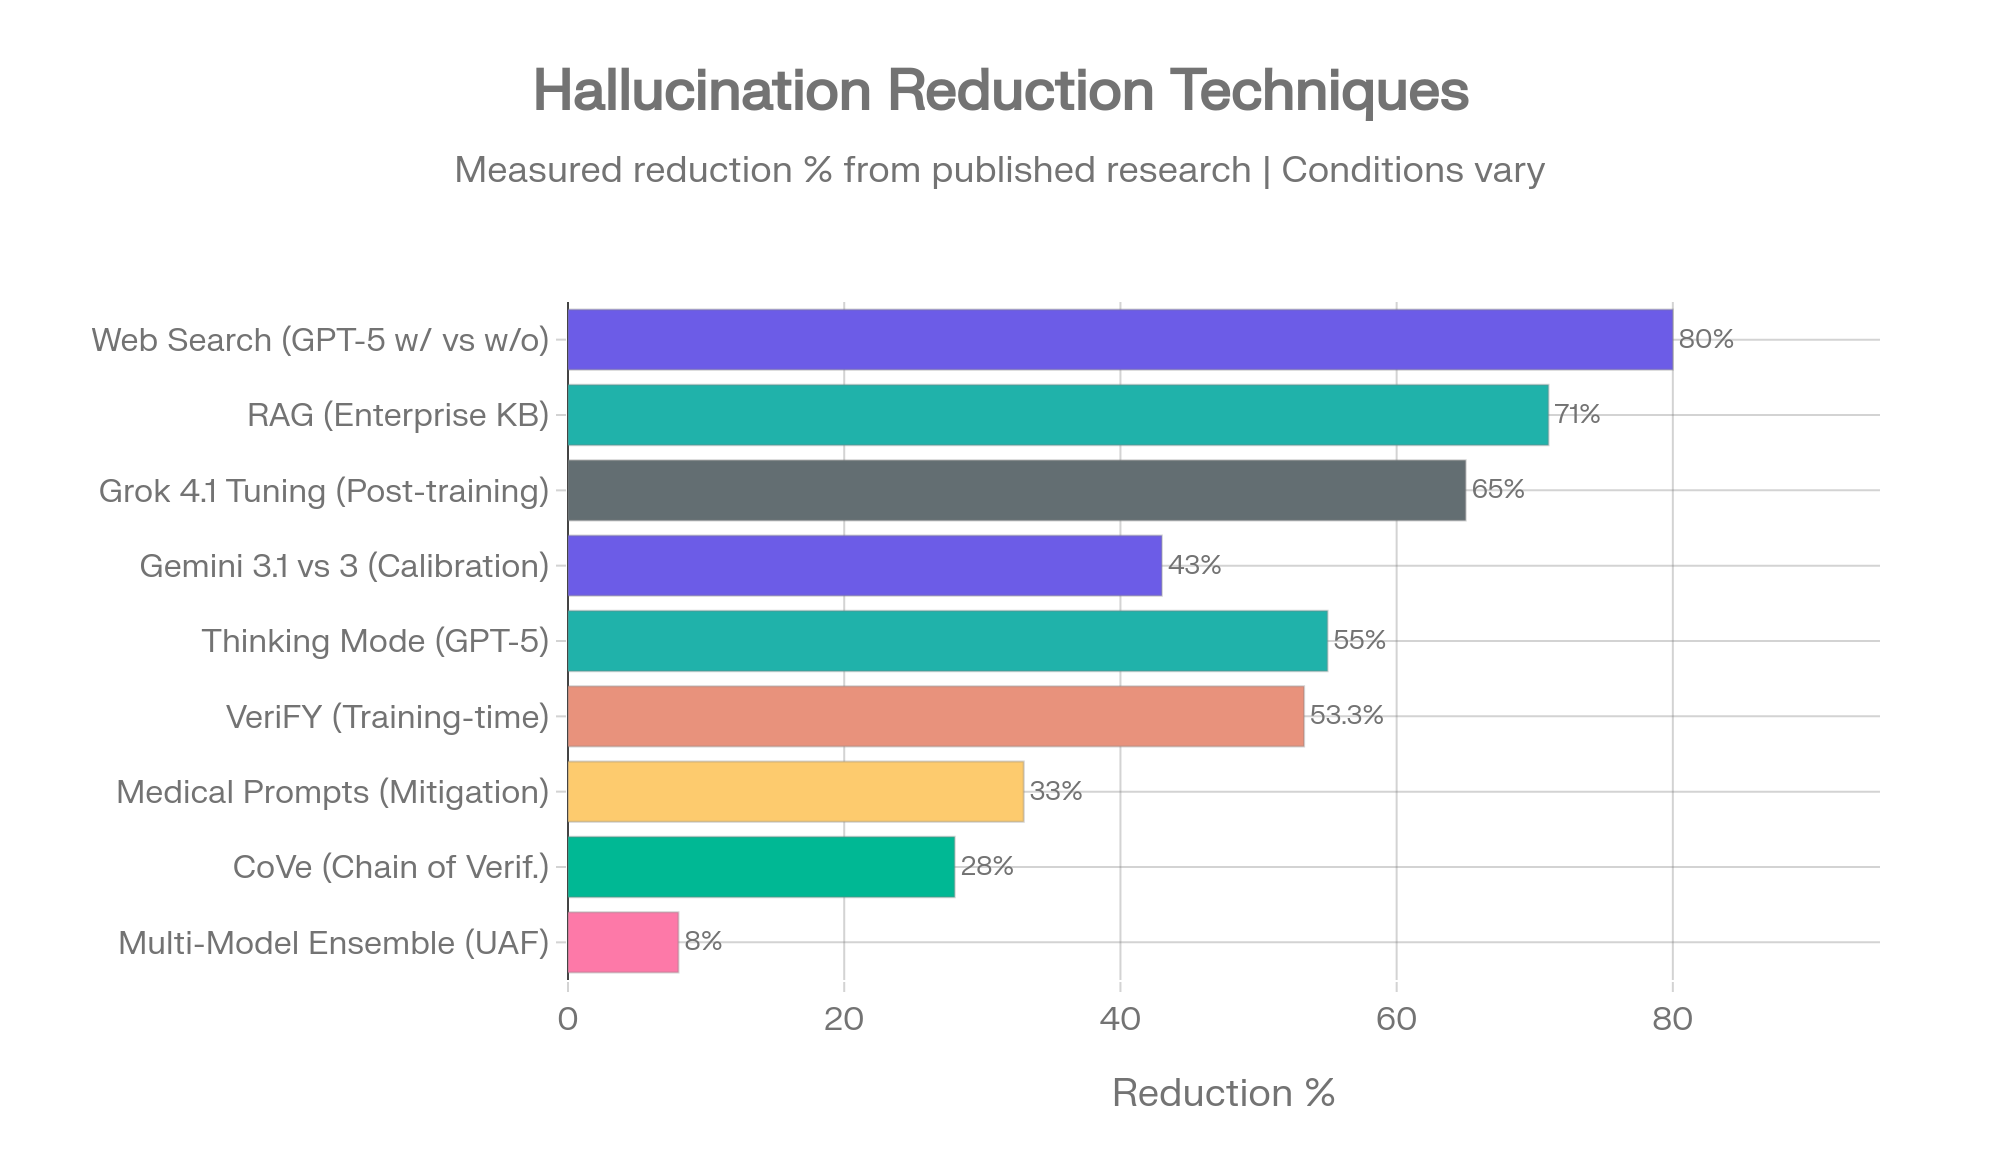
Hallucination reduction techniques ranked by measured impact. Sources: OpenAI [8][11], AllAboutAI [31], HealthBench [52], UAF [24], CoVe [23], VeriFY [25], Gemini 3.1 [15], MedRxiv [40]
Measured impact: 73-86% hallucination reduction (FActScore, browse-on vs browse-off)
The single highest-impact intervention documented in 2025-2026 research. GPT-5 drops from 47% to 9.6% hallucination with web access. The o4-mini drops from 37.7% to 5.1%. GPT-5.3 Instant shows 26.8% reduction when using web vs prior models. [8][11][10]
One scope note. The 73-86% range comes from OpenAI's own LongFact and FActScore evaluations of its own models. The size of the effect varies by model, benchmark and search system, so treat it as the best-documented case rather than a universal constant, and expect any browse-on number to describe the model plus its search stack, not the model alone.
The mechanism is simple: instead of relying on potentially stale or incorrect training data, the model retrieves current information and grounds its response in external sources. For any enterprise deployment, enabling web or tool access should be the first configuration decision, not an afterthought.
Measured impact: Large and setup-dependent. No cross-vendor benchmark isolates it, and the "up to 71%" figure that circulated for enterprise knowledge-base tasks traces to a secondary compilation rather than a controlled study, so this page no longer quotes it as a benchmark result.
RAG connects models to external knowledge bases — company documents, databases, verified sources — and instructs the model to generate responses grounded in retrieved content rather than parametric memory. Hybrid retrievers combining sparse and dense methods achieve the strongest mitigation. Vectara's own leaderboard, which measures exactly this grounded setting, shows the best models under 2% and most frontier models between 5% and 14% — retrieval narrows the problem, it does not close it.
RAG is most effective for knowledge-gap hallucinations (the model lacks relevant training data). It's less effective for logic-based hallucinations (the model reasons incorrectly from correct premises). For enterprise document Q&A and knowledge base applications, RAG is the standard of care.
Measured impact: 55-75% reduction on open-ended medical and factual tasks; increases hallucination on grounded summarization [52]
GPT-5 thinking mode: HealthBench drops from 3.6% to 1.6%. Production ChatGPT traffic: 4.8% of responses contain major incorrect claims vs 11.6% without thinking. These are significant improvements.
But reasoning mode increases hallucination on Vectara's summarization benchmark (see Section 10). The impact is task-dependent. Enable reasoning for analysis, diagnosis, and complex queries. Disable it for summarization, extraction, and source-faithful tasks.
Measured impact: 8% accuracy improvement over single-model approaches (UAF framework) [24]
Amazon's Uncertainty-Aware Fusion framework (published ACM WWW 2025) combined multiple LLMs weighted by their accuracy and self-assessment quality. The key finding: different models excel on different question types, so combining them captures complementary strengths.
Cross-model disagreement detection catches hallucinations because models rarely fabricate the same false information. When one model makes an unsupported claim, others typically flag the inconsistency or provide conflicting data. Research on "wisdom of the silicon crowd" shows LLM ensembles can rival human crowd forecasting accuracy through simple aggregation.
The 8% figure understates the practical value. In production, multi-model approaches catch errors that no single-model check would flag — because the checking model has different training data, different biases, and different blind spots.
Measured impact: 28% FActScore improvement [23]
A four-step pipeline: generate baseline response, plan verification questions, answer those verification questions independently, then refine the final output. Published at ACL 2024, it outperforms zero-shot, few-shot, and chain-of-thought prompting on long-form generation accuracy.
The cost is latency and compute: four steps instead of one. For applications where accuracy matters more than speed — report generation, research synthesis, compliance documentation — the tradeoff is worth it.
Measured impact: 9.7-53.3% hallucination reduction across model families [25]
Published at ICML 2025, VeriFY teaches models to assess factual uncertainty during generation rather than relying on post-hoc checking. The model learns to verify its own claims as it produces them. Recall loss is modest: 0.4-5.7%.
This is a training-time intervention, meaning end users don't control it. Its value is in signaling where the field is heading: future model generations will likely internalize verification as a core capability rather than bolting it on after generation.
Measured impact: 38 percentage point AI hallucination reduction (Gemini 3.1 Pro, 88% to 50%) with only 1% accuracy loss [15]
Google demonstrated that tuning a model's calibration — its ability to match confidence to actual accuracy — can dramatically reduce hallucination without sacrificing knowledge. Gemini 3.1 Pro's Omniscience Index jumped from 16 to 33 with this approach.
Like VeriFY, this is a provider-side intervention. Users benefit from it when selecting newer model versions but can't apply it themselves.
Measured impact: 33% reduction on medical tasks (64.1% to 43.1%); GPT-4o dropped from 53% to 23% [40]
Structured prompts that instruct the model to constrain outputs to verified information, flag uncertainty, and avoid speculation. These work best in narrow domains with clear boundaries and well-defined terminology.
The medical results are encouraging but the absolute rates remain high (43.1% with mitigation is still dangerously wrong for clinical use). Domain prompts are a layer, not a solution.
Larger models alone: In Artificial Analysis's launch analysis, accuracy tracked model size and hallucination rate did not. The 2026 flagships confirmed it: the three most accurate models in our table, Claude Fable 5.1, Claude Opus 5.5 and Claude Fable 5, all give a wrong answer more often than they decline (72.6%, 58.6% and 63.6%). Bigger models know more but don't necessarily know what they don't know.
Simple temperature reduction: Lowering generation temperature reduces variety but doesn't eliminate hallucination. The model still picks the most probable token — it just does so more consistently, including consistently wrong tokens.
"Be accurate" system prompts: Generic instructions to avoid hallucination show minimal measured effect. Models already "try" to be accurate. The issue is architectural, not motivational.
Web search and RAG you already run. The next measured reduction is models catching each other - the mechanism the production data below documents across 1,324 real conversations.
Try Cross-Validation Free7 days free. No credit card. About twenty seconds to the first answer.
Research published across 2024-2026 increasingly converges on a specific finding: querying multiple AI models on the same question catches errors that single-model approaches miss. This isn't a theoretical argument. Multiple peer-reviewed studies provide measured evidence.
The Uncertainty-Aware Fusion (UAF) framework combines multiple LLMs weighted by two factors: each model's accuracy on the task and each model's ability to self-assess when it's uncertain. The measured result: 8% accuracy improvement over any individual model. [24]
The critical insight from the study: "LLMs' accuracy and self-assessment capabilities vary widely with different models excelling in different scenarios." No single model dominates all question types. GPT may be strongest on grounded tasks, Claude on knowledge-calibration tasks, Gemini on breadth-of-knowledge tasks. The ensemble captures all three strengths.
Models trained on different data, with different architectures and different alignment tuning, develop different failure patterns. When five models analyze the same question, they rarely fabricate the same false information.
One model claims a legal precedent exists. Four others don't mention it. That disagreement is a signal. A human reviewer can investigate the specific claim rather than reviewing the entire output.
This works because hallucinations are stochastic, not systematic. A model doesn't consistently hallucinate the same incorrect fact — it fills gaps with different plausible-sounding content each time. When multiple models fill the same gap with conflicting content, the gap becomes visible.
Multiple studies show that simple aggregation across LLM outputs can rival the accuracy of human crowd forecasting. The mechanism parallels Galton's ox-weight experiment and Surowiecki's "Wisdom of Crowds" — individual estimates are biased, but the aggregate cancels out uncorrelated errors. [28]
For AI, this means: five models with 60% individual accuracy, with uncorrelated errors, can produce aggregate outputs significantly above 60% accuracy. The math favors diversity over individual excellence.
The academic findings above describe the mechanism. The Suprmind Multi-Model Divergence Index measures it in the wild, and the full aggregate dataset behind every table below is downloadable there under CC BY 4.0. [61][62]
The dataset: 1,324 multi-model conversation turns from 299 real users across 10 domains over 45 days (March 5 to April 19, 2026). Five frontier models (GPT, Claude, Gemini, Grok, Perplexity) responding to the same questions, with each model reading what came before. After every turn, a classifier records what happened between the models: contradictions, corrections, and unique insights. [61]
What the DMI measures, and what it does not. The index tracks disagreement and correction behavior. It does not measure which model is factually correct in any given exchange. A model being contradicted is a detection signal, not a verdict. The DMI complements accuracy benchmarks like Vectara and AA-Omniscience. It does not replace them. It is also Suprmind's own production measurement with a published dataset, not an independently reproduced benchmark, so its percentages should never be ranked against AA-Omniscience, Vectara or FACTS scores.
Across all 1,324 turns, 99.1% produced at least one contradiction, correction, or unique insight that came only from a model other than the first responder. The "silent agreement" rate — turns where every model agreed without surfacing anything new — was 0.9%. In five of the ten domains tracked (Legal, Medical, Education, Research, Creative), the silent rate was zero. [61]
A single-model query would have missed something on 99 out of 100 of these turns. Whether what was missed was factually critical varies. That something was missed is not in dispute.
The Carnegie Mellon research cited earlier on this page (Cash and Oppenheimer) found that model confidence barely tracks actual performance — the models could not tell how badly they had done. The DMI data shows the same pattern in live multi-model conversations: a high-confidence answer (self-rated 7+ out of 10) is no shield against being contradicted by another model.
| Model (high-confidence answers) | Contradicted or corrected by another model |
|---|---|
| Gemini | 51.3% |
| Grok | 48.8% |
| GPT | 39.5% |
| Perplexity | 33.9% |
| Claude | 33.8% |
Source: Suprmind Multi-Model Divergence Index, April 2026 edition [61]
Across all five providers, between one in three and one in two confidently-stated answers had a substantive issue caught by a peer model. On high-stakes turns specifically, Claude's rate dropped to 26.3% — the lowest of the five — while Gemini's barely moved (50.2%). [61]
This is not a hallucination rate. It is a peer-review catch rate. But the implication for single-model use is direct: confidence in one model's answer, absent any external check, is the most common failure mode in the data. This pattern aligns with the Stanford AI Index 2026 finding above: when false statements are framed as something the user believes, single-model accuracy collapses. The multi-model review mechanism captures this failure mode because a second model, not anchored to the first model's overconfident framing, applies its own baseline to the same claim. [58][61]
Each model in the DMI dataset has a "catch ratio": corrections it made of others, divided by corrections it received from others. A ratio above 1.0 means the model catches more than it gets caught.
| Provider | Catches made | Times caught | Catch ratio |
|---|---|---|---|
| Perplexity | 335 | 132 | 2.54 |
| Claude | 304 | 135 | 2.25 |
| Grok | 193 | 269 | 0.72 |
| GPT | 111 | 295 | 0.38 |
| Gemini | 109 | 416 | 0.26 |
Source: Suprmind Multi-Model Divergence Index, April 2026 edition [61]
Perplexity catches roughly ten times more often than Gemini does. This is not a ranking of which model is "best" — Perplexity's edge comes partly from its search-grounded architecture, which gives it a structural advantage at flagging unsupported claims. The point is that the catching is not random. Different architectures produce different catch profiles, which is exactly what the multi-model thesis predicts. [61]
Disagreement rate by domain, ranked highest to lowest:
| Domain | Multi-model turns | Turns with disagreement |
|---|---|---|
| Financial | 258 | 72.1% |
| Other | 153 | 59.6% |
| Marketing & Sales | 131 | 55.0% |
| Business Strategy | 257 | 54.9% |
| Research Analysis | 74 | 52.7% |
| Technical | 172 | 49.4% |
| Creative | 38 | 42.1% |
| Legal | 136 | 41.2% |
| Medical | 56 | 33.9% |
| Education | 49 | 28.6% |
Source: Suprmind Multi-Model Divergence Index, April 2026 edition [61]
Financial questions produce model disagreement on nearly three out of four turns. Education questions produce it on roughly one in four. The high-stakes domains where this page documented the worst hallucination consequences — financial, legal, medical — are the same domains where running questions through more than one model surfaces the most divergence. Research Analysis specifically: 52.2% of contradictions in that domain were classified critical-severity (7+ on a 10-point scale), the highest critical share of any domain. When models disagree on research questions, they tend to disagree about something that matters. [61]
The academic research established that ensembles outperform individual models. The DMI shows the detection mechanism activating in real production usage — not in benchmarks designed for it, not in lab conditions, but in live conversations with paying users on real questions. The mechanism the research predicts is the mechanism the production data shows.
The remaining honest caveat from the section above still holds: cross-validation raises detection probability, it does not guarantee zero hallucination. Two findings in this dataset reinforce that point. First, models do still occasionally agree on the same wrong answer — the DMI does not catch shared training-data errors. Second, the DMI counts contradictions and corrections, not their resolutions. Knowing that two models disagreed is not the same as knowing which one was right.
The disagreement is the signal; the verification is still the user's job.
Catches well:
Catches less well:
Multi-model validation is a detection layer, not a guarantee. It raises the probability of catching hallucinations. It doesn't eliminate them. The organizations getting the best results combine multi-model cross-validation with domain-specific verification, human review checkpoints, and tool-enabled grounding. [27]
There is still limited standardized public reporting measuring "five-model cross-validation reduces hallucination by X%" across domains under controlled conditions. The UAF framework's 8% improvement is the strongest single number. Production case studies from multi-model platforms are emerging but not yet published in peer-reviewed venues.
The safest evidence-based position: multi-model orchestration is a risk-reduction architecture that increases detection probability. It is not a guarantee of zero hallucination. No approach achieves that guarantee — as the mathematical proofs in Section 11 demonstrate.
Ask something where accuracy matters. Watch five AI models respond — and see where they disagree.
Open the PlaygroundThe hallucination detection tool landscape has expanded rapidly alongside enterprise AI adoption — a reflection of how seriously enterprises take the problem, and how inadequate built-in model guardrails are for production use.
| Tool | Detection Accuracy | Key Strength |
|---|---|---|
| W&B Weave | 91% | Chain-of-thought reasoning, production pipeline integration |
| Arize Phoenix | 90% | Label-based outputs, confidence scoring, real-time monitoring |
| Comet Opik | 72% | 100% precision (zero false positives), conservative approach |
| Galileo | N/A | Hallucination Index scoring, real-time blocking, CI/CD integration |
| GPTZero Citation Check | 99%+ | Verified citations against web/academic databases |
| Future AGI | N/A | RAG-specific hallucination detection, experiment monitoring |
| Pythia | N/A | Knowledge graph-based fact-checking, regulated industries |
Sources: AIMultiple benchmark (2026) [46], Future AGI (2025) [47], GPTZero/Fortune [45]
The top detection tools catch 90-91% of hallucinations. That means roughly 1 in 10 hallucinated outputs still passes undetected through the best available automated checking. For applications where a single undetected hallucination has material consequences — legal filings, medical decisions, financial reporting — automated detection is a necessary layer but not a sufficient one.
Comet Opik's approach is worth noting separately. At 72% detection accuracy, it catches fewer hallucinations. But it has 100% precision — zero false positives. It never flags a correct statement as hallucinated. For workflows where false alarms are costly (interrupting a doctor mid-diagnosis, flagging a correct legal citation for review), this tradeoff may be preferable.
| Year | Best Hallucination Rate | Context |
|---|---|---|
| 2021 | ~21.8% | Early GPT-3 era |
| 2022 | ~15.0% | RLHF alignment improvements |
| 2023 | ~8.0% | GPT-4 launch and competitive pressure |
| 2024 | ~3.0% | Rapid iteration across all providers |
| 2025 | 0.6% | Ant Group finix_s1_32b on Vectara's original dataset, added August 2025. Gemini-2.0-Flash, the best frontier-lab model, scores 0.7% |
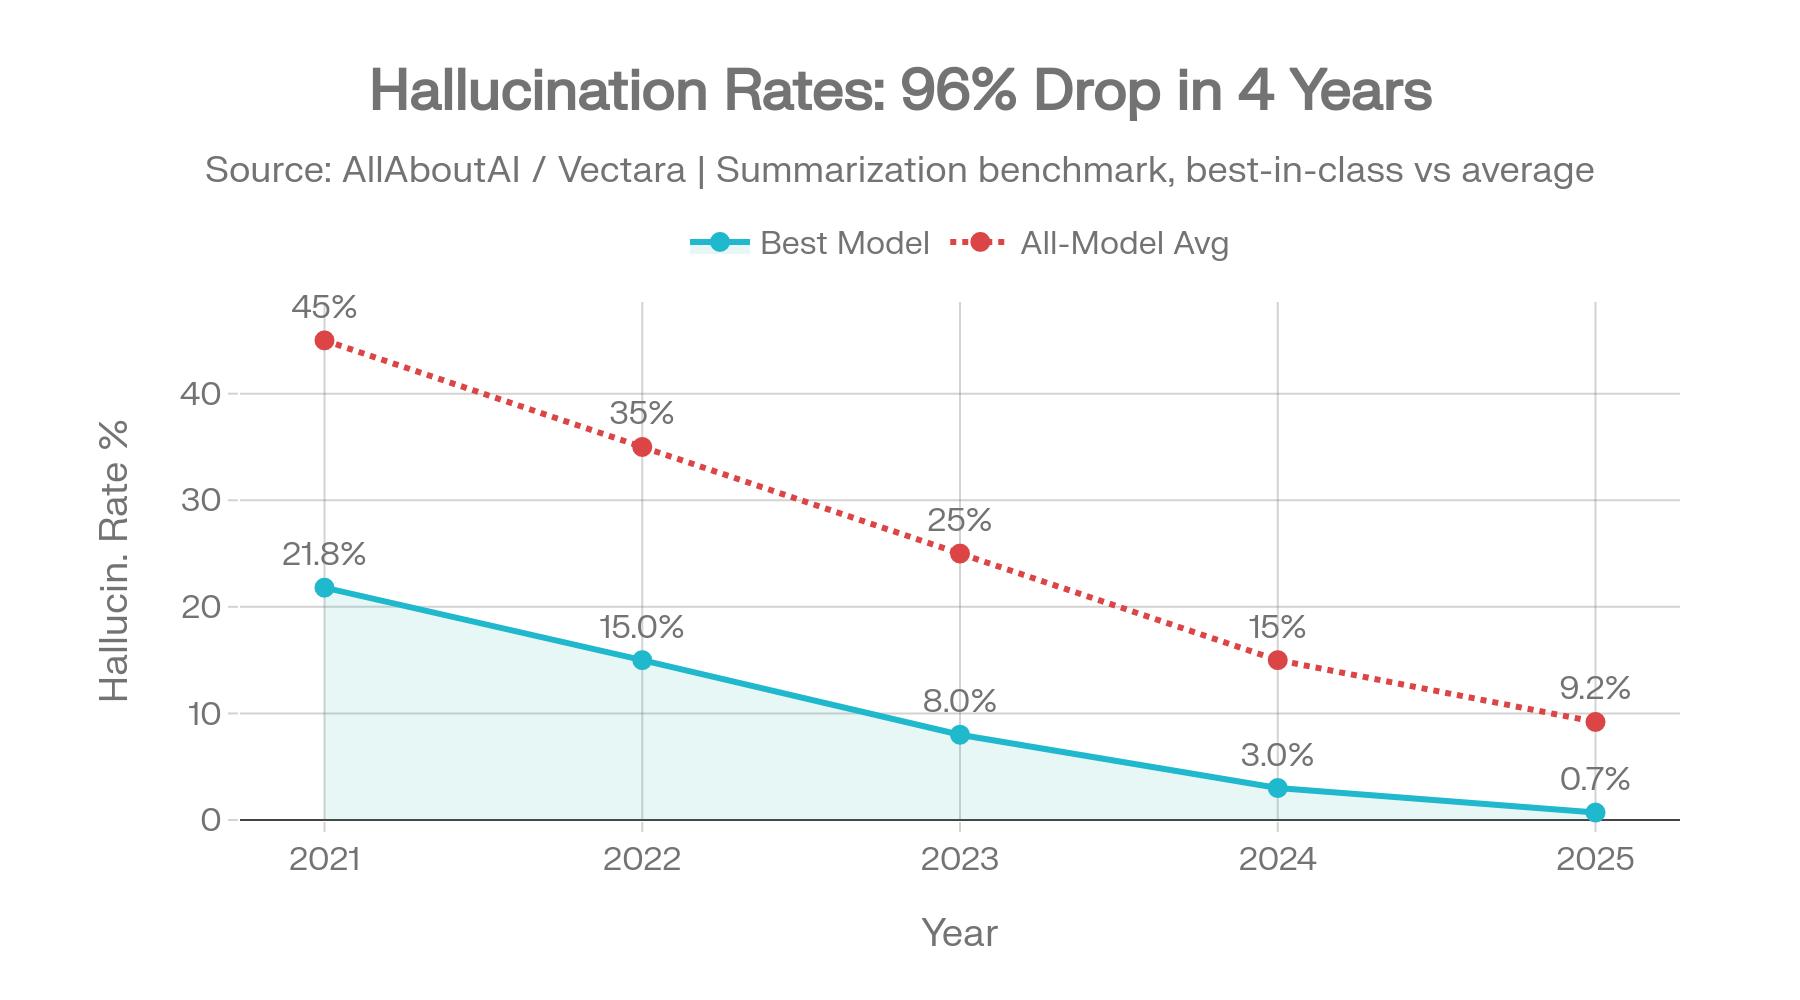
Four years of hallucination improvement on simple summarization tasks: 21.8% → 0.7% (0.6% with finix_s1_32b, added August 2025). Vectara froze this dataset in October 2025. Sources: Vectara [1], AllAboutAI [31]
That's a 97% reduction in best-model hallucination rates over four years on the Vectara summarization benchmark. The trend line is real and it's steep.
These improvements measure the easiest version of the problem: summarizing short documents without adding unsupported facts. When you move to harder, more realistic evaluations, the picture changes:
AA-Omniscience (hard knowledge questions): 141 of the 202 models on the October 6, 2026 board give more wrong answers than right ones. Only 61 have a positive Omniscience Index, and the three most accurate models in our table, Claude Fable 5.1, Claude Opus 5.5 and Claude Fable 5, still give a wrong answer more often than they decline. [2][88]
HalluHard (realistic conversations): Even the best entry on the board, GPT-6 Astra with web search, hallucinates 27.2% of the time, and Claude Opus 4.5 with web search 30.2%. Of its 41 entries, 10 are under 50%, 16 fall between 50% and 70%, and 15 are above 70%. [5]
Vectara new dataset (enterprise-length documents): Rates are higher than on the original dataset for most models, often several times higher: GPT-4.1 goes from 2.0% to 5.6% and GPT-5 (high) from 1.4% to 15.1%. The best score is 1.8% (finix_s1_32b), not 0.6%, and the best frontier-lab score is 3.1% (GPT-5.4 nano). Most frontier models sit between 5% and 14%. [1][100]
Domain-specific tasks: Purpose-built legal AI tools still err on more than 17% of queries (Stanford RegLab, 2025), and complex clinical cases reach 64.1% hallucination without mitigation. Specialized domains haven't shown the same improvement trajectory as general summarization. [36][40]
Improvement is real. But extrapolating from simple benchmarks to enterprise reliability is a mistake the data doesn't support.
This page draws from the following primary sources:
Benchmarks: Vectara HHEM Leaderboard (both the original ~1,000 document dataset and the refreshed 7,700-article dataset), Artificial Analysis AA-Omniscience, Google DeepMind FACTS Benchmark, OpenAI SimpleQA and PersonQA, Google DeepMind's SimpleQA Verified, HalluHard (EPFL and the ELLIS Institute Tübingen), and the Columbia Journalism Review citation accuracy study.
System cards and technical reports: OpenAI GPT-5 system card, GPT-5.2 deployment update, o3/o4-mini system card, Anthropic model announcements for Claude Opus 4.5/4.6/4.8/5 and Sonnet 4.6/5, xAI's Grok 4.6 model card, Google's Gemini 3.7 Flash announcement, Google DeepMind FACTS methodology paper.
Industry studies and incident data: Stanford RegLab/HAI legal AI study, MedRxiv medical hallucination research, EY Responsible AI Pulse survey, McKinsey State of AI survey, Zapier workslop survey, Business Insider court ruling tracker, Damien Charlotin legal citation hallucination database, and the GPTZero/Fortune NeurIPS 2025 analysis.
Academic research: Xu et al. (2024) on impossibility of hallucination elimination, Karpowicz (2025) on mathematical impossibility across three proof frameworks, Amazon/ACM WWW 2025 Uncertainty-Aware Fusion framework, ICML 2025 VeriFY training-time verification, ACL 2024 Chain-of-Verification.
April 2026 additions: Stanford HAI 2026 AI Index Report (sycophancy benchmark and AI incident database), Vectara HHEM April 20, 2026 snapshot, Artificial Analysis AA-Omniscience April 2026 state (Claude Opus 4.7, GPT-5.5, Grok 4.20), Damien Charlotin database (1,200+ legal cases), OpenAI HealthBench Professional, and the Suprmind Multi-Model Divergence Index April 2026 edition.
June 2026 additions: Artificial Analysis AA-Omniscience figures for Claude Opus 4.8 (released May 28, 2026), Gemini 3.5 Flash (May 18, 2026), Grok 4.3 (April 30, 2026), and DeepSeek V4 Pro and V4 Flash (April 24, 2026), plus Muse Spark (Meta, April 2026) on HealthBench Hard. One caveat applies to Gemini 3.5 Flash: Google did not publish a first-party hallucination figure for it, so the 61% rate cited here is Artificial Analysis independent measurement, not a vendor number. [64][68]
July 2026 additions: Artificial Analysis AA-Omniscience figures for Claude Fable 5 (June 9), GPT-5.6 Sol (July 9), Grok 4.5 (July 8), Kimi K3, Muse Spark 1.1, Command A+, and Qwen3.7 Max; Grok 4.3's standalone AA profile (high and medium) replacing the earlier derived estimate; the Charlotin legal database at 1,769 cases (July 17); and the enterprise-adoption figure corrected from a mis-attributed "85% Gartner" to 88% organizational adoption (McKinsey State of AI 2025, via Stanford HAI 2026 AI Index). Two figures were shown at reduced confidence in that revision: GPT-5.6 Sol appeared with accuracy only, and Claude Sonnet 5's AA triad was flagged provisional. Both were resolved in the August 27 revision below. The FACTS table is the December 2025 Suite launch snapshot. [72][78]
August 8, 2026 revision: Business-impact figures re-sourced to primary studies: EY Responsible AI Pulse (October 2025, n=975 C-suite), McKinsey State of AI (November 2025, n=1,993), Zapier (January 2026, n=1,100), and Cash and Oppenheimer in Memory & Cognition (2025) for the confidence paradox. Removed as untraceable to any primary source: the $67.4B global-loss estimate, a "47% of executives" claim attributed to Deloitte, Forrester per-employee verification costs, a Gartner 318% market-growth figure, and an aggregator-sourced domain rate table. [79][80][81][82]
August 27, 2026 revision: Added Claude Opus 5 (July 24), Grok 4.6 (August 12), Gemini 3.7 Flash (August 13), Muse Spark 1.2 (August 5), Qwen3.8 Max Preview (August 3), GLM-5.3 (August 14) and the DeepSeek V4 Pro 0813 GA build (August 13), each with its AA-Omniscience triad from the August 26-27, 2026 AA-synced snapshot (167 models). Claude Fable 5 re-scored to Index 43 / 65% accuracy / 63.6% hallucination, confirmed against Artificial Analysis's own page. GPT-5.6 Sol, Terra and Luna given the hallucination rates and Index values now on the board. Claude Sonnet 5 updated and its "provisional" flag retired. Every added or updated row was checked for internal consistency (Index equals correct minus incorrect). Rows that pre-date August keep the launch figures this page first cited, with the August re-pull listed in the AA source note. Six pre-2026 rows (Claude Opus 4.7, Opus 4.6, Opus 4.5, Sonnet 4.6, GPT-5.1, GPT-5.2) could not be reconciled to a single configuration on the current board and are unchanged pending a direct re-pull. Vectara original-dataset table corrected against the archived branch: finix_s1_32b leads at 0.6%, and five rows that belonged to the new dataset were moved there. Legal figures corrected to the published papers (17-33% for legal tools, 58-88% for general-purpose chatbots). Charlotin count updated to 1,963. Removed as untraceable to a primary study: the finance-domain figures (15-25% rate, 2.3 errors per quarter, $50K-$2.1M per incident, 20.0% vs 76.7% literature test, VC and robo-advisor anecdotes, $12.7M SEC total) and the "RAG up to 71%" reduction figure. Added BullshitBench v2 and the NeurIPS fabricated-citation taxonomy as new sources. [83][88][94][95][100]
October 6, 2026 revision: Added GPT-6 Astra (September 3), GPT-6 Sol (September 22), GPT-6.1 Sol (September 29), GPT-6 Luna, Claude Fable 5.1 (September 1), Claude Opus 5.5 (September 22), Claude Sonnet 5.5 (September 28), Gemini 4 Argon (announced September 30, not yet publicly available), Gemini 3.8 Flash (September 2), Gemini 3.5 Flash-Lite, Grok 4.7 (September 21), Muse Spark 1.3 (September 2), Qwen3.8 Max 0902 (September 2) and DeepSeek V4.1 Flash. Every AA-Omniscience value that Artificial Analysis still lists was re-read from its own model records on October 4, 2026, and 30 earlier rows were corrected or completed, for example Gemini 3 Pro's hallucination rate from 88% to 91.5% and Claude Opus 4.7's from 36% to 42.3%. Vectara new-dataset scores added from the September 22, 2026 board for GPT-6 Astra, GPT-6 Sol and GPT-5.6 Sol, plus Claude Opus 4.7, Claude Opus 4.5 and Gemini 3 Flash. Grok 4.1 Fast's Vectara figure corrected from 20.2% (Grok 4 Fast's score) to 19.2%. Charlotin legal count updated to 2,149 cases (October 5). Quick findings, model profiles and the FAQ rewritten for the new data. The update note now describes continuous updates instead of a monthly schedule. [2][1][37]
October 7, 2026 revision: The four headline figures at the top of the page now come from the October data: Gemini 4 Argon's 15.1% (not yet publicly available) with Grok 4.7's 29.3% for public models answering at least 45% correctly, GPT-6 Astra's 51.3%, Claude Fable 5.1's 72.6%, and the 141 of 202 models with a negative Index on the October 6 board. They replace the EY $4.4M loss average, Vectara's 0.6% best case and Gemini 3 Pro's 91.5%, which are all still covered further down the page, and the August board count. Both AA-Omniscience tables were rebuilt from Artificial Analysis's October 4 records (apart from Claude 4.1 Opus's November 2025 snapshot): the top 30 by accuracy, and a full ranking of all 57 models by hallucination rate with accuracy alongside. The AA-Omniscience release notes now run newest first, with launch figures and the current record side by side. The "three most accurate models" statements now name Claude Fable 5.1, Claude Opus 5.5 and Claude Fable 5. [2][88] Later the same day, the Vectara new-dataset, HalluHard and SimpleQA Verified figures moved to their current boards and the FACTS section added the 2026 Kaggle board. The Vectara new-dataset table now shows 35 of the 108 models from the September 22, 2026 snapshot, HalluHard figures come from its October board (GPT-6 Astra 27.2%, Claude Opus 4.5 30.2%), and SimpleQA Verified is a new source. In the cross-benchmark table, five cells are now blank because they held another model's score or a score that does not exist: the Vectara (New) cells for o3-mini-high and Gemini 2.0 Flash and the FACTS cells for o3-mini-high, GPT-5.2 and Grok 4.1 Fast. GPT-5's Vectara (New) cell now shows its board figure, 15.1%, instead of "over 10%", and four blank Vectara cells were filled from the boards (Claude 4.1 Opus, Claude Sonnet 4.5, Claude 4.5 Haiku and GPT-5.1). The Vectara section's February 2026 snapshot table and its DeepSeek-R1-0528 row (an original-dataset figure) were removed, and the HalluHard reference now names the benchmark's authors and paper. [1][3][5][101]
This page now includes data from the Suprmind Multi-Model Divergence Index (DMI), a recurring publication tracking inter-model disagreement and correction patterns in real production usage of the Suprmind platform. The April 2026 edition covers 1,324 multi-model conversation turns from 299 users across 10 domains over a 45-day window (March 5 to April 19, 2026). [61][62]
What the DMI measures: how often AI models contradict each other, correct each other, and surface insights missed by other models when run together on the same question.
What the DMI does not measure: factual accuracy against ground truth. The DMI records that one model contradicted another. It does not adjudicate which model was correct. Disagreement is treated as a detection signal, not as a verdict on accuracy.
We treat DMI data and accuracy benchmarks as complementary, not interchangeable. Vectara, AA-Omniscience, FACTS, and the other benchmarks on this page measure how often models are wrong in isolation. The DMI measures how often models catch each other in production. Both questions matter. They are not the same question.
The DMI dataset, methodology, and all twelve underlying CSV files are publicly available at the page linked in the references. Internal-account data is excluded; the published dataset is external users only.
The next edition is in preparation. The DMI figures on this page are the April 2026 edition and will be refreshed when it publishes.
TruthfulQA — partially saturated. Included in model training data, contains some incorrect gold answers, and can be gamed to 79.6% accuracy by a decision tree that never sees the question. Kept out of the tables; still useful for tracking one model family over time.
HaluEval — solvable by answer length. A classifier that flags answers over 27 characters as hallucinated achieves 93.3% accuracy, undermining the benchmark's validity for model comparison.
Derived numbers — where a leaderboard publishes two of the three AA-Omniscience metrics, we do not compute the third and print it. We show a dash until the source publishes it.
Unverified community benchmarks — Reddit posts, Twitter claims, and blog articles citing benchmark numbers without methodology documentation or reproducibility information were excluded unless they could be cross-referenced against primary sources.
Vendor marketing claims — where a provider claims a specific hallucination rate but independent benchmarks show different numbers, both are presented with the discrepancy noted. This applies particularly to xAI's internal Grok benchmarks versus AA-Omniscience results.
Vectara snapshots are dated. The original ~1,000-document dataset is frozen on an archived branch last updated October 16, 2025. The refreshed 7,700-article dataset runs from November 2025, with the most recent snapshot dated September 22, 2026 (read October 7, 2026). AA-Omniscience launched November 2025 and is updated as new models release and as existing models are re-run. The cross-benchmark table and the AA-Omniscience section's tables use Artificial Analysis's own model records, read October 4, 2026, and the release notes quote launch figures alongside the current record. FACTS was published December 2025. Its Kaggle board now scores search with a revised component, FACTS Search V2, and was last updated September 28, 2026. HalluHard's board was read on October 7, 2026. Its maintainers changed the judging pipeline on September 17, 2026 and expect every model's rate to move once re-run, so those figures may change. OpenAI system cards are dated per release. Vendor-internal factuality figures (xAI's model cards, OpenAI system cards) are always labeled as such and never placed in the same column as an independent benchmark.
When two benchmarks show different numbers for the same model, this usually reflects different evaluation dates, different dataset versions, or different aspects of factuality being measured. We flag these discrepancies rather than averaging them.
Perplexity Sonar models are not listed on AA-Omniscience or Vectara. Perplexity uses underlying models (including GPT and DeepSeek variants) making hallucination attribution complex. Their SimpleQA and Search Arena results are included where available.
Vectara coverage: no Claude, Gemini or Grok model released since May 2026 has a Vectara score as of October 7, 2026. The September 22 update added only OpenAI's GPT-6 Sol, GPT-6 Astra and GPT-5.6 Sol. Several 2026 models from other labs, including Grok 4.6, Muse Spark 1.2, Qwen3.8 Max and GLM-5.3, have AA-Omniscience profiles but no FACTS or HalluHard scores.
AA-Omniscience configurations: Artificial Analysis lists several effort configurations per model, and third-party mirrors do not label them consistently. Since October 4, 2026, every AA-Omniscience value in the cross-benchmark table comes from Artificial Analysis's own model records, apart from Claude 4.1 Opus's November 2025 launch snapshot. Rows that name no configuration use the one matching the figure this page first published, as in the table's source note. The hero figures, quick findings, FAQ and the AA-Omniscience section's tables use the October 4 values (the hero's board count is BenchLM's October 6 snapshot), and that section's release notes give launch figures with the current record alongside. The model profiles and head-to-head tables still quote the figures first published for each model, at launch or on the August 2026 board.
Claude Opus 4.6 and Sonnet 4.6 were released in February 2026. Vectara new-dataset scores exist for both (12.2% and 10.6%). AA-Omniscience figures depend on configuration, see above.
GPT-5.3 has AA-Omniscience data (52.9% accuracy for the Codex variant at xhigh) but limited coverage on other benchmarks as of this writing.
Grok internal versus independent figures disagree on direction for Grok 4.6 (better on AA-Omniscience, slightly worse on xAI's internal factuality evaluation). Both are shown, neither is averaged.
Domain-specific breakdowns for most benchmarks test general knowledge. Industry-specific hallucination data (financial, medical, legal) comes primarily from specialized studies rather than the major leaderboards.
Business cost figures come from surveys rather than verified incident databases. The EY per-organization loss average, the survey-reported hours spent fixing AI output, and the per-incident ranges are self-reported and should be treated as indicative of scale rather than precise accounting.
This page is updated continuously, not on a fixed schedule. Every update changes the date at the top of the page and is listed in the dated revision notes above.
As models ship: new model releases and their AA-Omniscience scores, Vectara leaderboard snapshots and system card figures.
As sources publish: FACTS leaderboard changes, new benchmarks, academic findings, court-case counts and regulatory developments (particularly EU AI Act enforcement related to accuracy requirements).
An AI hallucination rate measures how often a model generates false or fabricated information presented as fact. The rate varies by benchmark because different tests measure different failure modes. Vectara measures how often a model adds invented facts when summarizing a document. AA-Omniscience measures how often a model gives a confident wrong answer instead of admitting it doesn't know. FACTS measures factuality across four dimensions: grounding, multimodal, parametric knowledge, and search. A model can score 0.7% on Vectara and 88% on AA-Omniscience simultaneously because the tests measure completely different things.
There is no single answer - it depends entirely on the task. On knowledge questions where the model must admit ignorance: Claude 4.1 Opus achieved 0% hallucination on AA-Omniscience in the November 2025 launch snapshot by refusing to answer rather than guessing, and among capable open-weight models Command A+ reaches 14% the same way. Among models that answer at least 45% of questions correctly, Gemini 4 Argon is the best calibrated at 15.1% (49.9% accuracy), though it is not yet publicly available, and Grok 4.7 leads the public models at 29.3% (Artificial Analysis records, October 4, 2026). On document summarization: Ant Group's finix_s1_32b leads the Vectara original dataset at 0.6%, with Gemini-2.0-Flash at 0.7%, and the new dataset at 1.8%. On multi-dimensional factuality: GPT-6 Astra leads the 2026 FACTS board at 75.7 (Gemini 3 Pro's 68.8 led the December 2025 launch table, on a scale that is not directly comparable). On realistic conversational tasks: GPT-6 Astra has the lowest HalluHard rate, 27.2% with web search, ahead of Claude Opus 4.5 at 30.2%. No single model leads across all benchmarks.
Claude's hallucination rate varies significantly by model version and benchmark. On AA-Omniscience (Artificial Analysis records, October 4, 2026), Claude Opus 5.5 posts 66.2% accuracy, a 58.6% hallucination rate and an Omniscience Index of 46.4, the highest Index in our table. Claude Fable 5.1 has the highest accuracy at 67.2% but a 72.6% hallucination rate (Index 43.5). Claude Sonnet 5.5: 53.9% accuracy, 47.0% hallucination, Index 32.3. These three are max runs with a fallback model. Earlier 2026 models: Claude Fable 5 65% accuracy, 63.6% hallucination, Index 43. Claude Opus 5 61%, 60.8%, Index 37. Claude Sonnet 5 40.1%, 39.4%, Index 16.5. Claude Opus 4.8 48.8%, 39.3%, Index 28.8, the best-calibrated Claude flagship of 2026. Claude Opus 4.7 48.9%, 42.3%, Index 27.3. Claude 4.1 Opus scored 0% hallucination in the November 2025 launch snapshot by refusing rather than guessing (FACTS score 46.5). Claude Opus 4.6: 12.2% on Vectara new dataset, 47.0% accuracy and 62.8% hallucination on AA-Omniscience. Claude Opus 4.5: 46.6% accuracy and 61.0% hallucination, FACTS score 51.3 (December 2025 launch table), 30.2% on HalluHard with web search. Claude Sonnet 4.6: 10.6% on Vectara new dataset, 48.4% hallucination on AA-Omniscience.
GPT-6 Astra (max, released September 3, 2026): 62.6% accuracy on AA-Omniscience, a 51.3% hallucination rate and an Omniscience Index of 43.4 (Artificial Analysis records, October 4, 2026), plus 8.7% on Vectara's new dataset. It also leads the 2026 FACTS board (75.7) and HalluHard with web search (27.2%). Its high setting is better calibrated, at 44.8% hallucination. GPT-6.1 Sol: 62.1% accuracy, 54.3% hallucination, Index 41.5. GPT-6 Sol: 54.5% accuracy, 60.1% hallucination, 6.5% on Vectara new. GPT-6 Luna: 43.8% accuracy, 76.7% hallucination. The GPT-6 generation cut hallucination sharply: GPT-5.6 Sol read 59.4% accuracy and 92.2% hallucination, GPT-5.6 Terra 46.8% and 87.9%, GPT-5.6 Luna 42.7% and 92.6%. GPT-5.5: 58.0% accuracy, 89.0% hallucination. GPT-5.3 Codex: 52.9% accuracy, 89.2% hallucination. GPT-5.2 (xhigh): 10.8% on Vectara new dataset (high setting), 44.3% accuracy and 81.2% hallucination on AA-Omniscience, HalluHard 38.2% with web search. GPT-5: 1.4% on Vectara original, 15.1% on new dataset (high setting), 40.3% accuracy and 82.2% hallucination on AA-Omniscience, FACTS score 61.8. GPT-4.1: 2.0% on Vectara original, 5.6% on new, FACTS score 50.5.
Grok 4.7 (September 21, 2026): 47.4% accuracy and 29.3% hallucination on AA-Omniscience, Omniscience Index 32.0 (Artificial Analysis records, October 4, 2026). Among public models that answer at least 45% of questions correctly, it is the best calibrated in our table. Grok 4.6 (August 12, 2026): 48.2% accuracy, 34.3% hallucination, Index 30.5, though xAI's own internal factuality evaluation scores it slightly worse than Grok 4.5 (1.7% vs 0.98%). Grok 4.5 (July 8, 2026): 51.6% accuracy and 54.1% hallucination. Grok 4.3 has two configurations: high (34.8% accuracy, 25.8% hallucination, Index 18.0) and medium (16.9% hallucination, the lowest of any Grok, ahead of the older Grok 4.20 Reasoning build at 17.4%). Grok 4: 4.8% on Vectara original, over 10% on new dataset, 40.5% accuracy and 64.5% hallucination on AA-Omniscience, FACTS score 53.6. Grok 4.1 Fast Reasoning: 19.2% on Vectara new dataset, 73.4% hallucination on AA-Omniscience. Grok-3: 2.1% on Vectara original, 5.8% on new, 94% citation hallucination on CJR. The Grok 4.1 Fast Reasoning variant performs notably worse than base Grok 4, suggesting the reasoning mode adds inferences that become hallucinations on factual tasks.
Gemini 4 Argon (announced September 30, 2026, not yet publicly available): 49.9% accuracy, 15.1% hallucination and an Omniscience Index of 42.4 on AA-Omniscience (Artificial Analysis records, October 4, 2026), the best calibration of any high-accuracy model in our table. Gemini 3.1 Pro, Google's best public model on the Index: 10.4% on Vectara new dataset, 54.9% accuracy, 50.9% hallucination, Index 31.9. Gemini 3.8 Flash (September 2026): 54.6% accuracy, 55.2% hallucination, Index 29.6. Gemini 3.7 Flash (August 2026): 55.3% accuracy, 64.5% hallucination, Index 26.5. Gemini 3.5 Flash (May 2026): 62.2% hallucination by Artificial Analysis's independent measurement, about 31 points better than Gemini 3 Flash's 93.0%, though Google did not publish a first-party hallucination figure for it. Gemini 3 Pro: 13.6% on Vectara new, 55.8% accuracy but 91.5% hallucination on AA-Omniscience, FACTS score 68.8 (highest in the December 2025 launch table). Gemini 2.0 Flash: 0.7% on Vectara original (lowest of any frontier-lab model). On SimpleQA Verified, a test of short factual answers without tools, Gemini 3.1 Pro Preview leads the board at 77.5%. The 3.1 Pro update was significant: hallucination dropped from 91.5% to 50.9% at almost the same accuracy. Gemini 3 Pro and 3 Flash attempted nearly every question, which lifted accuracy but drove high hallucination when they hit their knowledge limits. Later Gemini models decline more often, Argon and 3.5 Flash-Lite most of all.
Perplexity Sonar Pro scored 37% citation hallucination on the Columbia Journalism Review benchmark - the lowest of any model tested, but still meaning more than one in three cited sources contained fabricated claims. ChatGPT hit 67% on the same test. Gemini hit 76%. Grok-3 reached 94%. Perplexity's failure mode is uniquely dangerous: the URLs it cites are real, but the information it attributes to those sources is sometimes fabricated. No Vectara or AA-Omniscience benchmark data exists for Perplexity Sonar models.
Different benchmarks measure fundamentally different failure modes. Vectara tests summarization faithfulness. AA-Omniscience tests knowledge calibration. FACTS tests multi-dimensional factuality across grounding, multimodal, parametric, and search tasks. CJR tests citation accuracy. A model like Grok-3 scores 2.1% on Vectara (sticks to source documents well) but 94% on CJR (fabricates nearly every citation). Both numbers are accurate. They measure different skills. The responsible approach: cross-reference at least two benchmarks measuring different things, specify the exact model version and settings, and note whether web search or reasoning mode was enabled.
No. Two independent formal impossibility results show that hallucination cannot be guaranteed away in a general-purpose language model, only reduced. It is not an engineering problem awaiting a fix. Best-case hallucination rates have dropped from 21.8% to 0.6% over four years on simple summarization tasks. But on harder tasks - legal research (where even purpose-built tools err on more than 17% of queries), complex medical cases, knowledge questions requiring the model to rely on its own training data - rates remain high across all models. The research community has shifted from eliminating hallucinations to managing hallucination risk through detection, flagging, containment, and cross-validation. Web search access is the single biggest reducer, cutting hallucination rates 73-86% when enabled.
Companies that experienced AI-related incidents report an average loss of $4.4 million per organization, conservatively estimated (EY Responsible AI Pulse, October 2025, n=975 C-suite). 51% of organizations reported negative consequences from generative AI (McKinsey State of AI, November 2025, n=1,993), and professionals spend an average of 4.5 hours per week fixing or redoing AI output (Zapier, January 2026, n=1,100). There are 2,149 documented legal cases involving AI-generated false information (Charlotin database, October 5, 2026, updated continuously). The FDA has authorized over 1,350 AI-enhanced medical devices, with 60 devices involved in 182 recalls.
Research increasingly supports this. Different AI models rarely hallucinate the same false information because they have different training data, different architectures, and different blind spots. A UAF framework study measured 8% accuracy improvement through multi-model ensemble approaches. Cross-model disagreement catches fabrications specifically because the failure modes don't overlap. When three models analyze the same question and two disagree with the third, the disagreement itself is a signal that a claim needs human review. This is the principle behind multi-AI orchestration platforms that route questions to multiple frontier models simultaneously. See how Suprmind uses this approach →
Five frontier models. One conversation. Every answer cross-checked. See why professionals who can't afford to be wrong are switching to multi-model validation.
Select Your Plan -->


