In Suprmind, five frontier AIs answer in one conversation and check each other’s work.
Then True North, a layer of AI Anti-Hallucinogen and an independent AI fact checker, additionally checks the claims that carry risk against live sources and corrects the answer before it reaches your work.
7 days free trial, no credit card, no True North.
* Median for new models from six major labs, July to September 2026: how often a model gives a wrong answer instead of saying it doesn’t know (Artificial Analysis AA-Omniscience). See the full data
An invented statistic. A quote nobody said. A source that doesn’t exist. One AI can deliver all three with the same confidence as the truth, leaving you to catch the mistake. In Suprmind, four other AIs are already in the room, ready to challenge the answer and correct what one gets wrong.
The Suprmind AI Anti-Hallucinogen is a two-layer system that fights AI hallucinations. Layer one is the multi-AI conversation itself. Layer two works outside it, because no AI should grade its own homework.
Live on every plan
Five frontier AIs answer in the same conversation and read each other’s answers. They were trained on different data, by different companies, and they’re wrong about different things.
When one states something false, the next can call it out, replace it with the right fact and rebuild the answer from there. You watch it happen. On Pro and up, DCI shows the contradictions and corrections right under the messages.
Pro, Frontier, Power and Enterprise
Some errors get past any reader. Nobody notices the wrong date, or every model learned the same outdated fact. True North works outside the five, so it doesn’t care who agreed with whom.
It picks the claims that carry risk, researches them against live sources, and a separate judge rules on each one. When the evidence says a claim is wrong, True North corrects it in the conversation and in your notes, before it reaches your work.
What AI hallucinations costs you
A judge, when the brief cites a case that doesn’t exist.
A client, when the number in the deck traces back to nothing.
A reviewer, when the citation in your paper leads nowhere.
55.2%
Median hallucination rate of new models from six major labs, July to September 2026. Without the right answer, they make one up more often than they say they don’t know.
Artificial Analysis AA-Omniscience
7 of 14
New models from those labs that hallucinate more than the model they replaced. All 7 also get more answers right.
Artificial Analysis AA-Omniscience
2,100+
Court decisions worldwide where a party relied on AI-hallucinated material. About five new ones a day in 2026.
Damien Charlotin, AI Hallucination Cases database
17-33%
Queries that legal research tools sold as hallucination-free answered wrongly, or backed with a source that doesn’t support the answer.
Stanford RegLab and HAI, 2023-24 tool versions
None of these needed a smarter AI. They needed someone to check it.
The answer goes straight from the model to you. There is no second opinion in the chat, so a made-up fact reads exactly like a real one.
You get several answers in separate panels. The models never read each other, so comparing them is your job. And when they agree, they can all be wrong together.
The AIs read each other’s answers and call out what doesn’t hold. Then True North checks the claims that carry risk against live sources.
We re-checked 17,885 real questions asked on Suprmind between July 30 and September 10, 2026, with model names hidden and answers in random order. Judges from OpenAI, Anthropic and Google tested the key findings.
At least one answer was judged corrected by another model. In a single-AI chat, there is no other model to make it.
Drew a correction, against 28% of low-stakes ones. The more it matters, the harder they push.
Questions where no model added, corrected or contradicted anything: 32 of 13,563.
Fact-checks where the correcting model was right, when two judges from different companies agreed. On facts that don’t change: 10 of 10.
A judge’s reading is not proof, and judges from different companies read the same answers differently. Every number here comes with its method.
Read the Multi-Model AI Divergence Index and its methodology. Window: July 30 to September 10, 2026.
A user uploaded two books and asked Grok to find a specific passage. Grok answered with confidence. Claude checked.
The Test
The user gave Grok a verifiable task: find a sentence in an uploaded novel and continue the paragraph after it.
“…it was clear that they were not being moved on for strategic reasons – but”
Continue from here. The paragraph should pop up.
Grok
FabricatedGrok produced a fluent, confident paragraph of Warhammer prose. It referenced characters, locations, and themes from the books. It read like a direct quote.
It wasn’t in the book. Grok wrote it and presented it as retrieved text.
Claude
CaughtClaude ran 8 verification searches. Zero results. Then identified four tells proving fabrication: referencing the conversation’s own framework, generic phrasing, no page reference, and blended quote and interpretation.
Claude’s conclusion: “Silent confabulation dressed up as sourced data.”
This is a real conversation from a real Suprmind session. One AI fabricated. Another caught it, in the same thread, in front of the user.
With a single AI, you’d have a confident wrong answer and no reason to question it.
Why True North exists
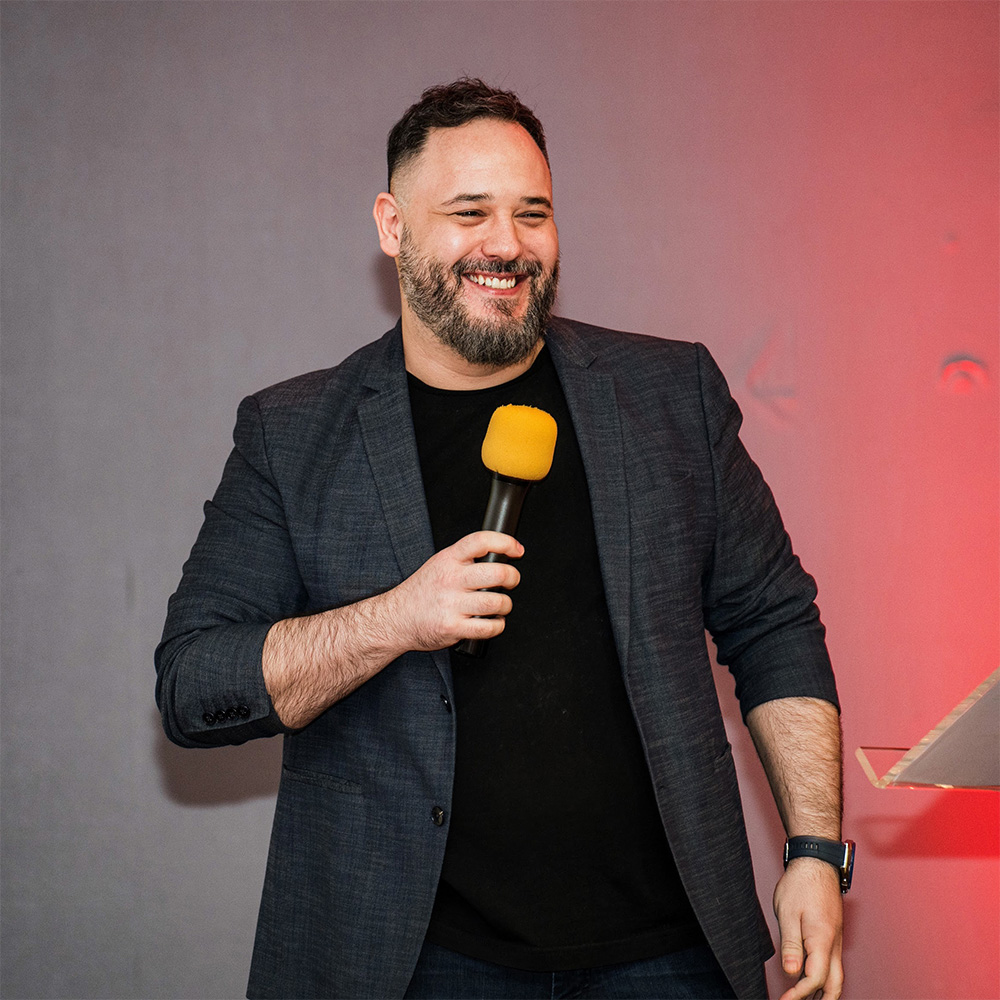
Gemini once wrote our own domain as suprmind.com. The other four AIs read it and adopted it without a word, on a product that lives at suprmind.ai. Five frontier models, all agreeing, all wrong, about my own company. If you’ve ever checked one AI with another and relaxed because the answers matched, that’s the same trap. That thread is why True North exists: when the AIs agree, evidence still gets a vote.
Radomir Basta
Founder & CEO, Suprmind
True North works in the background after each answer, while the conversation keeps going. You don’t switch tools, paste anything or remember to run it.
Every check is one claim, the evidence behind it and a ruling you can read. The original claim and the ruling stay in an audit trail, so you can always see what changed and why.
The AIs that wrote the answer never rule on it. A separate researcher gathers the evidence, and a separate judge decides.
Where a wrong answer costs money
Legal filings, financial models, research and client deliverables. The work where one confident wrong answer costs more than the time it saved. The previews below are illustrative.
Legal
A filing that cites a case nobody can find is how sanctions start. Five AIs read the citations before you rely on them, and True North checks them against live sources.
How legal teams use itRecommendation
Two of the nine cited cases can’t be found in any source. Remove them, cite the appellate holding instead, then file.
Finance
One wrong growth rate changes the valuation, and the deck still looks perfect. The AIs recheck each other’s math, and True North checks the figures behind it.
How analysts use itThe model assumes 40% growth for five years. Last year’s actual was 18%.
At 18%, the valuation falls by more than half. Rebuild the base case before the meeting.
The filings you shared show 12% to 20% sector growth over the last three years.
Research
A citation can be real and still not support the claim. Grok once caught Perplexity handing us statistics about human hallucinations for a report on AI ones.
How researchers use itSuprmind Pro
Five AIs and True North
$45/mo
Client work
Your deliverable goes out under your name, not the AI’s. Run the draft past five AIs and True North first, and send the version that survived.
How consultants use itEvery mode puts several AIs on the same question. What changes is how they work on it: one after another, all at once, in a debate, against your plan, as a research pipeline or from first principles.
Each AI reads every answer before it and challenges what doesn’t hold.
Best for:
Research, analysis and anything with numbers in it
All five answer independently and at the same time, then one answer merges them with the agreements and contradictions marked.
Best for:
Fast fact checks
Opening statements, direct rebuttals, then a separate moderator rules. Minority opinions stay on the record.
Best for:
Claims you want argued from both sides
Five AIs attack your plan across six vectors and hand you an exportable risk dossier.
Best for:
Anything you’re about to put money behind
A five-stage research pipeline with a dedicated fact-check stage before synthesis. Available on Enterprise.
Best for:
Long, cited reports
Each model names its assumptions, then rebuilds the answer from the ground up.
Best for:
Questions where the usual answer might be wrong
Use an @mention for one AI, then bring the team back when you need it. Check the plan comparison for model access, modes and usage limits.
Turn the discussion into a decision brief. Review the recommendation, disagreements, risks and unresolved questions before choosing your next move.
Create a brief, strategy memo or research report from the conversation. Choose a template included in your plan, review the result and export it.
“We are using Suprmind primarily for new clients’ strategy development and QA of all of important deliverables before they are sent to our clients. Catching and correcting errors before clients see them saves us a lot of unnecessary drama and stress.”
Co-founder, Miss Amara
“I started using it for competitor research and it just kept expanding – new markets, risk reviews, compliance docs. Five different angles on the same question catches things I would have missed.”
CEO & Co-founder, Miss Amara
“On a company level team is using Suprmind for due diligence of new clients and partners, as well as for finding resolutions to escalated contract fulfillment challenges. Five AIs in Super Mind mode tend to pick up all fine small-letter contact legalities that were until now often missed by popular AI platforms.”
Founder and CEO, FourWinds
“For analyzing business plans and evaluating client processes, the depth you get from five models reading each other is genuinely different. The Master Document export with custom prompt alone saves me hours on final reports.”
Senior International Adviser, EBRD – European Bank for Reconstruction and Development
Zero hallucinations. No platform built on today’s AI models eliminates them, and any page that tells you otherwise is selling. We fight them. We don’t pretend they’re gone.
That five AIs agreeing makes it true. Agreement can come from shared training data. That’s why True North checks evidence, not votes.
A ruling on everything. When the evidence is thin, True North marks the claim unverifiable. It doesn’t guess, and it doesn’t call a claim false because it couldn’t confirm it.
To decide for you. You still make the call. You make it with the fight already fought.
Five frontier AIs in one conversation, with True North behind them. Bring the question you’d normally trust one AI with, and keep the answer that survives.
Spark trial: four AIs, 7 days free, no credit card, then $19 a month. Pro: all five AIs and True North, $45 a month.
Questions
Not on purpose. An AI model has no idea when it’s wrong. It predicts the most likely next words, so when it doesn’t know the answer, it can produce a fluent, confident one that’s false. That’s a hallucination, and it reads exactly like a correct answer: same tone, same certainty, sometimes with a citation attached. The real problem is that nothing in a single-AI chat contradicts it. In Suprmind, four other AIs read the answer before you act on it, and any of them can call it out. True North then checks the claims that carry risk against live sources, so a made-up number has to get past four other AIs and an independent judge before it reaches your work.
No. No tool does, and any tool that claims to is selling. Hallucinations come from how language models work, so every model makes things up sometimes, including the newest ones. What Suprmind changes is what happens next. In a single-AI chat, a hallucination goes straight to you. In Suprmind, it lands in a conversation with four other AIs that read it and can correct it, then True North checks the risky claims against evidence and fixes what the evidence contradicts. Fewer wrong answers reach your work, and you can see every correction made along the way.
The Suprmind AI Anti-Hallucinogen is a two-layer system that fights AI hallucinations. Layer one is the conversation itself: five frontier AIs answer in one thread and read each other’s answers, so a wrong claim can be called out and replaced on the spot. Layer two is True North, an independent fact checker that works outside the five. It picks the claims that carry risk, researches them against live sources, has a separate judge rule on each one, and corrects the conversation and your notes when the evidence contradicts a claim. The name is coined on purpose: an Anti-Hallucinogen for AI.
In two tabs, the models never read each other. You do the comparing, and you only catch what you happen to notice. When the two answers match, it feels like proof. It isn’t, because two models can share the same outdated fact or the same gap in their training. In Suprmind, five AIs work in one conversation and read each other’s answers, so a later model can correct an earlier one while you watch. True North then checks the claims that carry risk against evidence, not against how many models agreed. You stop being the person who has to spot the difference between five answers.
The claims that carry risk: numbers, dates, names, citations, and legal, financial and scientific statements. After each answer, True North reads it and picks the claims worth checking, whether or not another AI disputed them. Its biggest value is often where nobody disagreed. It doesn’t check every sentence. Opinions, advice and reasoning aren’t facts it can look up, and the AIs handle those by arguing them out. Each selected claim is researched against live sources, and a separate judge rules it supported, contradicted or unverifiable. That makes True North an AI fact checker inside the conversation, not a separate tool you have to remember to use.
Three things. First, you see it: the ruling appears in the conversation with the evidence True North used. Second, the answer gets fixed: the correction goes back into the conversation, so the next AI reads the right fact instead of building on the wrong one. Third, it stays fixed: the wrong fact is replaced in Scribe’s notes and the project’s memory, so it doesn’t come back in a later conversation or end up in your Master Document. The original claim and the ruling stay in an audit trail. True North acts on clear contradictions. When the evidence is thin, it says so instead of guessing.
It happens, and it’s the case True North is built for. Five models can share the same outdated source or the same gap in their training, and their agreement looks like proof when it isn’t. True North doesn’t count votes. It takes the claim outside the conversation, gathers evidence and hands it to a separate judge, so a fact the whole room accepted still has to survive a check against live sources. If the evidence contradicts it, the correction goes into the conversation no matter how many AIs agreed.
It depends on the test. One model leads on hard knowledge questions, another on summarizing documents, another on citations, and a lab’s newest release sometimes hallucinates more than the model it replaced. No model wins every column. We keep a running comparison on our lowest-hallucination AI page. The practical answer is not to bet on one. Suprmind puts five frontier AIs in the same conversation, so when the model that’s strongest at one task is weak at yours, the others are there to catch it.
True North runs on Pro, Frontier, Power and Enterprise. Layer one, AIs checking each other in one conversation, is part of every plan. Spark, the entry plan, runs four AIs (GPT, Claude, Gemini and Grok) with layer one and without True North, and it’s the plan the 7-day free trial uses. Pro is $45 a month and adds Perplexity, True North, Debate, Red Team, First Principles and DCI, which shows the contradictions and corrections under the messages. Every plan is on the pricing page.
No. Suprmind doesn’t train AI models on your chats. Your conversations run on servers in Germany and Finland, and the database sits in Switzerland, so your data stays in the EU and Switzerland. Payments go through FastSpring, which holds the certifications that payment processing requires.
Five is smarter than one.
Five AIs keep each other honest. Evidence keeps all five honest.


